❌

Visualização normal

Antes de ontemCybersecurity Blog | SentinelOne
  • ✇Cybersecurity Blog | SentinelOne
  • Building Agents Backwards from Evaluation Carter Church
    Executive SummaryEvaluating a security agent begins with defining the work it should perform and the evidence required to consider that work complete and accurate. Domain experts establish reference answers and grading criteria. A successful approach must combine evaluations of complete runs alongside tests of individual competencies to both demonstrate whether a system is useful and help engineers identify what exactly to improve.Every material change to a model, prompt, tool, or workflow needs
     

Building Agents Backwards from Evaluation

28 de Setembro de 2026, 21:00

Executive Summary

  • Evaluating a security agent begins with defining the work it should perform and the evidence required to consider that work complete and accurate. Domain experts establish reference answers and grading criteria. 
  • A successful approach must combine evaluations of complete runs alongside tests of individual competencies to both demonstrate whether a system is useful and help engineers identify what exactly to improve.
  • Every material change to a model, prompt, tool, or workflow needs a measured comparison with the previous system. Operational failures supply new test cases, and fresh cases test whether improvements generalize.

In Part 1 of LLMs in the SOC, SentinelLABS examined the gap between cybersecurity benchmark scores and operational usefulness. In the months that have followed, we’ve observed those same design gaps in the flood of agentic systems hitting the market. This fail-fast development trend treats evaluation as a process that emerges after the proof-of-concept. In other words, teams build the system, demonstrate that it can work, and defer the harder task of establishing how reliably it performs and where it fails for a later date. 

This makes sense in the new world of rapid prototyping and AI experimentation. However, these systems are often brittle or only work until something in the environment changes or fails to generalize. This raises the urgent question, "How do I fix or improve this one behavior?" inside of a monolithic, non-deterministic pipeline.

For a system that will support security decisions, we believe the most important design choice is to make its performance measurable from the start. That means building the agent so that engineers can identify where an investigation goes wrong, test a correction, and verify that the change improves the complete workflow.

Consider a grounded example: an investigation agent that reviews an alert, queries the SIEM, and returns a verdict that matches an experienced analyst's. That looks like a success. On closer inspection, however, the query used the wrong device identifier and retrieved unrelated events. The verdict may be correct, but the records gathered during the investigation do not support the decision.

How would the team building that agent discover the mistake? And after fixing it, how would they know that the next model or harness update had not brought it back?

Start With the Work the Agent Should Complete

When building agents, attention often goes to the visible machinery: which model, which prompts, which tools, and so on. Those matter, but they're also some of the easier parts to modify. The part that's hardest to retrofit is the ability to answer two questions: is the system effective? And if not, what exactly do I change to make it better?

The industry has converged on this from several directions. Frontier lab engineering guidance observes that teams get surprisingly far on manual testing and intuition, but once an agent is in production, building without evaluations breaks down. Users report that the agent "feels worse" after a change, engineering scrambles to find out whether the claim has any validity, and it becomes difficult to tell real regressions from noise or to test changes against realistic scenarios before shipping [2]. For some the answer is what they label eval-driven development, scoped tests at every stage, before and during implementation, the way test-driven development writes tests before the code exists [3].

What that guidance usually leaves implicit is that evaluation discipline is an architectural decision. If you want to measure components individually with rigor, the agent has to be built out of individually exercisable competencies.

Before we choose a model or write a prompt, we need to define the work we expect the agent to do. For an investigation agent, that means reviewing an alert, gathering the evidence needed to understand what happened, and reaching a conclusion that the evidence supports. When it cannot resolve the case, it should give an analyst a clear account of what it found and what still needs investigation.

On Evaluations

"The first principle is that you must not fool yourself, and you are the easiest person to fool." – Richard Feynman

An evaluation is a way to measure a model's performance against a given scenario. More formally, every evaluation decomposes into a task (the point of indecision the system must reason through), a scenario (the environment wrapped around that task), and rubrics (how completion gets judged). This may seem simple on the surface, but LLM evaluations are an emerging discipline that every industry is struggling with. As the Pydantic team puts it, "Anyone who claims to know exactly how your evals should be defined can safely be ignored" [4]. A good eval set asks "what will a team use this for?" and ensures that the system gives them sufficient answers, and that it does so consistently.

End-to-End Evaluation: Does the System Perform?

An end-to-end evaluation runs the whole system on a realistic workload with grades as the final outcome. For an investigation agent, the natural frame is the human baseline it augments. A SOC analyst starts the day with a queue. Over a shift they work some number of alerts, dispositioning them into buckets (benign, suspicious, escalate, respond), and they end the day with a measurable amount of work left over. One metric that matches is burndown: of everything the system started with, how much still needs human attention? Alongside it sit the metrics that keep this burndown honest, such as disposition accuracy versus expert ground truth, time-to-verdict, stability, consistency, and cost per alert.

End-to-end metrics like these are often seen as the only metrics that matter. They tell a compelling story, they demonstrate that a system is worth building, and they're exactly the narrative that users want to hear. They also catch emergent failures such as compounding errors, context loss, and mis-sequenced steps that only show up when every component runs together against realistic inputs [2,6].

However, end-to-end metrics can aggregate away the information an engineer needs. When the overall performance is bad, or when it degrades after a change, it doesn’t provide any context about what went wrong. A regression in burndown could indicate one of many problems, meanwhile, all we can measure here is that suddenly we aren't performing. In a monolithic system, the only answer is to start reading traces and hunting for sources of failure.

Competency Evaluation: What Exactly Do We Fix?

To tackle that question we use the competency evaluation (elsewhere called component-level [6]). A competency evaluation isolates one skill and tests it directly, with its own specific inputs, definition of success, and a wide variety of different cases. These evaluations are helpful because they tell you whether a single part of a larger system is functional and capable across many scenarios. The inverse is also true, which is to say that it tells you which exact skills are underperforming.

End-to-End and Competency Evaluations: What Each Reveals


End-to-end evaluation

Competency evaluation

Question answered

Does the system deliver value?

Which capability is weak, and how?

Unit under test

The whole system on realistic workloads

One severable skill in isolation

Example metric

Alert burndown, disposition accuracy, escalation precision

Query correctness rate against a specific source's schema

Primary audience

Leadership and the teams relying on the system

The engineers improving the system

Detects

Emergent, compounding, integration failures

Localized skill deficits, regressions in one capability

Fails to provide

Any indication of what to change

Assurance that the assembled whole works

A mature program runs both continuously, and many teams add additional layers. For example, trajectory or trace evaluation, which grades the path the agent took rather than only the endpoints [2,6]. These evaluations are also critical, but this article specifically serves to spotlight the two defined above.

A Real-World Example

Take our Purple AI® Agentic Investigation agent as an example. When invoked, the system runs the investigation in the same way an analyst would. It pulls the surrounding evidence for an alert, enriches that evidence with additional data, forms and submits queries against the organizations telemetry, reasons over what comes back, and lands a verdict with the findings to support it. The tempting way to grade that answer is obvious, does the verdict match what an expert would have decided?

Very tempting, and also very dangerous. Suppose an agent agrees with the expert 95% of the time. That sounds strong, but the agent could just be pattern-matching on alert characteristics instead of actually retrieving evidence and building intermediate conclusions. A correct verdict reached for the wrong reasons is a failure, and only having a verdict-level score doesn’t tell us how we arrived at a conclusion. This is the same blind spot SentinelLABS identified in Part 1 - the unit of evaluation was more than often the answer to a question, as opposed to the path taken to reach it.

Decomposing the Problem

So, how do you evaluate competencies in this example? Start from the job you're trying to solve and decompose. On inspection, investigation hinges on many competencies. The agent has to form hypotheses worth testing given alert data and state from previous steps. It has to translate those hypotheses into correct and efficient queries against each data source, and it has to understand the schema of that source and what the fields it's filtering on actually mean. It has to interpret result sets, pick the next pivot, and know when the evidence is sufficient to stop. 

Each of these is a distinct competency that may be evaluated on its own. 

An (extremely abbreviated) tree:

Investigation 

├─ Hypothesis generation

├─ SIEM query construction (per-source eval suites)

├─ Investigation efficiency (tool-call budget)

├─ Adherence to organizational policy

├─ Confidence & evidence sufficiency judgment

└─ etc.

Now our evaluations can become concrete. "SIEM query construction" means many cases, each specifying an investigative intent, a target data source, and ground truth for what a correct query returns, graded automatically by running the query against representative data and comparing results, and backed by experts who wrote their own queries for the same asks.

For example, consider the device-ID failure we mentioned above. A competency case could give the agent an alert with a device ID and ask it to retrieve the related authentication events from a representative SIEM dataset. The case already defines which events a correct query should return.

If the agent queries the wrong identifier, it fails the case. The query may run successfully and return plausible data, but it does not return the expected events. This turns a failure that was previously hidden inside a successful investigation into something the team can measure directly.

Once the team fixes the problem, the case stays in the evaluation suite to ensure future changes to the system are consistently measured.

Even just a few dozen well-chosen evaluations per capability, drawn from real failures, can provide a strong initial signal. Each of these competencies gets its own suite since we know they are areas where models may struggle.

Where to Invest Evaluation Effort First

Not every node in the tree deserves equal attention. When setting up your own evaluations we suggest asking two questions:

Is this actually hard for models? Some competencies are commodities today. Summarization is the canonical example. Modern LLMs summarize nearly anything competently and the difference between a good and a great summary rarely moves outcomes. Contrast that with SIEM query construction, a real technical hurdle, with objective failure (the query is wrong, slow, or returns the wrong rows), high downstream impact (a bad query corrupts the whole investigation), and known model weakness on dialect and schema-specific syntax. An area that exhibits similar challenges is where your evaluation cases should go.

Can you define a defensible standard? Some competencies rely on direct checks against known facts, while others require expert judgement about whether an agent’s decision was justified by the evidence available. Evaluation effort pays off where success is decidable. Query construction has crisp ground truth (run it, compare results). Evidence-sufficiency judgment is softer, but experts mostly agree on clear cases, so a rubric plus expert-labeled examples works. Where even experts can't agree what "good" means, an eval suite just encodes noise. Before evaluating, you must first have a clear definition of success [10,11].

A useful heuristic is to simply combine the two and prioritize competencies by impact of failure × probability of model failure × decidability of ground truth. Wherever possible, look to grade binary pass/fail per case instead of arbitrary quality scores as binary judgments are easier for experts to make consistently, easier to trend, and harder to argue with [10]. If your system is already in the wild, you can still build cases - but we recommend you prioritize observed failures over successes [2,3].

impact_of_failure_equation.jpg

The Value of Domain Expertise

Every competency evaluation needs to answer the question "what does good look like?" The person who can say whether a generated query succeeded (not just executed, but "all things considered, this is equal to or better than what I would have written in my day job") is the person who writes those queries well.

This is why many companies are spending heavily on contracted expert annotators. They're buying, at market rates and arm's length, the domain judgment that their evaluations require. In reality, most AI engineers are not domain experts, and many teams building agents don't have these resources in abundance. This is where being a company of cyber professionals is our advantage: for nearly any skill a security agent needs, someone here already performs it at an expert level daily. That expertise is the standard every one of our evaluations is built against.

When you identify a competency, identify its experts, understand how the work actually functions, and co-author cases with them. Evaluations built this way are true to real life, benefiting generalization when it reaches the field as it was tested against reality rather than the builder's imagination of what the field might look like.

Prove It Before Production

A well-built competency tree carries a risk because it makes the evaluation effort feel finished. However, evaluation is a constant game of discovering scenarios, hill climbing performance, and monitoring for regressions. Inside SentinelOne®, once an agent has been well-evaluated, it earns the chance to prove itself alongside real security work. 

At this stage, we actively execute solutions in parallel with working analysts in our internal SOC and Wayfinder Managed Services teams. When runs are flagged for review, an expert re-investigates the alert from scratch and establishes ground truth before reading the agent's verdict, so the reference standard can never be anchored by the machine it's meant to judge. 

Every interesting divergence becomes a new case, and every fix then has to beat the case that motivated it while not regressing against the larger suite. Only after our internal teams have thoroughly vetted an agentic offering in production does it reach anyone outside SentinelOne.

Underneath all of this effort sits one standard: in security response, unmeasurable capability is unshippable capability. An agent that cannot demonstrate exactly where it is weak cannot be trusted where it is strong. Autonomy in a SOC must be earned competency by competency, evaluation by evaluation, and finally in production, in front of the people who do the job.

References

[1] G. Bernadett-Shapiro and E. Garcia Lazo. LLMs in the SOC (Part 1) | Why Benchmarks Fail Security Operations Teams. SentinelLABS, January 2026.

[2] Anthropic. Demystifying Evals for AI Agents. Anthropic Engineering, January 2026.

[3] OpenAI. Evaluation Best Practices. OpenAI API Documentation.

[4] Pydantic. Pydantic Evals. Pydantic AI Documentation.

[5] OpenAI. Advancing the Price-Performance Frontier with GPT-5.6. OpenAI, July 2026.

[6] Confident AI. LLM Agent Evaluation Metrics: Tool Calling, Task Completion, Reasoning, and Trace-Based Evals. Confident AI, 2026.

[7] R. Aleithan et al. SWE-Bench+: Enhanced Coding Benchmark for LLMs. arXiv:2410.06992, 2024.

[8] Anthropic. Writing Effective Tools for AI Agents — Using AI Agents. Anthropic Engineering, 2025.

[9] Anthropic. Building Effective AI Agents. Anthropic Research, December 2024.

[10] H. Husain. Your AI Product Needs Evals. hamel.dev, 2024.

[11] A. Szymanski et al. Limitations of the LLM-as-a-Judge Approach for Evaluating LLM Outputs in Expert Knowledge Tasks. Proceedings of the 30th International Conference on Intelligent User Interfaces (IUI), 2025.

Third Party Disclaimer:

All third-party product names, logos, and brands mentioned in this publication are the property of their respective owners and are for identification purposes only. Use of these names, logos, and brands does not imply affiliation, endorsement, sponsorship, or association with the third-party.
The Path to the Autonomous SOC: The Early Returns of AI & What It Means for Cybersecurity

25 de Agosto de 2026, 12:12

The question has shifted. Security leaders spent several years debating whether AI would reshape security operations. That debate has settled. Now the conversation is about pace. How fast can the foundation be built, and what do organizations that moved early have to show for it?

For the second year, SentinelOne® commissioned 451 Research to survey 611 North American cybersecurity decision-makers and practitioners on the state of security operations strategy. The results confirm what we’ve been building toward, and they surface a finding that should recalibrate how most security leaders sequence their AI investments.

The Returns Didn’t Wait for the Roadmap

Many product roadmaps assume a clear sequence and start with building toward higher maturity first with returns following. The data shows that AI is running ahead of schedule.

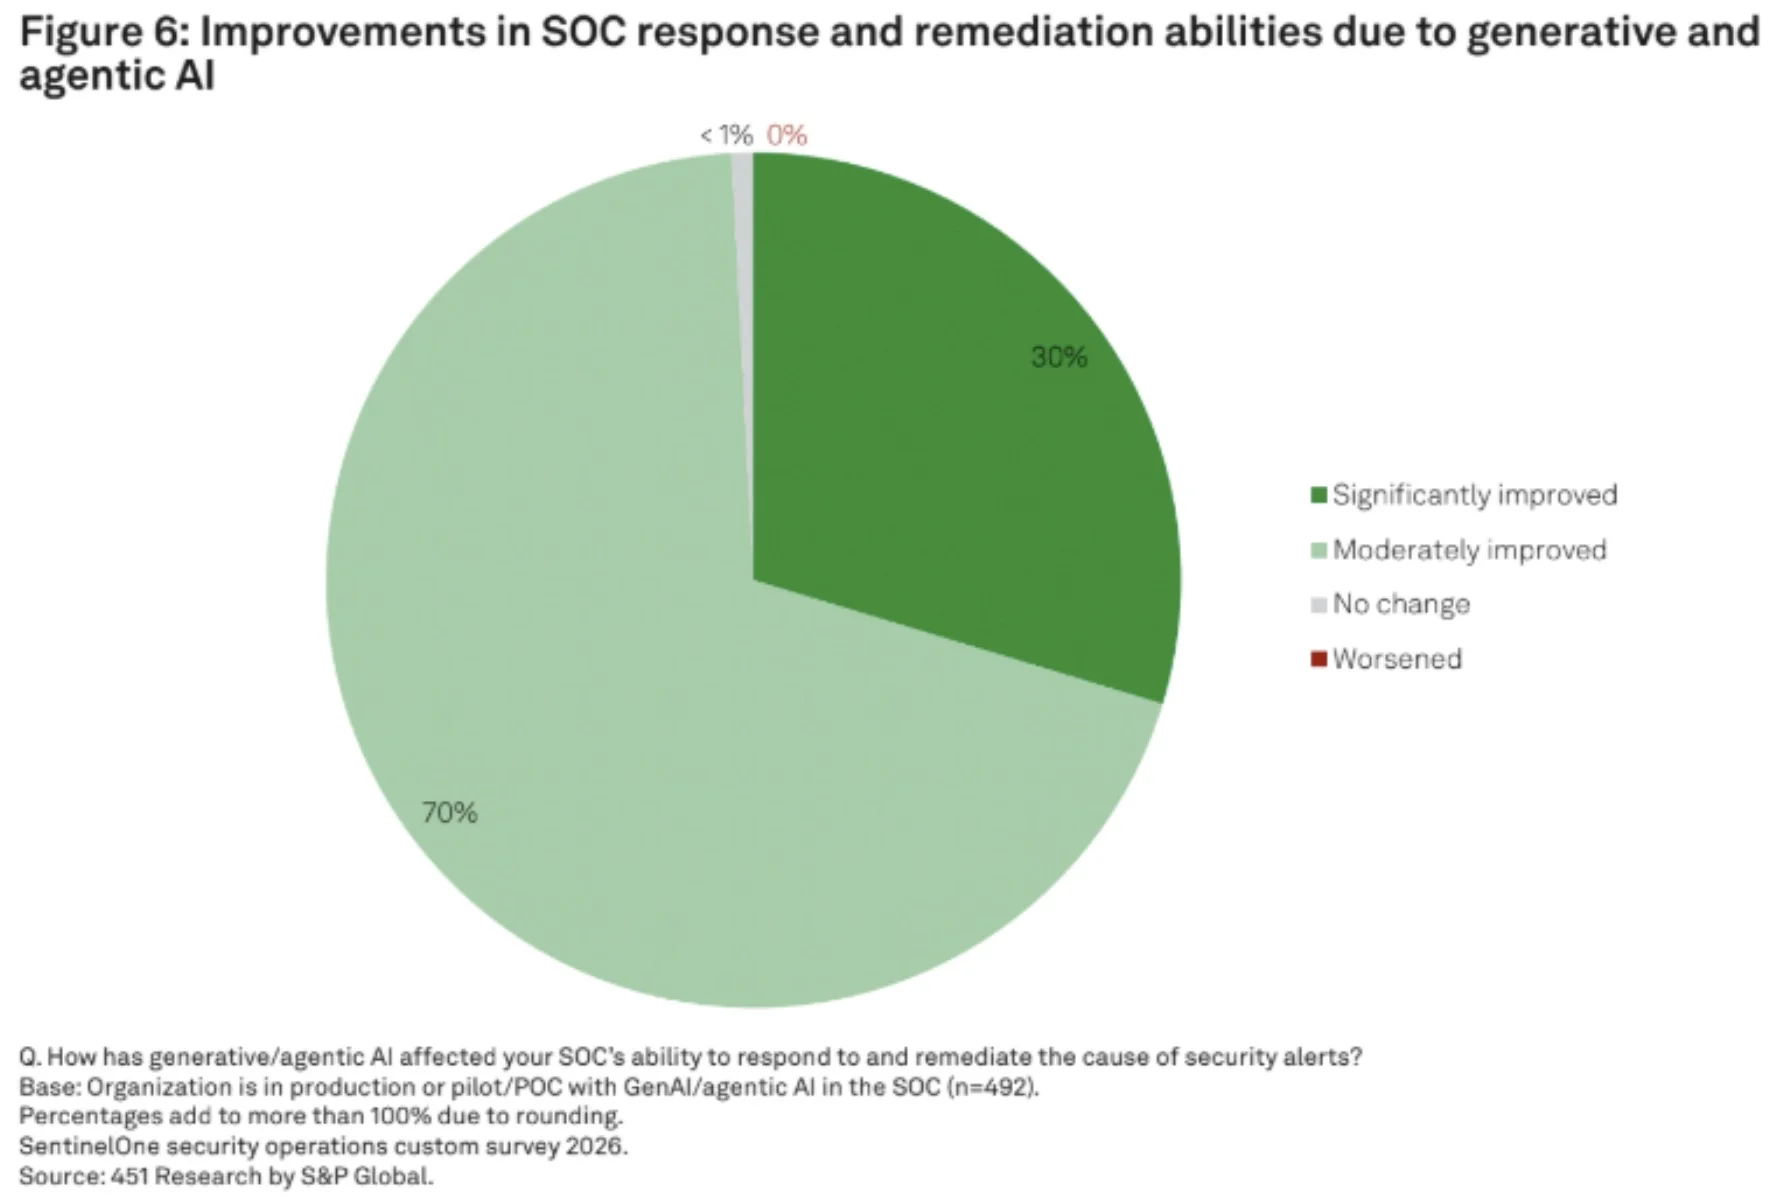
Nearly all organizations surveyed (96%) are still operating AI at the earliest maturity levels:

  • Level 1: Basic monitoring; triage specialist/alert analyst
  • Level 2: More senior triage analyst / basic incident responder and investigator

By most measures, AI adoption in the SOC is still early. And yet, 99% of those same organizations already report improvements in incident response and remediation.

The numbers are consistent. Early-stage AI (chatbots handling initial alert triage, automated tools sorting true positives from noise) is delivering before organizations reach advanced maturity. The gap between where most organizations are and what they are already getting is real and consistent across survey respondents.

Organizations waiting for higher AI maturity before building the supporting infrastructure are running the sequence backward. The returns are available now. The foundation built today determines how far those returns scale.

Platformization Has Reached A Verdict

The organizations accelerating AI adoption are also the ones consolidating onto platforms. A platform-oriented security architecture means moving from siloed, specialized tools to an integrated stack built on a foundation that coordinated AI decision-making can actually run on, and one that lets each new capability compound on the last.

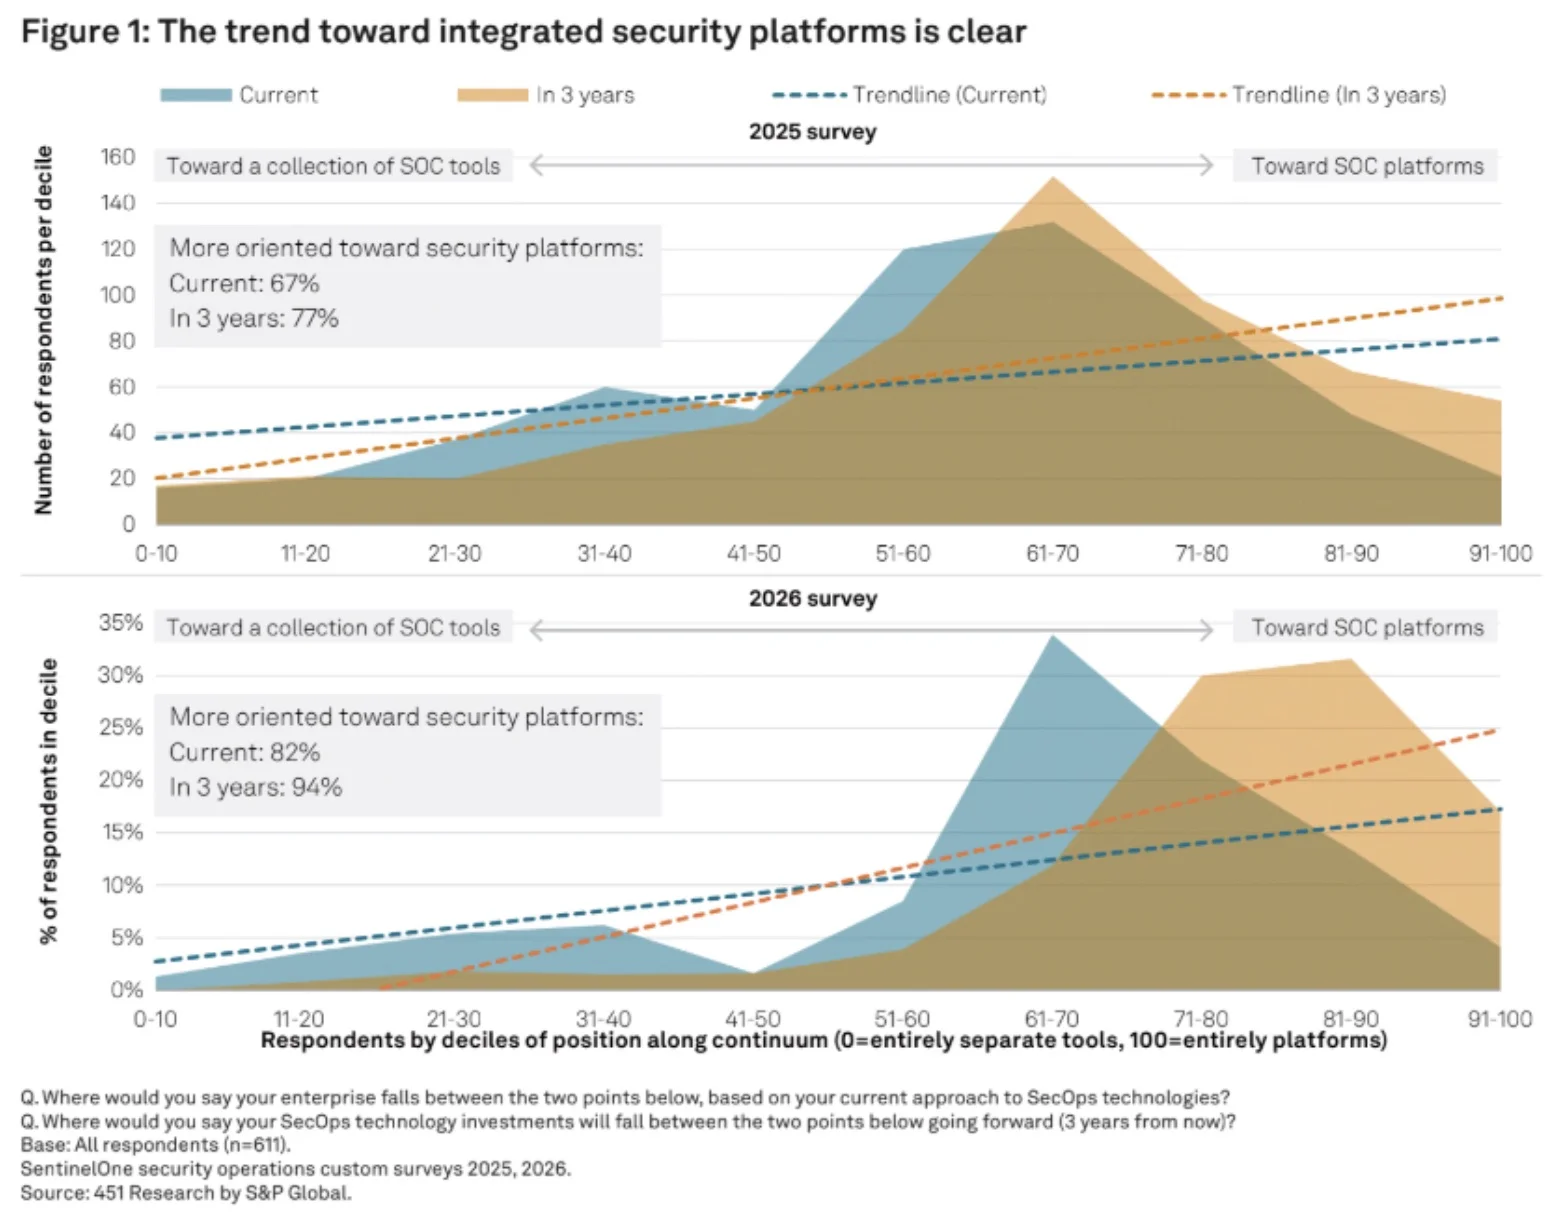
The platformization numbers from this year’s survey are clear. 82% of organizations describe themselves as platform-oriented, a 13-point jump in a single year, and 94% expect to be there within three years.

A common assumption is that platform adoption means replacing specialized tools. The data complicates that picture. The same technologies most frequently deployed as standalone tools (EDR, SIEM, CNAPP) are also the top anchors for integrated platforms. Organizations typically start with one of these and expand outward. What changes is the common data layer that enables coordinated AI decision-making, serving as the connective tissue underneath.

Platformization is not coincidental with AI’s emergence. Agentic AI needs connected, continuously updated data to accurately reason across signals and take autonomous action. Fragmented architectures, where telemetry is siloed and pipelines require manual effort, cannot support AI-driven SOC operations at scale. Platform adoption and AI adoption are converging because AI’s data requirements have made integration a structural necessity.

The survey makes the infrastructure connection an explicit one. The top-cited benefit of investing in a data lake for SecOps is supporting AI-driven SOC workloads and agents. Organizations that built the data foundation early have already cleared the barrier stalling others. Those who haven’t, face a prerequisite gap, and the distance is widening rapidly. Architectural readiness is the variable that determines how far AI investments can scale.

Job Satisfaction Is Rising

Every discussion of AI in the SOC centers on detection and response metrics. This report has those too, but there is a finding that security leaders managing attrition should weigh: analyst burnout is declining.

As AI handles repetitive, high-volume triage work, analysts report rising job satisfaction. The role is shifting away from processing an endless queue and toward investigation, threat hunting, and judgment-intensive work. In a market where SOC analyst turnover remains a persistent operational cost, that shift carries real dollar value.

The analyst role evolves, becoming more strategic and more consequential.

A New Attack Surface

The same AI systems changing how SOCs operate are also creating new targets. Adversaries are already probing AI infrastructure including agents, data pipelines, model endpoints, and the governance gaps that emerge when controls lag behind adoption. The report surfaces this tension clearly: Organizations are deploying AI faster than they are securing it.

An AI agent with misconfigured access or an unmonitored data pipeline is an exposure. Securing the AI infrastructure that powers the SOC is happening alongside deployment, whether organizations have planned for it or not. Those without a clear governance posture are accepting risk that may not be priced into their AI investment case.

The potential of GenAI and agentic AI in the SOC is already being realized. The organizations that capture it fully are those building governance alongside deployment. The platform that runs the Autonomous SOC and the platform that secures it are, increasingly, the same platform.

SentinelOne’s Vision: The Autonomous SOC

Everything the report surfaces, from AI returns arriving before maturity to platform consolidation to the improving analyst experience, points to how these are expressions of the same shift. The foundation that enables early AI returns is the same one that determines how far those returns scale, how capable analysts become, and how well the security of AI itself is governed.

The findings align with how SentinelOne has defined the path to autonomous security operations: A progression from AI-assisted triage at early maturity levels to increasingly autonomous investigation, threat hunting, and response, with humans in strategic and governing roles. The report validates that the market is moving through exactly that sequence. Organizations that understand the architecture behind it (the platform integration, the common data layer, the governance controls) are positioning themselves to capture returns at every stage rather than waiting for the destination.

The full 451 Research report goes further into detail, covering what progression looks like at each maturity level, the specific barriers organizations are encountering, and the data behind each finding in full.

Read the full 451 Research report to learn more about how AI is reshaping cybersecurity.

Third-Party & Intellectual Property Disclaimers

All third-party product names, logos, and brands mentioned in this publication are the property of their respective owners and are for identification purposes only. Use of these names, logos, and brands does not imply affiliation, endorsement, sponsorship, or association with the third party.

This blog may include discussion of unreleased services or features. Any unreleased services or features referenced here are still in development and subject to change. Customers should make their purchase decisions based upon features that are currently available.

  • ✇Cybersecurity Blog | SentinelOne
  • The Agentic SOC: Transforming Data into Defensive Velocity SentinelOne
    Security Operations Centers (SOCs) are currently confronting scalability challenges on two fronts: structural and cognitive. The day-to-day reality of modern defensive operations is stark: an analyst frequently begins a shift facing a queue deeply saturated with unvetted alerts. To process a single event, the analyst must open the alert, pivot to a secondary console to complete an investigation, manually enrich an IP address, copy a file hash into a third interface, and cross-reference an asset
     

The Agentic SOC: Transforming Data into Defensive Velocity

20 de Julho de 2026, 10:00

Security Operations Centers (SOCs) are currently confronting scalability challenges on two fronts: structural and cognitive. The day-to-day reality of modern defensive operations is stark: an analyst frequently begins a shift facing a queue deeply saturated with unvetted alerts. To process a single event, the analyst must open the alert, pivot to a secondary console to complete an investigation, manually enrich an IP address, copy a file hash into a third interface, and cross-reference an asset inventory that may not have been updated in months. Following this, they must author and refine queries, waiting for overloaded databases to return historical context.

The actual work of assessing the investigation’s results and moving to decision-making and action has not even begun. This is the administrative burden of the modern SOC. The true threats are not just those that attempt to bypass defenses, but the critical operational hours lost before an active mitigation attempt is even initiated. While analysts are highly trained professionals, the relentless requirement to perform manual data aggregation inevitably leads to exhaustion.

Misdiagnosing the Bottleneck: The Upstream Data Problem

Threat actors operate at machine speed, utilizing automation to pivot laterally across networks in a matter of seconds, frequently disappearing before defensive teams can even log into their terminals. Expecting human defenders to counter automated threat vectors by manually aggregating bad data is an architectural failure.

Every SOC inherits a highly fragmented data ecosystem. Telemetry is continuously generated by diverse sources, including firewalls, cloud workloads, identity providers, endpoint sensors, and legacy systems. This telemetry arrives in disparate dialects, varying formats, and highly inconsistent levels of fidelity. Before AI tools can accurately reason about a potential threat, or an analyst can initiate a logical investigation and run a playbook response, this raw telemetry must be synthesized.

Historically, organizations analysts take on these complex synthesis processes, manually normalizing data points across different vendor schemas. This represents a key misallocation of human intelligence. The asymmetry in modern security operations is not merely a discrepancy in speed; it is an imbalance in how security teams are forced to allocate their finite time. When operators spend the majority of their shifts wrangling data instead of actively investigating threats, the foundation of the SOC itself is inadequate. To achieve defensive velocity, organizations must recognize that fixing the data foundation is the mandatory prerequisite for improving all downstream security functions.

Architecting the Data Foundation with Singularity™ AI Data Pipelines

Addressing the upstream data problem requires the implementation of advanced data pipelines capable of resolving enterprise data chaos before it impacts the detection engine. Frameworks such as SentinelOne’s® Singularity AI Data Pipelines serve as this foundational layer, engineered to ingest telemetry from every source and in every format without requiring months-long integration projects or heavy manual engineering.

Modern pipelines utilize AI to normalize raw telemetry into standardized formats, specifically aligning with the Open Cybersecurity Schema Framework (OCSF). This structural alignment transforms fragmented logs into structured data that is immediately actionable. It eliminates the need for analysts to construct complex regular expressions during critical incidents simply to reconcile how two different software vendors format data, such as usernames or a timestamp.

Efficient data ingestion also requires dynamic, in-flight optimization. Not all telemetry possesses the same analytical value, and storing all generated logs in highly indexed, expensive storage tiers is financially and operationally untenable. Data pipelines optimize data streams by filtering out extraneous noise, trimming excess volume, and routing specific logs based on dynamic criteria. High-value security events are routed and indexed for rapid search retrieval, while lower-priority compliance or operational logs are routed to more cost-effective tiered storage. The result is a substantial reduction in infrastructure costs, a higher signal-to-noise ratio, and a structured data foundation that is completely prepared the moment an investigation is required.

When underlying data pipelines automatically enrich that log with identity and asset information, revealing (for example) that a specific financial director’s laptop in a remote office is communicating with a known botnet, the output transitions from a raw data point into a definitive starting point. Crucially, this enrichment occurs systematically before the human operator ever interacts with the alert. Solving this data problem end-to-end is a primary reason SentinelOne was recognized in the IDC MarketScape for AI SIEM.

Accelerating Detection via Singularity AI SIEM

When a clean, structured data foundation is properly established, the performance of downstream security tools accelerates. Modern detection engines, such as the Singularity AI SIEM, leverage indexless architectures to manage enterprise-scale telemetry. Because the data is normalized and optimized prior to ingestion, these platforms can execute petabyte-scale queries with minimal latency, ensuring investigative results are delivered before the analyst’s attention wanes.

Within this architecture, detection logic is executed continuously against a stream of clean, correlated telemetry. This transforms an ocean of disparate event logs into readable, centralized dashboards that provide immediate situational awareness. The quantitative benefits of this approach are substantial. With AI SIEM, organizations are already executing their queries 70% faster. Adding AI Data Pipelines further augments this workstream, providing cleaner data for AI to run at optimal efficiency. These improvements represent the direct result of ensuring that the data arriving at the SIEM is inherently fit for purpose.

AI SIEM remains a single, comprehensive SKU with customers automatically receiving integrated pipeline functionality for everyday data optimization rather than treating it as a premium add-on. For every unit of paid Data Ingest capacity, customers can process twice that volume through Data Pipelines. A customer with 500 GB/day SIEM entitlement can push 1 TB/day through the pipeline at no additional cost.

Transitioning to Agentic Reasoning Layers with Purple AI

The establishment of a structured data pipeline unlocks the capability for true agentic reasoning within the SOC. Unlike traditional rule-based automation, which executes static responses to predefined triggers, technologies like SentinelOne’s Purple AI operate as a dynamic investigative layer.

When an initial alert is generated, an agentic reasoning system does not simply pause and wait for human triage. It autonomously launches an investigation, comprehensively maps the potential blast radius of the incident, and synthesizes a clear, logical recommendation for containment. Then, the analyst logs into the console and is presented with a fully formed situational briefing rather than a blank investigation screen.

More importantly, an agentic AI layer possesses the capacity to evaluate broader adversarial campaigns rather than isolated security events. In isolation, a minor registry key modification, a singular file write, or a brief outbound network connection may not meet the threshold for a critical alert. Legacy security tools often fail to connect these disparate, low-signal events. However, Purple AI can assemble these seemingly unrelated activities into a cohesive narrative, exposing the overarching strategy of the attacker before a major breach occurs.

This level of autonomous intelligence is strictly dependent on the underlying architecture. Advanced AI algorithms cannot derive accurate conclusions from unparsed, low-quality telemetry. The analytical integrity of the agentic layer is entirely contingent on the principle of data quality; systems like Purple AI require clean, structured data to function effectively, avoiding the fundamental issue of “garbage in, garbage out”.

Governed Hyperautomation and the Human-in-the-Loop

The final component of a modernized, agentic SOC is the deployment of Hyperautomation to execute defensive responses. To counter threats effectively, organizations must deploy automated workflows capable of executing decisions at machine speed. These no-code workflows can be configured to trigger autonomously based on AI triage verdicts, the disclosure of new high-severity vulnerabilities, or specific incoming alerts. By automating the mitigation phase, the SOC evolves from an environment strictly dedicated to passive observation into a dynamic system that actively neutralizes threats.

However, the implementation of automated response mechanisms must be rigorously governed. Executing changes to enterprise infrastructure carries inherent risk. To mitigate this, automated workflows must integrate critical approval steps, ensuring that highly consequential actions are paused until human authorization is provided. The analyst retains the ultimate authority, defining the precise parameters of what processes may run automatically and what workflows require manual judgment.

Redefining the Analyst Mandate via Autonomous Security Intelligence

The strategic objective of integrating data pipelines, agentic reasoning, and Hyperautomation is not the removal of the human operator. Instead, the overarching goal is the restoration of the analyst’s primary function: exercising expert judgment.

By offloading repetitive tasks to technological systems, organizations systematically remove operational friction. The data layer filters out irrelevant noise, allowing the analyst to clearly see the threat. The AI investigation layer removes the administrative grind of data collection, allowing the analyst to focus purely on analytical thinking. Finally, the automated response layer eliminates procedural delays, ensuring the analyst’s decisions are executed rapidly enough to matter. This creates an intelligence fabric, known as Autonomous Security Intelligence (ASI), where data, investigation, and response function concurrently as a single, unified system.

Under this model, the operational output of a single analyst is exponentially multiplied, allowing one unburdened professional to accomplish the work of ten while still owning every critical decision. While the alert queue will perpetually require attention, the fundamental nature of the work fundamentally changes. The timeline of a manual initial triage to active investigation compresses from a multi-hour ordeal into a matter of minutes. The data arrives clean, the investigation runs automatically, and the response mechanisms are prepared. The hours previously consumed by administrative waiting are directly reallocated to strategic decision-making.

Conclusion

When defensive systems are finally architected to operate at the speed of the modern threat landscape, the role of the human operator transforms. Analysts are no longer forced to act as passive passengers, grateful to be carried by fragmented tools. They are elevated to the role of pilots, operating with full situational awareness, retaining their judgment, and actively directing the defensive posture of the organization. This is the paradigm of the agentic SOC, and it is entirely predicated on the foundation of clean, structured data.

Contact us today to learn more about how SentinelOne is leading the way forward with Agentic SOC.


  • ✇Cybersecurity Blog | SentinelOne
  • The Autonomous SOC, Revisited: What 18 Months on the Road Has Taught Us Gregor Stewart
    This post revisits SentinelOne’s Autonomous SOC maturity model, first introduced in “Autonomous SOC Is a Journey, Not a Destination” (December 2024). When SentinelOne® introduced the Autonomous SOC maturity model, we made a deliberate choice: describe a journey, not promise a destination. The industry had no shortage of vendors declaring that AI would transform security operations. We thought the more useful contribution was a framework for understanding what that transformation looked like, at
     

The Autonomous SOC, Revisited: What 18 Months on the Road Has Taught Us

1 de Julho de 2026, 10:00
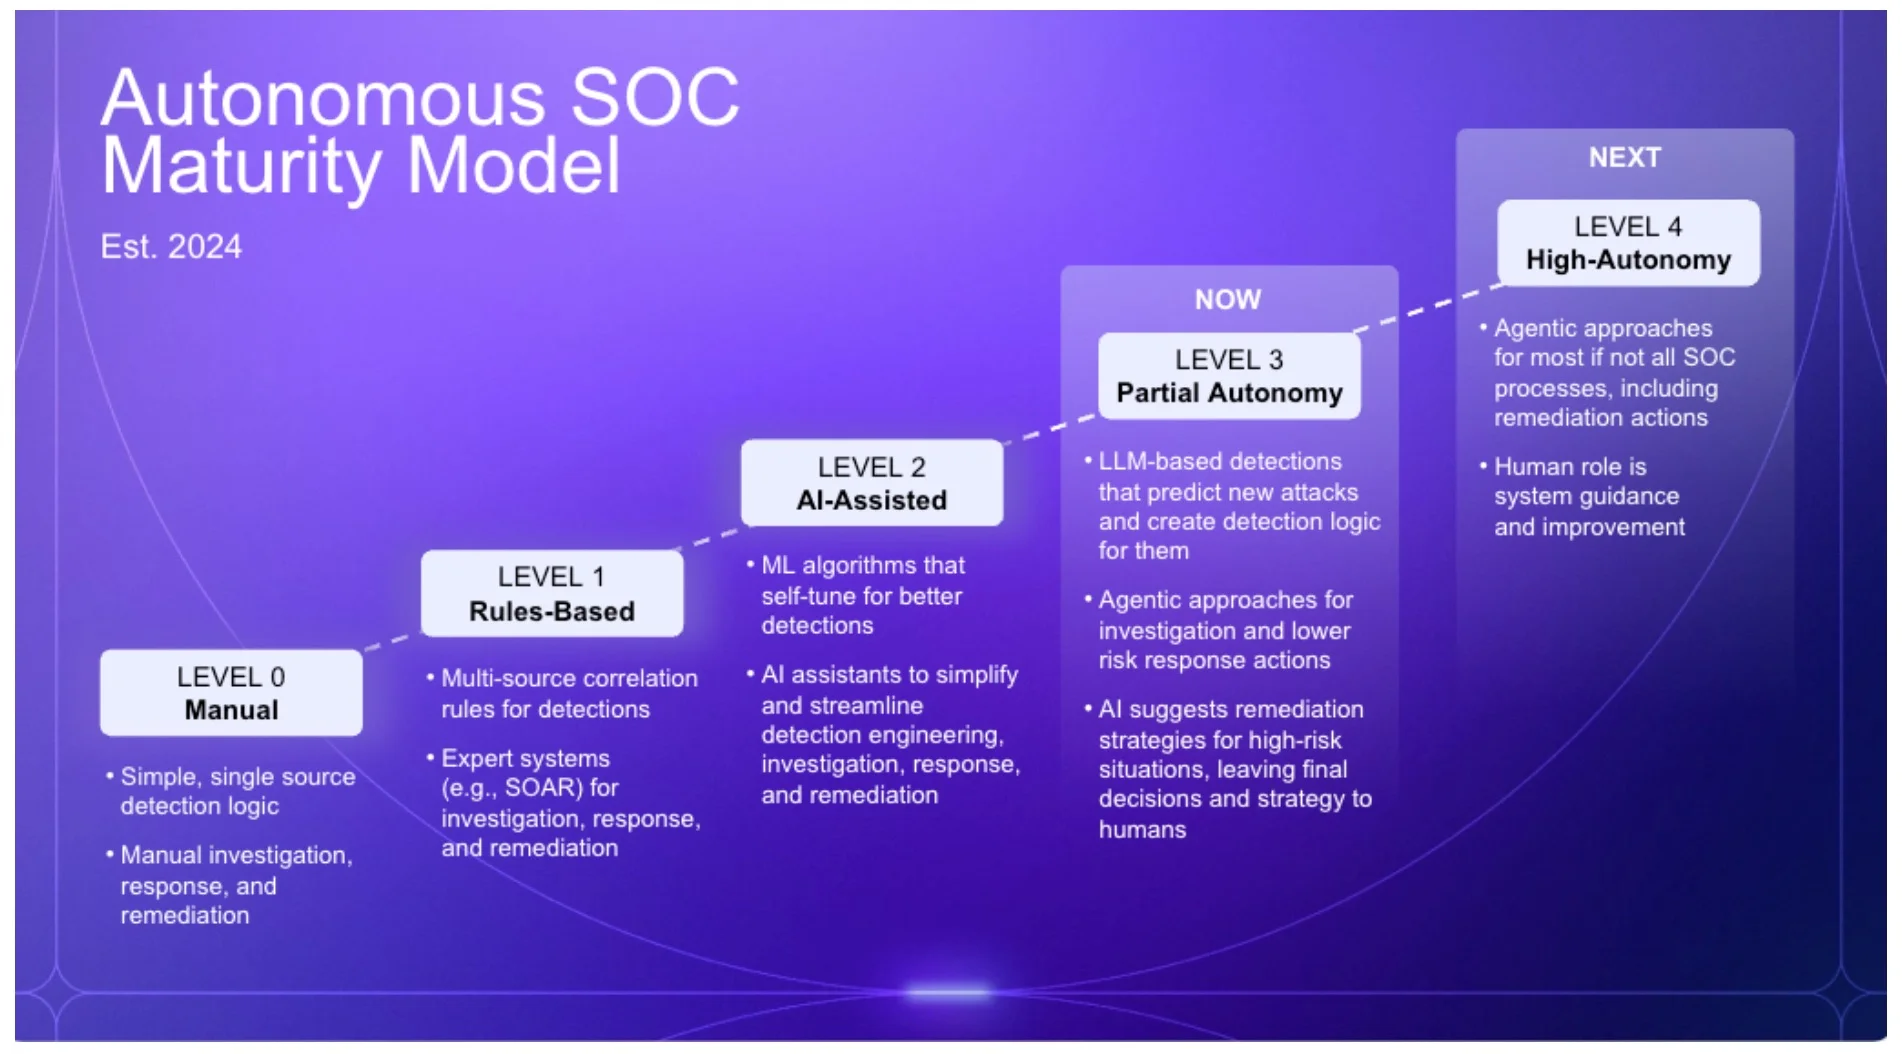
This post revisits SentinelOne’s Autonomous SOC maturity model, first introduced in “Autonomous SOC Is a Journey, Not a Destination” (December 2024).

When SentinelOne® introduced the Autonomous SOC maturity model, we made a deliberate choice: describe a journey, not promise a destination.

The industry had no shortage of vendors declaring that AI would transform security operations. We thought the more useful contribution was a framework for understanding what that transformation looked like, at what pace it was realistic, and what conditions each stage of progress required.

Security teams found the model useful. Not as a marketing claim, but as a map. CISOs and SOC leaders started placing their organizations on it, asking what it would take to move forward.

What happened next was telling. By RSAC 2026, ‘autonomous SOC’ appeared in vendor keynotes and product launches from companies that hadn’t used the term twelve months earlier. Add in pseudonyms like Agentic SOC and AI SOC, and the list explodes. Fast adoption brings loose definitions. For us, it’s worth being precise about what the concept means and what it doesn’t.

Here is what SentinelOne has learned from 18 months of real-world Autonomous SOC deployments.

What Held Up

Today, the progression still maps accurately to where organizations are and what separates each stage from the next. That accuracy holds even for a framework built before most organizations had meaningful AI deployment experience. The inflection points reflect real operational transitions at each maturity step.

The “journey not destination” framing has proven more important than we anticipated when we wrote it. In early 2026, Gartner published guidance to help buyers evaluate AI SOC claims more critically, noting that vendor credibility in this space depends on honest representation of where the technology is:

“Some vendors exaggerate capabilities (like being able to deliver a fully autonomous SOC), risking buyer trust and harming the reputation of legitimate solutions.”1

A maturity model is structurally honest. It reflects where you are, not where a vendor wishes you were. Gartner’s research found that while 40% of organizations are actively evaluating AI SOC capabilities, only 18% have actually deployed2. The gap between evaluating and deploying is rarely about technology. Most organizations cannot advance because they lack a clear view of where they stand or what the next stage requires.

When security leaders use the model as a reference point, the evaluation conversation changes. The question shifts from “does your product make my SOC autonomous?” to “what would it realistically take to advance, given where we are today?” A feature list cannot answer that question. An honest vendor can.

Watch our webinar on why most AI SOC deployments stall here.

What We Underestimated

The levels were always sound. What we underestimated was how much organizations needed to build before they could operationalize them. Customers understood where they wanted to go. But achieving Partial Autonomy (Level 3) requires a data foundation, a workflow architecture, and AI readiness that most teams were still building when we first published this model. That’s a fact about where most security organizations were in 2024.

The transition from AI-Assisted Operations (Level 2) to Partial Autonomy (Level 3) is primarily a governance problem, not a tooling one. The tools are capable. What most organizations are missing is an understanding of the foundation of data and trust that Partial Autonomy (Level 3) requires, including the role humans play in building it.

When analysts work with AI assistance, they leave traces. Which queries they accept. Which results they act on. Which steps they modify or override. Over time, the system learns which investigation patterns the team trusts, which AI recommendations get acted on, and where analyst expertise is required – the kind of institutional knowledge that only comes from doing the work. Partial Autonomy is built on that record, not installed on top of an existing stack.

The path from AI-Assisted Operations to Partial Autonomy starts earlier than most organizations realize. It begins before they’re thinking about autonomy at all. Every assisted workflow is building toward what comes next.

What Holds Organizations Back

The primary barrier between AI-Assisted Operations (Level 2) and Partial Autonomy (Level 3) is accountability.

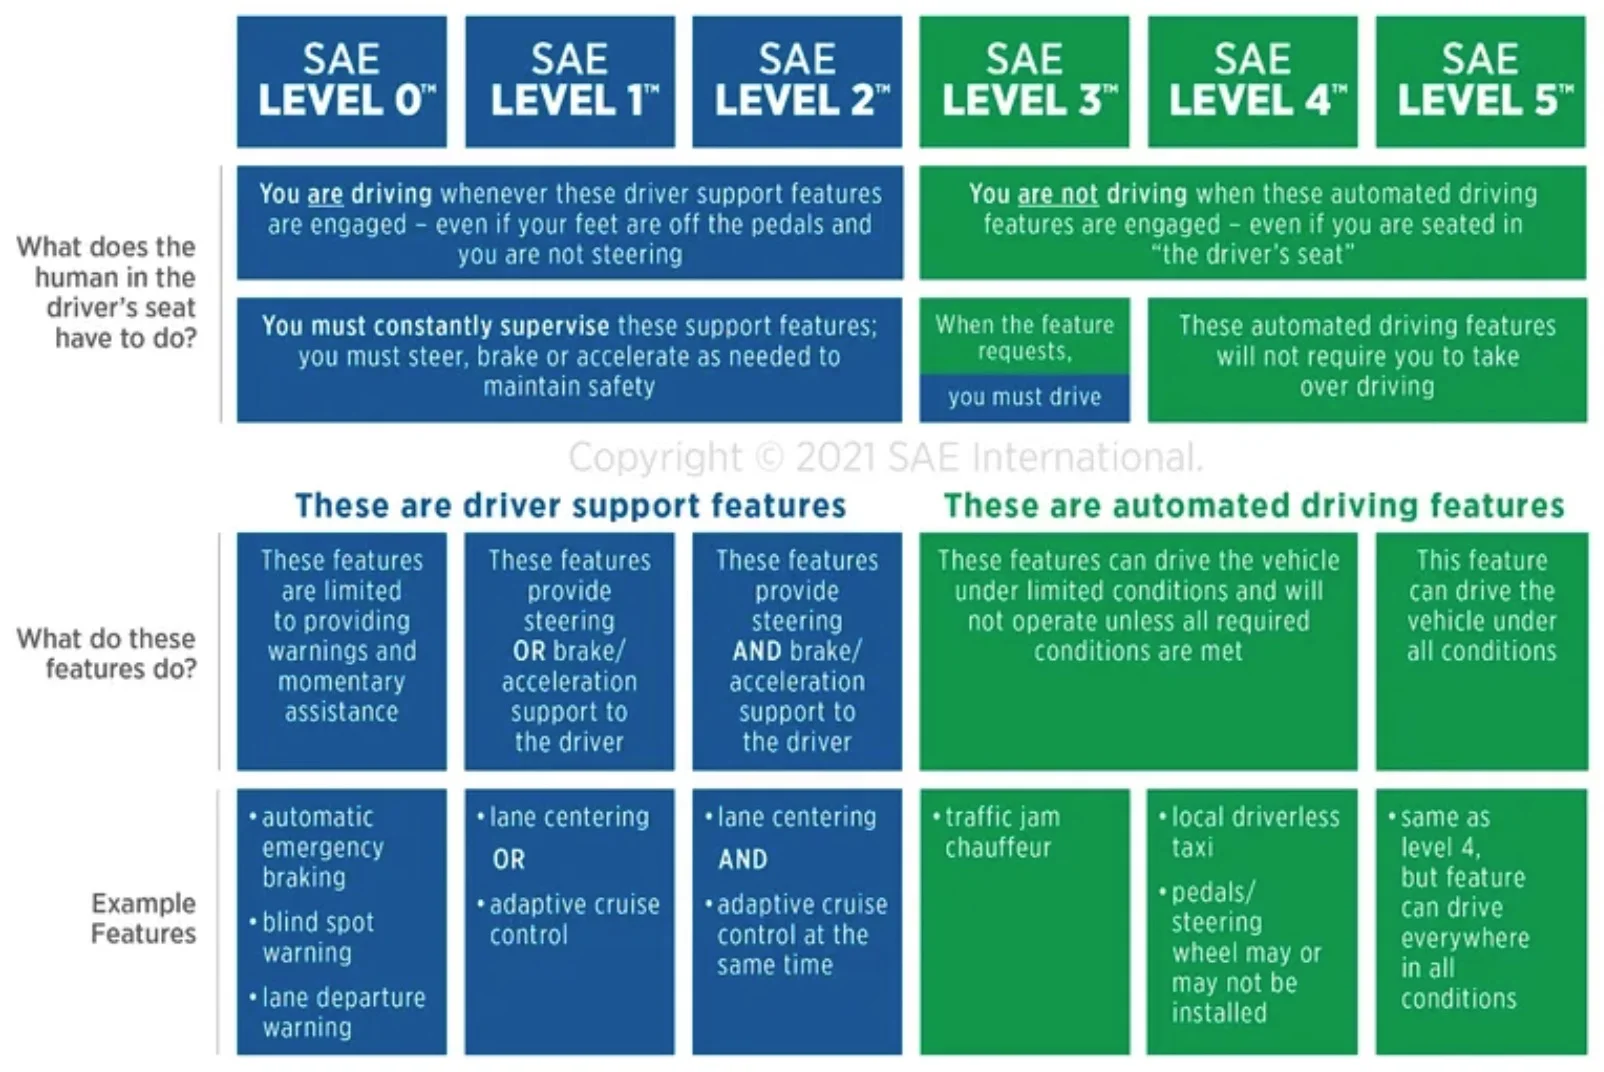
Consider how the automotive industry defined its equivalent of Partial Autonomy – SAE Level 3.

Taxonomy and Definitions for Terms Related to Driving Automation Systems for On-Road Motor Vehicles3

The designation applies only within specific, defined operational conditions. Outside those conditions, the human must take control. What qualifies a system for L3 is defined before autonomous operation begins: explicit parameters, a defined scope, and clear conditions for human override. Governance precedes autonomy.

Consider Waymo. It is the most capable autonomous system deployed at scale today — L3+ — operating without a safety driver under defined conditions. The vehicle is remarkable. But Waymo’s primary innovation is the organization built around it: the cloud infrastructure that keeps cars in autonomous condition, the human operations that handle exceptions the system cannot cover. The more autonomous the system, the more organizational maturity it required to build. High autonomy is an organizational capability.

The same logic applies in security operations. Accurate AI is the foundation. What makes Partial Autonomy legitimate is what gets built on top of it: defined rules of engagement, pre-approved policies, audit trails, and a clear organizational answer to who is responsible when an AI verdict is acted on. That accountability sits with the security team. When automation fires, it fires because someone made a deliberate governance decision to allow it. That is what makes it auditable, defensible, and durable.

Gartner’s readiness criteria for AI SOC deployments require that operational workflows be established in playbooks before AI is introduced4. In practice, the organizations that advanced most consistently treated that requirement as a sequencing discipline, not a box to check. They defined their rules of engagement before turning on automated response.

The second learning was the attacker asymmetry. Defenders who stall between AI-Assisted Operations and Partial Autonomy have often done the validation work. The AI logic checks out. What remains is the decision to extend that trust to autonomous action — and that decision takes time. Attackers move differently. They deploy, observe what works, and iterate. Governance is an externality. Trial and error with no consequences for failure is a significant operational advantage. The gap between a defender’s trust-building timeline and an attacker’s operational tempo is structural. It compounds.

Why High Autonomy Stays on The Horizon. And Why That Matters Less Than We Thought

Eighteen months of deployment have also changed how we think about the upper end of the model.

When the original post was written, High Autonomy (Level 4) was described as dependent on a level of AI reasoning we hadn’t yet seen in production security environments. That remains the right framing. What’s changed is how close that horizon has become. Two years ago, asking a model to reason through a multi-stage attack, correlate signals across data sources, and produce an auditable verdict required significant scaffolding and produced inconsistent results. That’s no longer true. The gap between where AI was and where High Autonomy requires it to be has narrowed substantially.

High Autonomy still requires more than capable models. Institutional trust takes time to build. Accountability structures have to go beyond controlled tests to survive real incidents. Human oversight has to be redefined from reviewing individual actions to governing a system’s behavior within a defined scope. Those are organizational problems, technology doesn’t solve them. That work is already underway at Partial Autonomy (Level 3). What the road to High Autonomy requires is only visible from Partial Autonomy. Organizations that haven’t operated there yet are planning for a destination they haven’t seen. The knowledge of what it takes is path-dependent, and it emerges from operation, not from design.

As organizations move deeper into Partial Autonomy, the distinction between levels matters less in practice. What security leaders actually want is relevant control: governance over the decisions that matter, without being burdened by the ones that don’t. You cannot be responsible or accountable for a system that asks you to review everything.

Control over the right decisions is what matters. An analyst reviewing every alert has maximum control and minimum leverage. A system that acts autonomously on well-understood threat patterns, surfaces only the ambiguous and novel cases for human judgment, and maintains a complete audit trail, gives the analyst control over exactly what deserves their attention. That is a better and more focused version of human oversight.

High Autonomy, seen through this lens, is AI that has earned sufficient trust within a defined scope. The remaining human decisions are the ones that require human judgment, because the governance architecture evolved to allocate human attention correctly.

In the same way, a pilot does not manually adjust every control surface for the duration of a flight. They set the destination, define the parameters, and monitor the instruments. The system handles thousands of micro-corrections that would be impossible to manage directly. The pilot’s job is to govern the conditions under which the aircraft flies itself, not to manage every control input directly. Nobody describes this as a lack of pilot control. It is a better allocation of pilot judgment. And it works because of the environment surrounding the autopilot: pilot training standards, airline operational doctrine, air traffic control, and regulatory frameworks. The technology is one layer of a much larger system.

The governance work done at Partial Autonomy is the same work that produces High Autonomy. Organizations investing in it now are not waiting for a future capability release. They are building the foundation on which High Autonomy operates.

What This Means for the Road Ahead

The first step toward Partial Autonomy is a policy decision. Define the conditions under which your organization will allow a system to act: which response actions, against which threat types, within what scope, under whose authority. Write it down, however rough. That document is the actual starting point. Without it, the tooling is irrelevant.

The work at Partial Autonomy is real, meaningful, and available now. Security teams that define accountability structures before deploying autonomous systems, build a record of AI efficacy in their specific environment, and treat governance as a prerequisite rather than an afterthought, are the ones that reach and sustain Partial Autonomy. They are also the ones best positioned for what comes next. That work produces a more integrated SOC — data, AI, and response operating as a unified system.

High Autonomy remains the north star. This clearly articulated ideal state stops organizations from settling too early. It is the same function that “zero trust” serves as an architectural principle: no organization fully achieves it. Every organization is better for pursuing it.

The tools are capable. The frontier models have advanced significantly since our maturity model was first introduced. The capability gap that once made waiting feel reasonable has narrowed. What remains is the institutional work. That work is always harder than buying a product, which is why vendors who are honest about it are worth paying attention to.

SentinelOne customers operating the Autonomous SOC are seeing it in their numbers: 75% faster investigations, 4x more threats handled, 42% fewer false positives5. Read the IDC Business Value Snapshot.

References

1 Gartner, “AI SOC Agents: Harnessing Innovation, Managing Expectations,” Kevin Schmidt, Alex Tytarenko, Steve Santos, 25 February 2026. G00841784.

2 Gartner, “AI SOC Agents: Harnessing Innovation, Managing Expectations,” Kevin Schmidt, Alex Tytarenko, Steve Santos, 25 February 2026. G00841784.

3 SAE International, “Taxonomy and Definitions for Terms Related to Driving Automation Systems for On-Road Motor Vehicles,” SAE Standard J3016_202104, April 2021. https://www.sae.org/standards/content/j3016_202104/

4 Gartner, “AI SOC Agents: Harnessing Innovation, Managing Expectations,” Kevin Schmidt, Alex Tytarenko, Steve Santos, 25 February 2026. G00841784.

5 IDC Business Value Snapshot, “The Business Value of SentinelOne Singularity AI SIEM,” Michelle Abraham and Matthew Marden, May 2026, sponsored by SentinelOne. #US54435826-BVS.

Third-Party Trademark Disclaimer 

All third-party product names, logos, and brands mentioned in this publication are the property of their respective owners and are for identification purposes only. Use of these names, logos, and brands does not imply affiliation, endorsement, sponsorship, or association with the third party.

The Agentic SOC: Solving Security’s Investigation Capacity Crisis in the Frontier AI Era

17 de Junho de 2026, 10:00

The security industry spent the last decade solving detection. Endpoint. Cloud Workloads. Identities. AI. We built better models. We moved beyond signatures. We reduced false positives. We got the alert into the right queue. Then, we discovered the harder problem had been waiting behind it.

The constraint in every SOC today is not detection. It’s investigation capacity. Security teams are generating more critical alerts than any staffing plan can possibly accommodate. The queue grows. Triage waits on analyst availability. Coverage drops on nights, weekends, and surges, exactly when adversaries know to move.

Frontier AI is about to make this exponentially worse. The same models reshaping every industry are being weaponized to chain hidden gaps and vulnerabilities, accelerate attacks, and compress attacker timelines. Investigation cannot stay a human-paced or human-scaled activity. If it does, defenders lose. We built Purple AI® to change that.

Every Alert. Investigated. Now.

Starting today, we’re opening up Purple AI Agentic Investigation to all new and existing SentinelOne® EDR customers. In the Singularity™ console. Activated with a single click.

The moment a new EDR alert is flagged Critical and Malicious, Purple AI acts, using flags you can trust. It is the output of over a decade of AI and ML models running natively at the edge, from behavioral analysis to real-time threat intelligence. Purple AI investigates signal vs. noise.

It collects evidence. It correlates telemetry across endpoint, identity, cloud, and third-party data. It builds the attack timeline and delivers a verdict: True Positive, False Positive, or Unknown. The complete evidence chain arrives with it before an analyst opens the console. We call it ‘zero-click’ investigation: Automated trigger, zero wait, coverage gaps closed.

Open the Alerts view, and you see it live: Purple AI retrieving context, running threat hunts, querying host telemetry, building the investigation in real time. Then, the verdict lands, supported and traceable, ready for a decision. This is investigation at machine speed. Continuous. At scale. Integrated into existing workflows.


The Native Platform Advantage

Purple AI investigates at this depth because it operates natively on the Singularity Platform. Zero integrations required. Where your team already works. Where your security data already lives.

Bolt-on AI tools layered onto other platforms start from a disadvantaged position. They require connectors, data mapping, and integrations before they can reason. Purple AI reasons directly on telemetry already in Singularity: endpoint, identity, cloud, and third-party data in the Singularity Data Lake. Nothing to configure. One click to activate.

The intelligence is distinct. Purple AI takes a multi-model approach that keeps customers at the edge of frontier AI reasoning capability. Models from leading frontier providers like Anthropic (Claude) and OpenAI (GPT) are part of that architecture. So is SentinelOne’s own Ultraviolet family of models, purpose-built on petabytes of real security telemetry and trained for SOC investigation reasoning. Here, frontier AI reasoning combines with Autonomous Security Intelligence.

Autonomy With Accountability

Agentic AI without defined limits and guardrails is a liability. As an AI-first company, we get that. So we built the limits first. Investigations run autonomously. Response stays on your terms. You decide your human-in-the-loop comfort zone.

Every verdict connects to one-click or policy-driven response actions in Singularity, including governed automated execution through Hyperautomation, SentinelOne’s workflow automation layer. Nothing fires outside the guardrails your team defines. Activation is admin-controlled and reversible at any time. Access is role-based. Every verdict carries a complete, auditable evidence chain. We’ve eliminated black-box decisions. Your analysts can see and review every AI step. The agentic SOC keeps humans in control of what happens next, by design.

What Customers Are Doing With It

Purple AI customers are already seeing the shift. Agentic Investigation is built to extend it further.

“By using Purple AI, we’re saving between 40% and 50% of the time to investigate incidents, allowing us to respond much quicker. It gives us readily available information on alerts — which systems, which users, and why they may be malicious,” said Rod Goldsmith, Cybersecurity Leader at YKK Americas.

“Purple AI really increases our efficiency. It allows users to search logs quickly without knowing any query languages and get answers faster, reducing our Mean Time to Respond,” said John McLeod, CISO at NOV Inc.

“SentinelOne helps us with our incident response process tenfold. We have so many options, from automation to using Purple AI, to give my analysts more confidence in their abilities,” said Zack Moody at KYOCERA AVX.

AI designed to give human defenders a decisive operating advantage. The machine removes the ceiling on what humans can cover.

Singularity Credits

Alongside Agentic Investigation, we are introducing Singularity Credits: a new unified currency for AI-powered workflows across the Singularity Platform. AI should be accessible. Utilization should be visible. Spending stays in the hands of those who set the limits. Credits are built around all three.

Every eligible SentinelOne customer gets free access starting this week. No payment method required. After the trial, Credits are available through partners, direct billing, and eCommerce channels. The balance is visible in real time. Built-in spending controls keep consumption bounded.

Agentic SOC, Autonomous SOC, AI SOC, ISOC: Call it what you want. Just don’t call it a roadmap item.

What we are delivering today is real, accessible and, for the next couple of months, complimentary. It is the agentic SOC in operation. GA, now. Critical alerts automatically investigated. Verdicts autonomously reached. Workflows automatically triggered. Governed authorization. Responses that execute within the policies your team controls and human-in-the-loop gates that your team decides.

The industry has called this many things: The Autonomous SOC, the Agentic SOC, the AI SOC. Gartner now has a name for this model: the Integrated Security Operations Center. Modern threat detection, investigation, and response as a single, continuous, AI-driven loop vs. the historic siloed functions and tool sprawl. More than solving alert fatigue, the new model has the potential to solve the investigation capacity gap and shrink MTTR to a scale and speed that cybersecurity will require in the frontier AI era. At SentinelOne, we have been building for this moment for years.

Investigation capacity should never again be the reason a critical alert goes unexamined. Frontier AI belongs where the data and the analysts already are: In the console, in the workflow, governed by the human customer. We put it there.

Activate Purple AI Agentic Investigation in your Singularity console or visit s1.ai/agentic.

Why Most AI SOC Deployments Stall. How the Fastest Teams Don't.
Join the webinar on Wednesday, June 24, 2026 at 10:00AM PT/ 1:00PM ET.

Third-Party Trademark Disclaimer:

All third-party product names, logos, and brands mentioned in this publication are the property of their respective owners and are for identification purposes only. Use of these names, logos, and brands does not imply affiliation, endorsement, sponsorship, or association with the third-party.
❌
❌