A French blood bank cyberattack targeted EFS plasma refrigeration units, altering temperature thresholds before emergency alarms prevented product loss.
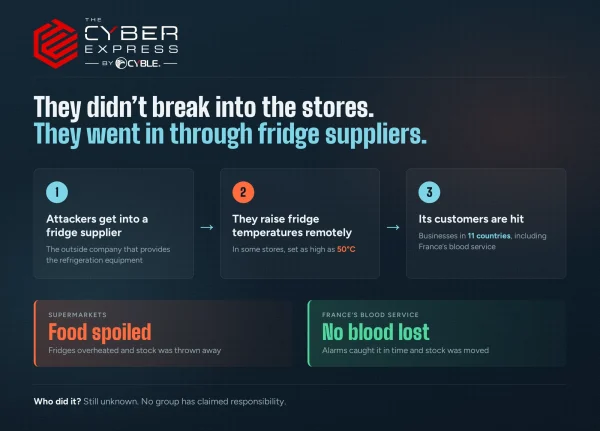
Until this week, the wave of refrigeration cyberattacks sweeping Europe looked like a supermarket problem. That changed when France's national blood service confirmed that temperature controls had been altered at three of its sites. Blood products stored for hospitals were suddenly at risk, and the attackers had not even targeted the organisation directly.
The Établissement Français du Sang (EFS) said "temperature and defrosting thresholds were raised to very high levels" in its cold storage rooms. These rooms hold blood products at preparation and distribution sites before they go to healthcare facilities, along with samples for biobanks.
The outcome was far better than in the supermarkets. "No health impacts have been identified and no losses of blood products have been reported," the EFS said in a statement on Tuesday.
How the Refrigeration Cyberattacks Reached Blood Storage
The EFS says it was not targeted directly. Like many of the affected retailers, it says the attack reached it through a third-party provider of refrigeration equipment.
That detail explains why a blood service ended up on the same list as supermarkets. If attackers can get into a shared supplier's systems, any organisation using that equipment may be exposed, whatever its sector.
This is the first reported case in France in the second wave of attacks on control systems, and the first reported to affect a healthcare organisation.
Why the Blood Supply Survived When Food Did Not
The difference came down to how quickly someone noticed. "The EFS's monitoring and alarm systems enabled the rapid identification of these anomalies and the implementation of necessary measures to ensure that no blood samples or products were compromised," the organisation said.
Depending on the situation, affected equipment was either brought under control without impacting the products, or shut down. Products in the affected cold rooms were moved to other facilities as a precaution.
Compare that with the first wave in France in October. Attackers remotely defrosted fridges in hundreds of supermarkets, reportedly by triggering a forced defrost option, and pushed temperatures as high as 50 degrees Celsius. They struck while stores were closed, so the heat went unnoticed for hours. Tonnes of food perished, some equipment melted, and in some stores the heat sparked fires. Reporting on that wave found the attackers had targeted ageing, internet-connected devices still online years after their manufacturer stopped supporting them.
How Far the Refrigeration Cyberattacks Have Spread
The second wave is wider than the first. Businesses in at least 11 countries have reportedly been affected: Belgium, Estonia, Finland, France, Germany, Ireland, Luxembourg, the Netherlands, Portugal, Sweden and the United Kingdom.
Earlier this week, supermarket chains in Sweden, Belgium, Luxembourg, Ireland and Estonia reported fridges and freezers set to high temperatures, with several discarding food. In Estonia, where the intrusion was caught within minutes, there was no significant damage.
Who Is Behind It?
No one knows for sure, and no group or entity has claimed responsibility for the attacks. It is also unclear whether the same people are behind both waves.
Rumours have spread online that two Russian hacktivists groups, Noname057(16) and Z-Pentest Alliance, posted that they had hacked Danfoss. That led to speculation that they were behind the freezer attacks. Analysts now question whether that claim means they were responsible.
Russian groups have not been ruled out. However, experts say Iranian hacktivists, nation-state hackers, or even teenagers pulling pranks could also be the culprits.
A French Bank Reports a Separate Attack
In the same week, Crédit Mutuel Arkéa in northwestern France said it had halted some services after a cyberattack enabled fraudulent transactions. Nothing in the bank's statements links the incident to the refrigeration attacks. However, the bank describes a similar entry point: attackers "used the platform of one of our service providers" to reach the bank directly.
The bank said attackers used its own account, not customer accounts, to make transactions to other banks. That potentially let them convert the money into cryptocurrency through specialised platforms. It denied press reports that the attackers got in through its subsidiary Fortuneo, and said human error was not the cause.
Asked whether 118 million euros was stolen, the bank said it could not confirm the figure and could "only validate the order of magnitude." Some funds have been frozen and recovery efforts are under way. The bank says the losses will not threaten its financial stability and that customers' assets were not affected, apart from delays to some transfers. Almost all operations have resumed.
The bank has also warned customers about a likely rise in phishing attempts, urging them never to share passwords, card numbers or SMS validation codes.
The refrigeration attacks and the bank attack have not been tied to the same attackers. What they share is the route in. In both cases, the organisations say they were reached through an outside provider rather than through their own systems. Neither the blood service nor the bank was the first door the attackers opened.
Per-token pricing has become the default commercial language of generative AI, and practically every budget conversation now happens in those terms (tokens consumed, tokens generated, cost per million tokens, etc., etc.).
The problem is that this model treats every AI interaction as a discrete transaction, separate from the infrastructure required to process it. Yes, tokens are a billing unit, but the work they represent also has a physical footprint in memory and storage, and as agentic AI drives context windows into the hundreds of thousands of tokens, that footprint has outgrown the GPU.
So why does this matter? Well, according to recent analysis published in Harvard Business Review (HBR), corporate AI is about to experience a massive “cost shock”, as vendors move away from unmetered or bundled AI features and begin passing on the cost of the infrastructure required to deliver them.
As HBR points out, organizations are currently being paid, in effect, to adopt AI, with major software vendors quietly absorbing the steep costs of GPUs, inference and tokens on their customers’ behalf. That subsidy is not built to last.
Take memory and storage costs, for example. DRAM prices have risen sharply as manufacturers focus on High Bandwidth Memory (HBM) production for AI accelerators, tightening supply for conventional server memory. Meanwhile, demand for AI is exerting sustained pressure on the availability and pricing of high-capacity SSDs.
This is totally unsustainable, and there was always going to come a point at which vendors could no longer continue covering these costs themselves and would need to pass more of them on to customers. That point is now rapidly approaching.
The scale of the shift is hard to overstate. Google was processing 9.7 trillion tokens a month in 2024; by mid-2025 that had risen to 480 trillion, and at this year’s I/O, Sundar Pichai put the figure at 3.2 quadrillion tokens a month. Goldman Sachs projects industry-wide token consumption will multiply another 24 times by 2030. Whatever an organization budgeted for inference last year, the volume assumption behind it is already out of date, and a growing share of that volume is input, not output: agentic workflows that plan, call tools and re-read context on every step are pushing input tokens, not generated ones, to the top of the cost stack.
Your AI budget has a serious NAND problem
The clearest sign of where this is heading came at CES 2026, when Nvidia unveiled what it first called its Inference Context Memory Storage Platform, built around its coming BlueField-4 DPU, and has since formalized as the NVIDIA CMX context memory storage platform. CMX standardizes the offload of the model’s working memory, the KV cache, onto NVMe SSDs, extending GPU memory into a shared, pod-level context tier and making it persistent across inference runs. Nvidia says the approach can deliver up to five times greater power efficiency and up to five times higher tokens-per-second throughput, and it already has more than a dozen storage partners lined up to support it, including Dell, IBM, NetApp, VAST and WEKA.
That is a significant validation point: several storage vendors were already extending GPU memory onto flash before ICMSP existed. Nvidia standardizing the approach across its ecosystem confirms this is now an architectural direction for the industry, not a niche workaround. But it also means the economics of inference are no longer determined solely by GPU pricing; they are now directly exposed to storage media pricing.
That exposure matters because flash pricing is anything but stable. According to VDURA’s own Flash Volatility Index, 30TB TLC SSD pricing rose 472% between Q2 2025 and Q1 2026, and the price multiple between high-capacity QLC flash and hard drives widened from roughly 4.9x to more than 22x over the same period, while HDD pricing moved about 35%. If cost-per-token now depends on flash-resident context tiers, then token costs inherit flash volatility, and organizations running all-flash inference infrastructure are carrying unhedged exposure to the NAND market on every query.
Instead, flash should be reserved for hot context data where its performance genuinely affects inference. This is because not all types of data generated or retained by AI workloads have the same latency requirements. For instance, data retained for future use, such as checkpoints, does not necessarily need flash performance. The hyperscalers worked this out long before the current price cycle: Google, Meta and Microsoft do not run all-flash storage; they run mixed fleets, with just enough flash to saturate compute and intelligent tiering draining everything else to high-density disk. A mixed-fleet architecture separates performance capacity from bulk capacity, giving organizations a structural hedge against volatile flash prices.
Tread carefully
If they aren’t doing so already, infrastructure leaders should model token-cost sensitivity to media pricing before committing capital. Do not forget that agentic workloads can disproportionately increase token consumption on the input and context sides. As a result, cost models must account for how much context requires high-performance flash capacity and how much can be stored on lower-cost tiers. Teams should regularly test how projected AI costs change as CMX-style architectures push more context onto NVMe, and as SSD pricing rises further while context requirements grow.
That all being said, HBR’s concluding analysis is extremely apposite: as long as executives are being asked to redesign their organizations around a technology with unpredictable pricing, they should tread carefully.
Discover the impact of the Microsoft 365 storage changes. Learn how the new 2TB shared OneDrive limit severely squeezes Family Plan users and their files.
Today, shared Microsoft 365 plans include 1 TB of OneDrive cloud storage for every family member. Microsoft is about to shrink that allotment dramatically.
The FBI and the U.S. Secret Service (USSS) have issued a joint cybersecurity advisory warning organizations about FortiBleed, an active global credential-compromise campaign targeting internet-facing Fortinet FortiGate firewalls and SSL VPN gateways. The advisory, published on October 6, 2026, cites SOCRadar data verifying more than 86,644 compromised devices across 194 countries.
According to the advisory, the campaign exploits reused or leaked credentials and legacy SHA-256 password storage, allowing threat actors to harvest and crack authentication data at scale. Attackers continue to scan exposed Fortinet firewalls using previously obtained credentials, and some affected organizations have been locked out of their own systems.
How the FortiBleed Attack Chain Works
The operation's internal workflow came to light after the threat actors unintentionally exposed their own backend server. The open directory revealed a mature, multi-stage campaign run as an initial access broker operation.
Attackers first scanned the internet for exposed FortiGate SSL VPN portals using automated scripts. They then gathered credentials through credential stuffing and password spraying, drawing on prior Fortinet leak dumps and infostealer logs.
Password hashes taken from compromised devices were exfiltrated and fed into a GPU-accelerated cracking cluster running on rented infrastructure, where Hashcat and Hashtopolis ran distributed jobs to convert stolen data into plaintext credentials.
Cracked credentials were then validated, with scripts filtering out honeypots, mapping organizations and ranking high-value targets by revenue and network structure. Attackers created new administrative accounts on firewalls to maintain persistence, then moved into victim networks to enumerate Active Directory and identify privileged accounts. The final stage involved selling access, including working VPN configurations and target lists, to downstream threat actors.
FortiBleed Lockouts and Ransomware Links
The advisory warns that victims may lose access to their Fortinet devices if attackers delete original accounts or change their passwords. In certain cases, threat actors removed existing accounts to block organizations from their devices while attempting lateral movement. Recovery may require steps beyond standard patching and password resets.
Reporting also indicates that initial access brokers using the FortiBleed attack chain have supplied access to ransomware affiliates, currently including INC/Lynx ransomware and Payload ransomware.
FortiBleed Indicators of Compromise
The agencies released indicators of compromise (IOCs) to help defenders review their environments. IP address 45.154.12.132 was observed as a command and control server, while 154.202.59.169 and 103.27.186.156 served as proxy nodes and 45.155.250.158 functioned as a beacon relay. The address 85.11.187.8 was linked to the Hashtopolis tool. The advisory also lists 13 IP addresses observed between June 18 and July 23, 2026, conducting brute force attacks or authenticating with compromised accounts.
Account names found on victim systems include adminin, fortiAdmin, forticloud-sync, fgtsecure, adminsslvpn, itadmin and roadmin. The agencies note that IP addresses may be reassigned over time and advise organizations to vet IOCs before acting on them.
Recommended Mitigations Against FortiBleed
The FBI and USSS recommend that organizations:
Restrict external management through trusted hosts, a local-in policy, or by removing internet administration entirely.
Terminate all active admin and VPN sessions and reset all Fortinet VPN and administrative passwords.
Review firewall and VPN configurations for unrecognized accounts and unauthorized changes.
Check firewall, VPN, authentication and domain controller logs for unusual access.
Use PBKDF2 to store administrator credentials and remove weaker legacy hashes, following Fortinet guidance for FortiOS v7.2.11 and later.
Review all REST API keys, remove unknown ones and refresh legitimate keys.
Organizations that detect a compromise are urged to isolate affected hosts, scope the intrusion and report incidents to the FBI's Internet Crime Complaint Center (IC3), a local FBI field office or a local USSS field office.
CISA warns the Viidure dashcam app leaks hardcoded cloud credentials (CVE-2026-96587) and public storage (CVE-2026-94204). The vendor has not responded.
For the first three years of the generative AI wave, the output of a model was a string. You called an API, you got tokens back, you rendered them in a chat window or wrote them to a row in Postgres. The economics of that pipeline were dominated by inference cost. Storage was a rounding error.
That era is over. The output of a modern generative pipeline is an asset: a 4K video clip, a stem-separated audio track, a 50-megapixel product render, a 3D mesh with PBR textures. Generative AI has gone from text-centric to asset-centric, and the architectural center of gravity has moved with it. The teams building durable advantages in generative media right now are the ones treating their storage layer as a pipeline component rather than a destination.
This is a good problem. It is the problem you get when your pipeline works.
Asset-centric changes the shape of the system
Text pipelines are stateless in practice. A prompt goes in, a response comes out and the interesting state lives in a database. You can rebuild almost any artifact by re-running the call.
Media pipelines are not like that. Every stage produces a large, opaque binary that the next stage consumes. A single finished deliverable might traverse a dozen of them: prompt expansion, base generation, upscale, frame interpolation, color pass, audio generation, mix, mux, transcode to delivery formats, thumbnail extraction. Each stage writes an intermediate. Each intermediate is expensive enough to regenerate that you keep it.
The result is a system where the objects are the state. Your object store stops being a place you put things when you are finished and becomes the substrate the pipeline runs on.
Adoption is past experimentation, and the volume is in production
Advertising has the clearest numbers. IAB’s 2026 Digital Video Ad Spend and Strategy Report finds that nearly two in three digital video buyers now use generative AI for creative, up from half in 2025. A third of their ad assets are expected to involve generative AI this year, up from a quarter in 2025, with buyers projecting 43 percent by 2027. That is happening inside a U.S. digital video ad market IAB projects will pass $80 billion in 2026, growing 11 percent year over year, nearly 20 percent faster than the total ad market.
The interesting detail for architects is what the creative is used for. IAB’s prior-year data showed buyers reaching for generative AI specifically to produce audience-specific versions of an ad, visual style variations and contextually adapted cuts. That is not one asset per campaign. That is a matrix.
Games are the instructive counterexample. GDC’s 2026 State of the Game Industry puts generative AI use at 36 percent of industry professionals and 30 percent at game studios specifically, but the usage breakdown is dominated by language models rather than media generation: research and brainstorming at 81 percent, code assistance and routine writing at 47 percent each, prototyping at 35 percent. The most-used tools are ChatGPT, Gemini and Copilot. Sentiment is sharply negative, with 52 percent saying generative AI is having a negative impact on the industry, rising to 64 percent among visual and technical artists. Asset-centric pipelines have not landed in games the way they have in advertising, and the constraint is as much workforce and provenance as it is tooling.
Elsewhere, the pattern holds even where the survey data is thinner: e-commerce teams generating on-model imagery per SKU per segment, localization pipelines producing dubbed and lip-synced variants per market, previsualization work that used to require an art department.
What the adopting categories have in common is that none of them produce one asset per request. They produce a set. The pipeline is judged on how many viable options it surfaces, which means a better pipeline is, definitionally, a pipeline that writes more bytes.
Reactive architecture, because the model layer will not hold still
The model landscape resets on a cadence measured in weeks. A new video model ships with better temporal coherence. A new audio model handles multilingual prosody properly. A new image model finally gets text rendering right. If your pipeline requires an engineering sprint to adopt a new model, you are structurally behind teams whose pipelines do not.
Reactive architecture is the answer, and it means two specific things.
Model-agnostic stages. Each stage of the pipeline should express a contract in terms of inputs and outputs, not in terms of a vendor. A generation stage takes a prompt and conditioning assets and produces a video at a declared resolution and duration. Which model backs it is configuration. Swapping providers should be a config change and an eval run, not a refactor.
Event-driven orchestration. Polling-based orchestration couples your stages to a scheduler and makes each new stage a change to the control plane. Event-driven orchestration inverts it: a stage completes, it writes its output, the write itself is the signal that the next stage should start. Adding a stage means subscribing to an event, not modifying a DAG definition that six other teams depend on.
This is where storage stops being passive. Object storage that emits events on write lets your bucket act as the message bus for the pipeline. B2 Event Notifications send a signed HTTP POST to a webhook endpoint when objects are created, updated or deleted, with rules scoped per bucket and filterable by prefix. That prefix filter is the part that matters architecturally: if your bucket is organized by stage, a rule on stage/upscale/ is a subscription to “upscale finished” without any code knowing what upscale is. Custom headers on the notification carry auth tokens or context to the target, so the endpoint can be a queue, a serverless function or a workflow platform rather than a service you had to build.
A completed upscale triggers the color pass. A completed mux triggers the transcode fan-out. A completed transcode triggers the CDN warm and the catalog write. The storage layer sequences the work, which removes an entire class of orchestration glue from your codebase and removes polling latency along with it.
Quality improvements arrive as file size increases
Every generation of media models improves along axes that all cost bytes. Resolution goes up. Frame rate goes up. Duration limits extend. Bit depth and color fidelity improve. Audio moves from mono to multi-channel. Compression artifacts that were acceptable at 720p are not acceptable at 4K, so teams move to higher bitrates and, for anything entering a post pipeline, to intermediate codecs.
The arithmetic is worth doing explicitly. A 10-second clip in a delivery-grade H.264 4K encode at 50 Mbps is roughly 60 MB. The same ten seconds as a ProRes 422 HQ intermediate, which Apple targets at 884 Mbps for 3840×2160 at 30p, is 1.1 GB. That is roughly 18 times the size, and intermediates are exactly what you keep between stages. Now assume your pipeline generates eight candidates per brief because your creative director wants options, and each candidate produces four intermediates before final. That is one brief consuming tens of gigabytes.
Nobody plans for that in a proof of concept. Everybody encounters it in month four of production.
The iteration multiplier
Here is the part that surprises teams: robustness and storage growth are the same curve.
A fragile pipeline produces one output per request because that is all it can manage. A robust pipeline produces candidates, keeps the rejects for training and eval, versions every asset so a creative decision can be reverted, retains intermediates so a late note does not require regenerating from the prompt, and derives proxies, thumbnails and per-platform cuts from every approved master.
Each of those is the correct engineering decision. Together they mean that improving your pipeline increases your storage footprint superlinearly relative to your output volume. If your unit economics assume storage scales with delivered assets, they are wrong. Storage scales with attempts multiplied by stages multiplied by versions multiplied by derivatives.
This is why storage strategy has to be a design input rather than a line item you discover on an invoice. The two things that turn it from a manageable cost into a structural problem are egress pricing and the absence of a lifecycle policy. Egress hurts most in the exact architecture described above because a multi-stage pipeline repeatedly reads its own intermediates, and a distribution layer constantly reads masters. When every read carries a metered charge, the pipeline design that produces the best creative output is also the one that produces the worst bill, and teams start making architectural compromises to protect margin. Lifecycle policy hurts by omission: if you never decide what an intermediate is worth after 30 days, you pay to keep all of them forever.
What to put in place now
If generative media is core to what you are building, four decisions determine whether your storage layer accelerates you or constrains you:
Choose a storage economic model that does not penalize reads. Understand your egress terms before your architecture depends on them. A pipeline that reads its own outputs at every stage is a read-heavy workload, and pricing that assumes write-once, read-rarely does not fit it. Model the ratio you actually expect: egress as a multiple of stored volume, not as an absolute. That ratio is the number to design against.
Make writes trigger work. Use object-level event notifications as the pipeline’s signaling mechanism. This buys you loose coupling, lower latency between stages and the ability to add a stage without touching the orchestrator.
Attach metadata at write time. Model version, prompt hash, parent asset, generation parameters, approval state. Metadata written at generation time is nearly free. Reconstructing provenance across a million objects later is not; provenance is what makes your rejected candidates usable as eval data and a training signal.
Define lifecycle policy per artifact class. Masters, approved derivatives, intermediates and rejects have different retention values. Encode that as policy on day one rather than as a cleanup project in year two.
Which points at the useful way to think about the storage layer: in a pipeline where everything else churns, it is the constant. Models turn over every few weeks. Stages get swapped, added and reordered around them. Output volume compounds with every quality improvement. The one layer absorbing all of that without being redesigned is the one holding the assets, so it is worth choosing based on the characteristics that stay true while the rest moves. That is what we built B2 for. Always hot, so no stage waits on a rehydration to read what the last one wrote. No retention minimum or file size floor, so intermediates that were always disposable cost what they used. Egress scales to what you store rather than metered per read, so a pipeline that reads its own output is not penalized for being good at its job. The architecture above it should change every quarter. The storage underneath it should not have to.
The opportunity
The teams that will win in generative media are not the ones with privileged access to a model. Model access is converging toward commodities. The advantage is in the pipeline: how fast you can adopt a better model, how many candidates you can afford to generate, how much history you retain to evaluate and fine-tune against, and how cheaply you can move all of it.
Every one of those is a storage architecture question. Treat the storage layer as an active participant in the workflow and it becomes the thing that lets you iterate faster than your competition. Treat it as a bucket you dump finished files into, and it becomes the ceiling on how good your pipeline is allowed to get.
The assets are the product now. Architect accordingly.
Dell Technologies is acknowledging that infrastructure and storage supply still can’t keep up with agentic AI’s insatiable appetite for resources.
The company this week reported a “record” AI backlog, with $95 billion in orders waiting to be filled. This dovetails with quarterly earnings reflecting a more than 50% year-over-year increase in AI demand.
On an earnings call, Dell COO Jeff Clarke acknowledged that supply constraints start with servers and storage, and span the stack to “just about every product going through a leading node.”
“We are doing everything we can to get more supply,” he said. “In today’s environment, that’s a very difficult task.”
A glimpse of infrastructure demands ahead
Dell reported that, in its financial quarter ending July 31, its revenue was $47 billion, reflecting 58% year-over-year growth. Moreover, revenue in its Dell Infrastructure Solutions Group (ISG) increased 89% to a record $31.8 billion.
Much of this growth is in servers, notably traditional central processing unit (CPU)-based servers that are increasingly supporting agentic AI workloads. Demand is “exceptionally strong” in this area, with earnings up 122% year-over-year.
Perhaps most tellingly when it comes to the ongoing demand, the company booked nearly $61 billion in AI server orders in the three months ending July 31; all told, over the last 12 months, it has inked more than $130 billion in AI server orders.
Clarke reported that Dell converted $131.7 billion of demand into orders over the last year, and that demand is broadening across enterprise customers, neoclouds, and sovereign cloud providers. To illustrate his point, he noted that the number of customers using Dell AI Factory, the company’s platform built to support AI workflows, has surpassed 6,500, and of those, 3,300 signed on in the last three quarters. Clarke pointed out that, by contrast, it took the company two years to sign on the first 3,200 after debuting Dell AI Factory in May 2024.
“Agentic demand is reshaping the data center,” Clarke said. Inference is “pure demand in our industry.” In fact, Dell anticipates that 3,600 quadrillion tokens will be in use by 2030, representing an 87x increase from today. Further, over that same period, training demand is predicted to grow to 850 zettaflops, a 5x jump.
“Enterprise agentic AI is expected to be the single largest workload by 2028,” Clarke said, and by 2030 will account for 75% of all data center demand.
Enterprises clamor for traditional servers
Dell is seeing a growing trend of customers requiring “meaningful CPU compute capacity” to support AI and agentic workflows. As evidence of this demand, in just its last two financial quarters, it has generated nearly as much revenue from traditional servers and networking as it has in any prior full year in company history.
Most of this growth comes from existing customers accelerating their investments in traditional IT environments to refresh, modernize, and bolster performance, efficiency, and resiliency. Dell anticipates “significant and durable” refreshes ahead, and heightened security and resiliency requirements are also increasing demand.
“AI requires modern, disaggregated architectures that keep data accessible and in motion across compute, storage, and networking,” Clarke noted. It is much more than assembling and delivering components; AI deployments require significant engineering, design, and deployment expertise. Some customer engagements, in fact, require upwards of 50 unique designs as enterprises optimize for workload performance, power, cooling and the data center environment, he claimed.
Enterprises want new servers with more cores, more dynamic random-access memory (DRAM), and more storage. However, the constraints remain the same: “DRAM, DRAM, DRAM, followed by NAND, NAND, NAND [flash memory],” Clarke said. There are “spotty” CPU and disk drive shortages, and constraints all the way down the supply chain, from microcontrollers to drives to transistors.
Large enterprises and multinational corporations across the globe “would prefer to have products now if we had the supply,” he said. “We are supply constrained in the sense of what we can build in any given quarter.”
This has led Dell to plan accordingly and optimize configurations with what “bits and bytes” they do have coming in to maximize outputs, with a focus on “getting it out the door,” Clarke said. There are associated lead times that the company is working through, but they’ve been able to “realize greater shipments.”
“We’ll continue to focus on trying to get more supply, and take the supply we have and optimize the output,” he said.
Reflecting increased need for storage as enterprises prep, manage, and protect huge volumes of data, Dell has also seen strong growth across its PowerFlex, PowerStore, PowerProtect, and PowerVault products.
“Demand remains broad based; enterprises continue to modernize their storage environments as data growth increases the importance of keeping data available and secure,” Clarke said.
How customers respond to shortages
Clarke acknowledged that modernization is driving higher core counts, more DRAM, and more storage. Those configurations “cost more than they did last quarter, and the quarter before, and the quarter before.”
Customers are adjusting to these price increases, he noted, deferring purchases because they are unable to sufficiently flex existing budget dollars. In other cases, enterprises are placing orders further in advance to ensure they have access to constrained supplies. “Large, sophisticated customers are acting, first and foremost,” Clarke said. Some are collaboratively planning with Dell to gain a view of their needs further into the future.
“That is a new phenomenon,” he said. “We are working through this demand environment that’s well ahead of supply, helping customers manage.”
Brands like Snickers, M&M’s, and Twix are familiar to most consumers, but Mars Inc. doesn’t just produce snacks. The family-owned company, with a revenue of approximately $65 billion, is also one of the largest manufacturers of pet food and ready meals, and its more than 100 production facilities operate around the clock. Of course, this places considerable demands on its IT.
“Our team must ensure that every system, including production lines, runs at maximum performance so we can continuously deliver the products and services our customers value,” says Luciano Batista, the company’s VP of enterprise services delivery.
However, Batista and his team realized that the existing data infrastructure could no longer reliably support operations, especially during peak periods such as Halloween and the pre-Christmas shopping season. So with the support of hybrid, multi-cloud data storage service Everpure, Mars is rebuilding its data and IT infrastructure.
“The Everpure platform met all our requirements,” says Batista. “It’s a scalable platform that futureproofs our operations and integrates seamlessly with our hybrid cloud infrastructure.”
Unified storage environment
Mars initially consolidated its complex network of storage systems for business-critical databases like Oracle and applications like SAP onto a single Everpure Flash Array system. These software-defined, all-flash storage arrays are available in versions for different workloads, and typical use cases include databases, virtualized environments, SAP applications, and AI and analytics applications.
Mars has since expanded its flash array infrastructure and now supports mixed workloads, including VMware, Windows, and Linux in areas of production, development, and quality assurance. It also uses Everpure Flash Blade as the basis for the global SAP file system. And while Flash Array is optimized for structured data, the scale-out systems of the Flash Blade series are designed for unstructured information.
“At peak times, Everpure supports up to 300,000 IOPS without any performance degradation,” says Lincoln Silva, product owner for Linux and on-prem storage at Mars. From his perspective, another point speaks favorably of the new platform in that he estimates his team saves approximately three months of planning time thanks to the Evergreen subscription model. This is because the vendor provides regular updates for the storage platform’s hardware and software. As a result, Mars’ IT professionals can focus on more critical tasks.
Basis for hybrid cloud strategy
Mars also works with choice vendors to implement its approach to cloud. Dedicated local storage capabilities, for instance, are being integrated into Microsoft Azure cloud workloads, which simplifies restore processes and increases resilience.
Snapshots from the local environment can be replicated to the cloud, too. Recovery point objectives (RPEs) of four to 24 hours are available, depending on system priority. “Our success is also the success of our partners,” Batista says. “We embrace a spirit of reciprocity to get the most out of our collaboration.”
The hybrid cloud allows Mars to run VMware workloads and extend its IT infrastructure to the cloud as needed. And the company aims to expand its use of cloud-native applications via Microsoft Azure at a lower cost.
“We’re seeing a data reduction ratio of 18 to one. That’s nine times the expected compression rate,” Batista adds. “This puts us on track to save up to 50% on cloud storage costs. We can now work more efficiently and make better decisions thanks to intelligent solutions and automation.”
Fewer racks and lower power consumption
By consolidating on the flash platform, Mars has also reduced the space requirements and power consumption of its data centers so they only use one sixth of the power, and the number of racks has decreased significantly.
“We’re shaping a sustainable future by changing the way we work,” says Batista. “The decisions we make today will impact the world we leave behind, and Everpure aligns with our commitment to thinking in generations, not just business quarters.”
Microsoft is betting that the integration of HorizonDB, the cloud-native PostgreSQL alternative it is developing, with Azure will attract more enterprise AI and agentic workloads to its cloud services.
Enterprises may not be willing to take that bet.
It’s been nine months since Microsoft unveiled HorizonDB, but the service remains in public preview with no announced general availability date. Why put AI projects on hold waiting for HorizonDB to arrive, when AWS, Google, Databricks, Snowflake, and others already have production-ready PostgreSQL services positioned for the same AI workloads that Microsoft says it is building HorizonDB to handle?
AWS has had the longest head start. Aurora PostgreSQL became generally available in 2017 and has since evolved from a cloud-native PostgreSQL database into an AI-ready service with vector search and integrations with Amazon Bedrock. Similarly, Google’s AlloyDB, which followed in 2022, now includes AlloyDB AI with vector search, embeddings and model interaction for generative AI and agentic applications.
Databricks and Snowflake, too, have their own platform-centric services in the form of Lakebase, which became generally available on AWS and Azure this year, and Snowflake Postgres, which was made generally available in February 2026.
As the latecomer, when Microsoft pitched HorizonDB at Ignite in November 2025 it talked up its new architectural approach to cloud-native PostgreSQL, built around disaggregated compute and storage and a database-as-log design. The hyperscaler also positioned native vector search and deep integration with Foundry and Fabric as key differentiators for AI-heavy workloads.
No reason to wait
Those architectural differences may not be compelling enough for CIOs to wait for HorizonDB to become generally available, though.
“Most enterprises with urgent needs will not wait. A long preview window creates uncertainty around SLAs, pricing, operational maturity, and roadmap confidence,” said David Linthicum, an independent cloud consultant.
And, said Stephanie Walter, practice lead of AI stack at Hyperframe Research, enterprises cannot build mission-critical production plans around an undefined GA date, regional footprint or support commitment.
Given the difficulty of unwinding a poor database choice, enterprises will approach unknown quantities with caution.
“Database platforms eventually become sticky control points. Once the database is connected to the rest of the application, analytics, AI, and governance stack, switching becomes a business transformation rather than just an infrastructure swap,” said Michael Ni, principal analyst at Constellation Research.
In the case of a cloud database, there’s also the unwelcome possibility of “huge egress fees” in case of change, said Bradley Shimmin, lead of the data and analytics practice at The Futurum Group.
All that uncertainty is likely to lead enterprises to restrict HorizonDB to experimental use cases for now, Shimmin added.
Performance anxiety
Analysts also questioned whether HorizonDB’s technical differences will show up in performance benchmarks.
Microsoft has said HorizonDB can deliver up to three times the throughput of open-source PostgreSQL, but makes no comparisons with rival offerings such as Aurora or AlloyDB that it will compete with, Walter said.
The bigger question, according to Igor Ikonnikov, advisory fellow at Info-Tech Research Group, is whether those performance advantages, still largely on paper, translate into a meaningful difference in production.
“A database with a better compute benchmark can still be more expensive once resilience and ecosystem costs are included,” Ikonnikov said.
The economics also point to another HorizonDB limitation, particularly for workloads that are not continuously running, said Advait Patel, senior site reliability engineer at Broadcom.
HorizonDB currently uses provisioned compute rather than a serverless, scale-to-zero model, meaning customers continue to incur compute charges while an instance is provisioned, even if its workload is intermittent or idle, Patel said.
There are developer considerations too.
HorizonDB’s PostgreSQL compatibility does not necessarily mean every existing PostgreSQL application will move cleanly as in its current form the database supports only an approved set of PostgreSQL extensions rather than arbitrary ones, Walter said.
Who should wait?
For enterprises already deeply invested in Microsoft’s Azure ecosystem, those limitations may not be enough to rule out waiting for HorizonDB, Patel said: The chance to integrate the database with AI services and the wider Microsoft stack may outweigh immediate availability, he added.
That calculus also reflects how enterprises typically make database decisions in the first place: not by comparing databases in isolation, but by weighing how well they fit into the broader technology stack, including the cloud platform they have standardized on, Ikonnikov said.
For Azure shops, the choice may therefore be less about moving an existing workload away from Aurora or AlloyDB and more about whether a new Azure workload should start on Azure Database for PostgreSQL today or wait for HorizonDB when it becomes available, he said.
That may be an open question for some enterprises, said Devin Pratt, research director at IDC. “Plenty of organizations are still mid-decision, not locked in,” he said.
Microsoft finally offers a timeframe
Microsoft still won’t say exactly when HorizonDB will launch, with Shireesh Thota, corporate vice president for Azure Databases at Microsoft, saying only, “General availability for Azure HorizonDB is currently targeted for the second half of 2026.”
That narrows it down to a period of a little over four months, including Microsoft’s FabCon and Ignite conferences — an eternity in AI.
 Entrar





 Source: FBI[/caption]