Entrar

VerifiedIDA | Making LLM-Driven Reverse Engineering Inspectable, Continuable and Reusable
Executive Summary
- SentinelLABS evaluated how frontier models reverse engineer binaries and annotate disassembler databases, finding recurring problems with inaccurate labels and incomplete analysis.
- To improve performance, we developed and tested a standard for LLM-driven reverse engineering that keeps annotations tied to evidence, verifies database changes, preserves project state, and requires review of the model’s work.
- We open-sourced VerifiedIDA, a reference implementation that applies the standard to autonomous reverse engineering in IDA Pro.
- Despite the growing capabilities of new models, our research shows that scaling reverse engineering requires that the analysis they produce remain inspectable, continuable, and reusable by humans, other models, and downstream security workflows.
Overview
The use of large language models (LLMs) for reverse engineering creates the possibility of examining binaries at a scale and speed exceeding that of manual analysis. It also makes reverse engineering accessible to those without specialized expertise in the discipline. The combination of scale, speed, and accessibility introduces a major shift across multiple domains. In cybersecurity, for example, defenders can analyze larger volumes of malware in less time, while attackers can misuse the same capability to considerably accelerate and scale vulnerability research and exploit development, shortening the time to exploitation and increasing the volume of intrusions.
As part of our broader innovation initiative for applying AI to automate and scale up defense workflows to keep up with an increasingly fast and widespread threat landscape, this work contributes to making LLM-driven reverse engineering inspectable, continuable, and reusable. These properties are important when reverse engineering output is used as part of cyber defense operations, such as incident response, detection development, or threat hunting, where analysts act on this output, share it with other stakeholders, and use it as input to other tools and workflows. This requires the ability to inspect the evidence behind an LLM's conclusions to verify them, have another analyst or model continue the work from where the LLM stopped, and reuse results coupled with the code and data they describe.
To this end, we focus on LLM-driven reverse engineering whose output is an annotated disassembler database, such as an IDA Pro, Ghidra, or Binary Ninja database. In contrast to a textual report, which reduces the analysis to a prose snapshot of the model's conclusions, detached from the code that supports them, an annotated database records findings directly on the disassembled code and data, as labels, types, data structures, and comments.
As a result, an analyst can verify each conclusion against the code and data it describes. When the database is shared with other stakeholders, recipients get every annotation, not only the findings a report would contain, and can verify and use the parts they need. In addition, another analyst or LLM can continue the analysis from the existing annotations in the database or correct them if necessary, rather than interpreting a prose report and locating the code and data each conclusion refers to. Other tools and workflows can also work directly with the findings and the code they apply to, for example, to generate YARA rules that target functions identified as implementing specific capabilities, or to parse configuration data using recovered data structures.
However, an annotated database provides these benefits only if its annotations are accurate and complete, which LLMs do not guarantee. To understand these limitations in practice, we conducted evaluation studies in which LLMs analyzed binaries and annotated IDA databases without safeguards for the accuracy or completeness of their work.
We first present the results of these studies, which show that models produced inaccurate labels, left some findings unrecorded, lost track of unfinished work, and stopped the analysis early. Full model specifics are provided in the section below.
Based on these findings, we propose a standard for LLM-driven reverse engineering that annotates disassembler databases. Under the standard, each annotation must be confirmed as recorded in the database and traceable to documented evidence against which its accuracy can be verified, outstanding work stays tracked until it is resolved, and an independent review assesses the accuracy of the annotations and identifies work left undone, returning its findings to the LLM that reverse engineers the binary for correction.
Finally, we present VerifiedIDA, a harness that serves as a preliminary implementation of the standard by mediating the LLM's access to an IDA database. VerifiedIDA is released as an open-source project, together with the specification of the standard and a user guide.
Evaluation Studies | LLM-Driven Reverse Engineering Without Safeguards
The goal of our evaluation studies was to identify common challenges with model-led reverse engineering where the model had to annotate a disassembler database using basic tooling. A detailed comparison of how models perform, individually or by vendor or tier, was not our focus.
We used proprietary models from Anthropic and OpenAI in addition to open-source models to reverse engineer binaries of varying size, both malicious and legitimate. The majority of our testing presented here used GPT-5.6 Sol. The models worked through a simple harness, in which an LLM analyzes a binary autonomously, without any human or automated feedback and with access only to basic reverse engineering capabilities. The harness provides only general instructions and a fixed set of tools for viewing disassembled and decompiled code, following cross-references, searching the binary, and writing labels, types, and comments, such as free-text descriptions of functions, into an IDA database.
The full reasoning of Anthropic and OpenAI models is not available through their APIs, so we could not directly observe how they make decisions while reverse engineering a binary. Instead, we logged each analysis step by step in what we refer to as an LLM log, recording the tools the model called, the code it retrieved, its intermediate notes and planned next steps, and the edits it made to the database. An LLM log may show, for example, the model retrieving the pseudocode of a function, following its cross-references, and then labeling the function in the database. This allowed us to reconstruct what the model retrieved, what it based each annotation on, and how it acted on that information.
To illustrate some of the observations we discuss next, we present two case studies in the Case Studies section, each examining in detail how GPT-5.6 Sol performed a routine reverse engineering task. In both, the model reverse engineered a sample of ComRAT (SHA-1 hash: 0139818441431c72a1935e7f740a1cc458a63452), a backdoor attributed to the Russian APT group Turla. Case Study #1 covers the recovery of a data structure passed as a parameter to two ComRAT functions, whereas Case Study #2 covers the analysis of a single ComRAT function's behavior.
Structured Work Grounded in Evidence
We observed that the LLMs took a sound, methodical approach to reverse engineering tasks. For example, when labeling a variable or a function, they typically started with a broad analysis of the pseudocode or disassembly and then moved to targeted exploration, analyzing how the variable or function is used across the binary to determine the variable’s role or the function’s primary operation, which is what the label should describe.
The models also largely avoided fabrication. For example, when a model could not establish the role or type of a variable, it typically applied a generic label, such as unknown, or a generic data type, such as void, rather than inventing one the code did not support.
In addition, the LLMs made effective use of authoritative information relevant to the analysis, such as the public documentation of Windows API functions, which is highly likely present in their training data. For example, when a variable was passed to a Windows API function, they typed it based on the function's documented parameter types, and when a function called Windows API functions, they took the documented behavior of these API functions into account when determining the primary operation of the calling function.
Inaccurate and Incomplete Disassembler Databases
Alongside the strengths discussed above, we observed four major, recurring problems. These problems undermine the purpose of an annotated database as the primary output of LLM-driven reverse engineering, which is to serve as an accurate and complete binary-grounded foundation for any downstream use.
Accuracy of labels
Some labels the LLMs applied to variables and functions did not accurately describe the variables' roles or the functions' primary operations. This matters because analysts often rely on labels to navigate an annotated disassembler database. Inaccurate labels therefore have consequences for anyone who uses an annotated disassembler database, human or model, whether to continue an analysis or to draw conclusions from it. For example, an ambiguous label may lead an analyst to redo work that is already done, while an imprecise one may draw attention away from binary behavior that matters.
Inaccurate labels also misrepresent the binary under analysis, and any conclusion drawn from the database carries that misrepresentation forward. In addition, the inaccuracy of a label is not apparent from the database itself, since a label says nothing about how well it is supported. An inaccurate label is therefore either taken at face value, with the consequences that may bring, or caught only at the cost of redoing the analysis whose conclusion it was meant to record.
Capture of findings
The models repeatedly established findings during the analysis without recording them as annotations in the databases, that is, they did not reliably translate reverse engineering findings into database annotations. These findings did not survive the analysis sessions, and the effort behind them was effectively lost, leaving the databases incomplete.
Continuity of work
As the analyses progressed, the models often lost track of unfinished work, which we suspect is primarily due to context compaction, the condensing of the models' earlier output and tool results to fit their context windows. Steps they had planned were dropped, leaving the parts of the binary they targeted unanalyzed and without annotations in the databases.
Completeness of analysis
The LLMs often stopped exploring before examining all the code relevant to what they were analyzing. For example, having settled on a function's primary operation, an LLM labeled the function without exploring all of the function's callees, some of which implement additional capabilities. These capabilities remained unidentified, and the function's label did not express them.
Reverse Engineering Standard
The four problems we observed are not variations of a single failure. Each points to a responsibility that cannot be left to the model alone.
Models are not infallible, so no system can guarantee that every label they apply is accurate. A system can, however, keep the evidence behind each annotation, so an inaccurate label can be found and corrected without redoing the analysis it was meant to record. It can confirm which findings reach the database, carry unfinished work beyond the model's context, and check whether the code behind a conclusion was examined.
These checks fall into two categories. Mechanical checks can be made without interpreting the code: whether a requested change persisted, or whether a function's callees were inspected before the function was labeled, as in Case Study #2. Semantic checks require review on whether a label describes a function's primary operation, or whether the analysis establishes how two capabilities relate.
This is the division of labor at the center of our standard: the model makes the analytical judgments, and the system around it preserves the evidence, maintains the state of the project, and enforces follow-through. We formalize this into four requirements.
Problem | Requirement | What the system must establish |
Accuracy of labels | Attributable evidence | What each annotation is based on, so its accuracy can be verified |
Capture of findings | Verified changes | What was requested, what was recorded, and whether it persisted |
Continuity of work | Preserved project state | What is known, what has been done, and what is planned next |
Completeness of analysis | Enforceable scope and review | What must be examined, and what remains unresolved |
Attributable evidence. Every annotation must be traceable to the evidence the model retrieved to support it, identified by the binary and the state of the database it came from. Evidence that no longer reflects the current database must not support new annotations.
Verified changes. The system must check what each requested change recorded in the database and whether it persisted. If a change fails, the accepted database must stay intact, and the model must receive feedback it can act on. This matters most for type changes. A recovered structure that cannot be applied cleanly, or that alters parts of the database the model did not intend to change, can be detected and rejected mechanically before it affects how other code decompiles.
Preserved project state. Accepted annotations, the history of changes, the working summary of the binary, and the list of pending tasks must be stored outside the model's context. The analysis can then be resumed after context compaction, an interruption, or a switch to another binary, by the same model, a different one, or a human analyst.
Enforceable scope and review. An independent reviewer must be able to challenge the accuracy of annotations and identify work left undone. Its findings must go back to the investigating model and stay tracked until each is corrected, rejected with evidence, or recorded as unresolved for a human to pick up.
Our proposed standard is the floor for LLM-driven reverse engineering. It does not make a model's analysis correct, and it does not prescribe how a model should reverse engineer a binary. Many tools already use models for reverse engineering in their own ways, and more will follow. Verification is essential, but it establishes only what was recorded, not whether it is right, and review by another model or by an expert human can still miss errors. What the standard ensures is that the model's conclusions remain tied to evidence that can be revisited, and that its mistakes are identifiable rather than hidden. The standard is also independent of a particular disassembler. We publish it as an interface specification alongside our reference implementation for IDA Pro, which we describe next.
The VerifiedIDA Harness
VerifiedIDA is our reference implementation of the standard. We built it for IDA Pro first because it is the disassembler our team works with most. The model chooses what to investigate, inspects code, and proposes annotations. VerifiedIDA acts as the host and mediates every access to the IDA database: it identifies the target of each request, requires current evidence, applies edits to a candidate copy of the database, checks the result, and records each operation. It maintains three records:
- IDA databases, which hold the accepted labels, comments, types, interfaces, and relationships, one per binary, including embedded binaries.
- A SQLite ledger, which holds inspections, operations, verification results, database revisions, and tracked work.
- A project notebook, which holds the model's current understanding, uncertainties, and next actions, along with a journal of how they changed.
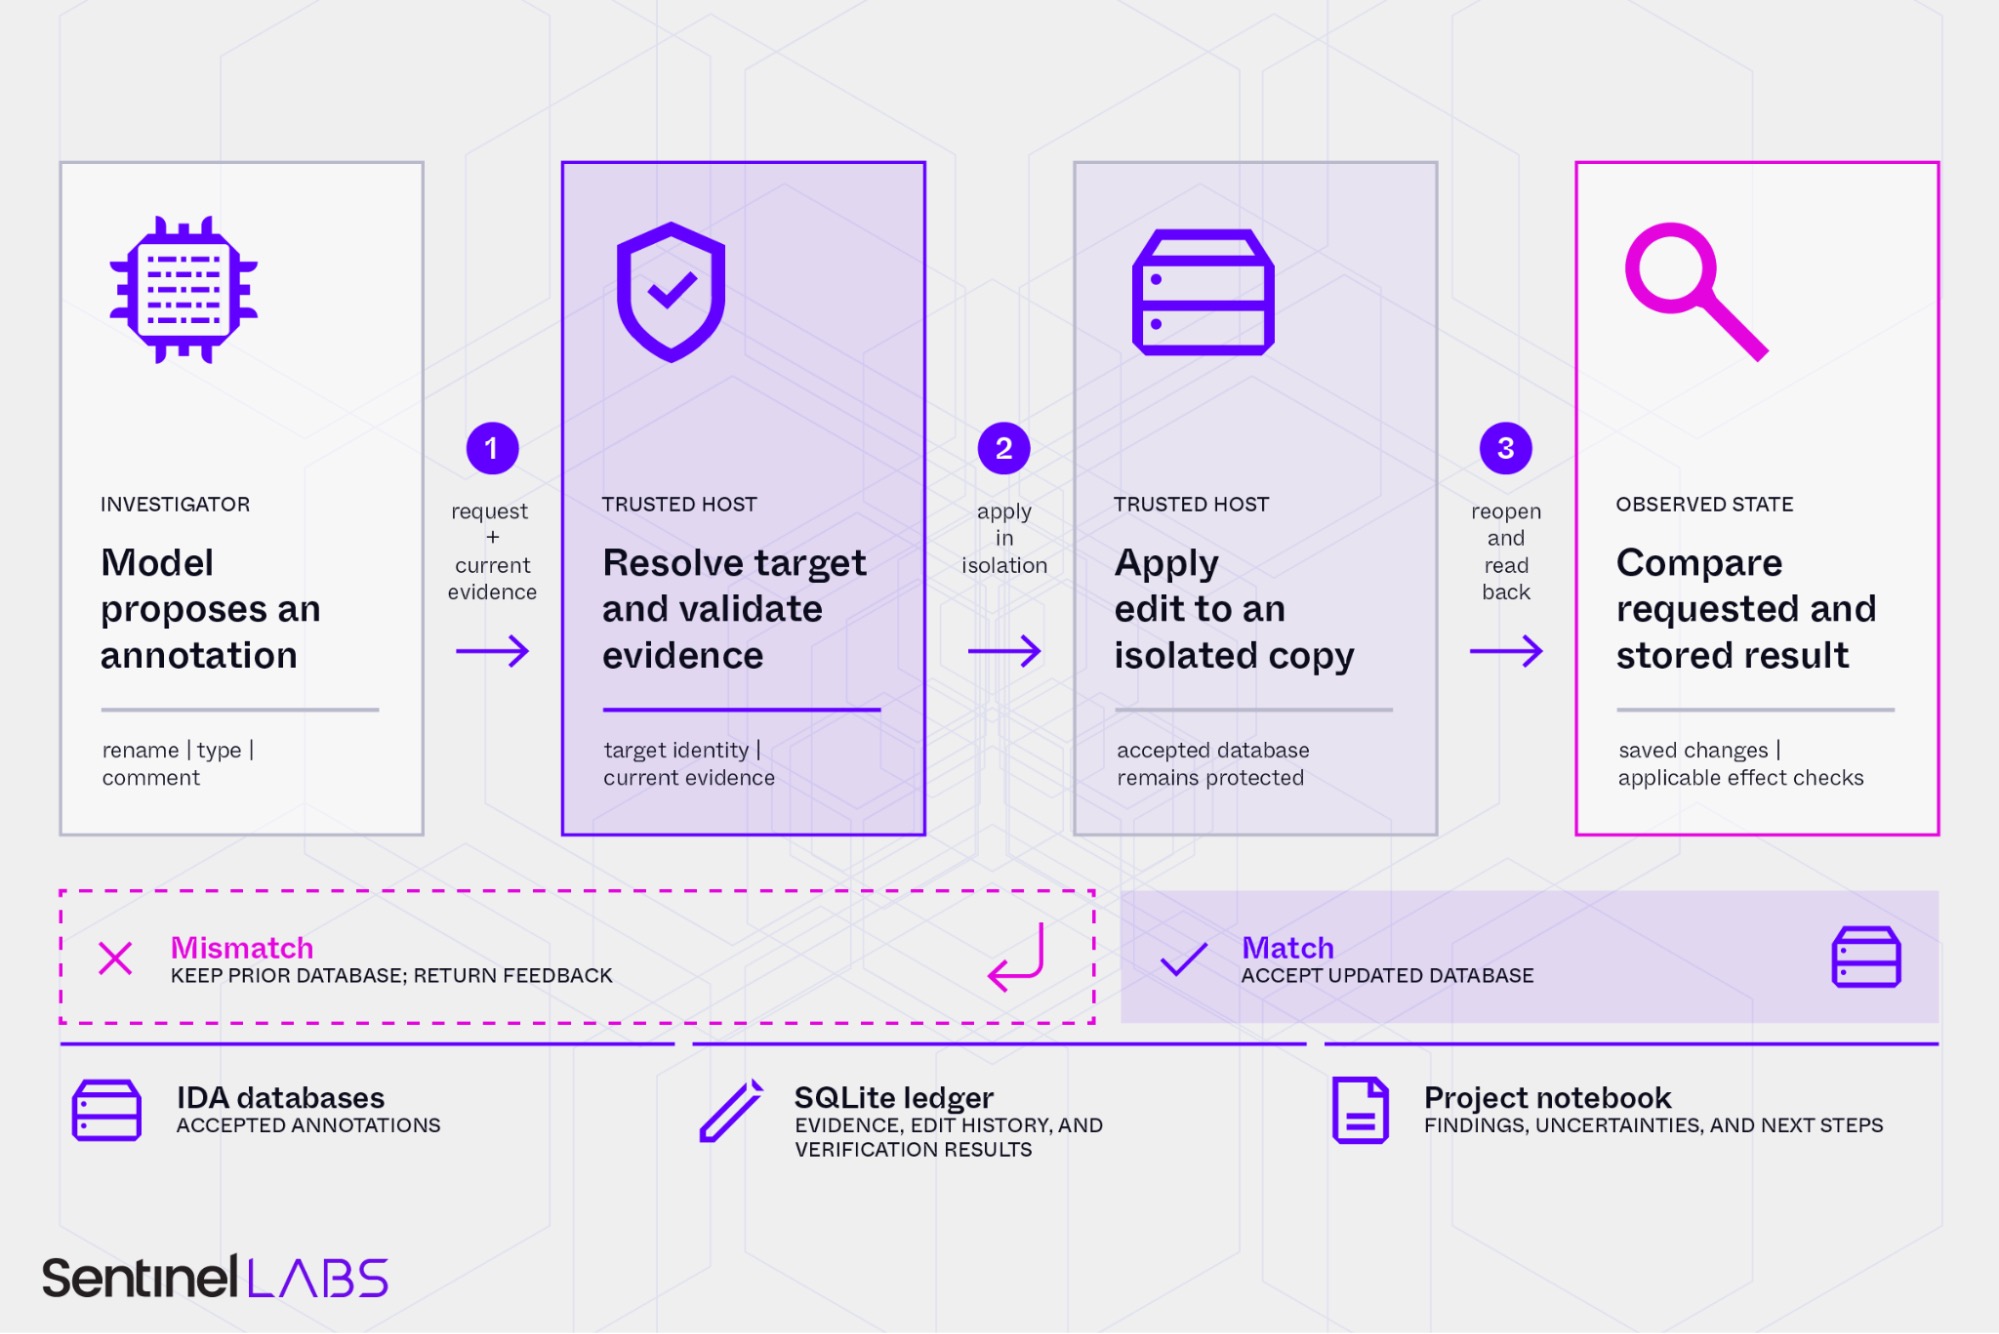
Attributable evidence. Every edit must cite evidence the host recorded for the current target and database revision. Evidence is identified by binary and revision rather than by address alone, because a binary and the binaries embedded in it can use the same addresses. If the database has changed since the model inspected the code, the host rejects the edit and explains how to obtain current evidence. Model inferences and historical evidence are labeled as such. A reviewer can start from any annotation, find the operation that introduced it in the ledger, and examine the code the model was shown when it made it.
Verified changes. The host applies each edit to an isolated candidate database, reads the result back through a separate path, and checks it before the candidate becomes the accepted database. Type and prototype edits also receive a comparison of the affected IDA state, and unrelated changes lead to rejection. If an edit fails, the accepted database is left unchanged, and the model receives the target, the failed stage, the requested and observed state, and a recovery direction. Checkpoints reopen the database in a fresh IDA process to confirm that accepted changes persisted.
Feedback also targets the capture problem directly. After an edit, the host flags incomplete annotations, such as a renamed function without a behavior comment or parameters that retain generated names, and reports where a newly created type is not yet applied. In our worked example, based on the ComRAT structure from Case Study #1, the feedback reported that the structure the model had created was declared but not used anywhere, and the model went on to apply it to the function's parameter.
Preserved project state. The notebook records where the investigation stands, and its current-state sections are rewritten as the model's understanding changes. After context compaction, the model is given its current instructions and the recorded project state, and any further edit still requires fresh evidence from IDA. When the model follows an embedded binary, the host records the child's bytes, how it was extracted, and its link to the parent, and opens a separate database for it. Before switching, we require the model to record what it has established in the parent and how the parent uses the child, so it knows where to return.
Enforceable scope and review. Independent review starts with the host building an inventory of annotations and possible gaps. Reviewer models then examine individual claims and the overall explanation of the program, with read-only access to disposable copies of the databases. The host validates their findings and freezes the scope of required corrections. The investigating model then resumes and works through one finding at a time: it can apply the correction, revise it, reject it with evidence, defer it, or request a specific follow-up. It then checks that the accepted review conclusions agree with the annotations, and any remaining disagreement blocks completion. The final report states what was verified, what remains unresolved, and whether the completion policy was met.
Coverage mode. We reran the Case Study #2 function with an experimental call-flow mode enabled. In six earlier GPT-5.6 Sol runs, none had opened sub_180081450, and the four that annotated the parent all omitted forwarded-export handling.
In the new run, Sol began from a clean database and was not told which callee mattered. Once it committed a claim about sub_180077C10, the mode listed the function's 20 direct internal callees and held that claim open until each had a recorded outcome. Sol opened sub_180081450, identified it as the recursive resolver for forwarded exports, and confirmed a parent comment that separates local export-table parsing from the recursion it delegates.
A repeat under a revised policy reached the same result across all 20 callees, and every edit survived a fresh-process reload. The mode follows direct calls only. An early attempt to apply it across the whole project generated 265 required nodes for eight edits, so we reserve it for selected claims.
Conclusion
Over the past year we’ve watched the infosec community grapple with the rapid adoption of AI tools and increased automation. It is clear that AI models can now reverse engineer binaries at a scale no team of analysts can match. As the volume of analysis the models produce grows, it creates a widening gap in our ability to understand how decisions were reached and what evidence they were based on. After all, a model's labels, types, and descriptions are only as useful as an analyst's ability to confirm them, correct them, and build on them.
A database makes this level of inspection possible in a way that a report cannot because each conclusion can be tied to the code it describes. This allows a person (or another model) to easily continue the work or incorporate the findings into downstream detection and hunting workflows.
LLMs give us the opportunity to automate more security analysis but only insofar as the work they produce remains understandable. Scaling the analysis without also scaling our ability to inspect it replaces one bottleneck with another.
Our evaluation studies showed that models alone do not reliably produce attestable databases. Labels drift from what the code does, findings stay in logs, planned work disappears, and analysis stops before the relevant code has been read. The standard and VerifiedIDA respond by leaving the analytical judgment with the model and giving the system around it the job of keeping that judgment checkable. Our rerun of Case Study #2 shows the difference: the helper that six earlier runs skipped became work the model could not leave unfinished.
We are releasing both as a starting point. The requirements describe the minimum a model-driven workflow should provide, and our implementation covers a single disassembler. We invite the community to test the specification against their own tooling, build adapters for Ghidra and Binary Ninja, and push back on requirements that do not hold up. Where sharing is permitted, we also encourage researchers to publish annotated projects alongside their reports, so others can extend an analysis instead of repeating it.
This paper complements research we presented at LABScon 2026.
Case Studies
#1 | Recovering a Data Structure
Recovering data structures is routine reverse engineering work. At the memory level, a structure is a base address with fields at fixed offsets from it, where a field may be a complex data type itself. If the binary carries no debug symbols, it does not declare field offsets, types, and names, and these have to be recovered through analysis.
Two ComRAT functions, with the IDA default names sub_18002C770 and sub_18002CDA0, receive a pointer to a data structure as their parameter. IDA types these parameters as an integer.
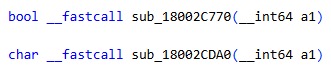
The LLM typed the parameters as a pointer to a data structure, which it declared as follows.
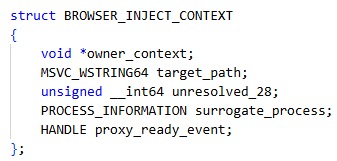
The LLM approached the recovery of the structure in two stages. First, from the pseudocode of sub_18002C770, sub_18002CDA0, and the functions they invoke, it observed references to specific offsets from the function parameter value (the structure base address), concluding that the parameter is a pointer to a structure. It then widened the analysis to the rest of ComRAT's code, looking for references to the structure's fields wherever they occur. For each field it identified, it analyzed the context in which the field is used to propose a label, type, and size.
This enabled the LLM to recover the full set of structure fields, and from their sizes the correct total size of the structure itself.
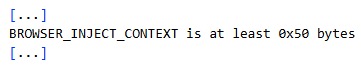
The strongest evidence the LLM had for typing a field was its use as a parameter to a Windows API function. Many Windows API functions are documented publicly and their parameter sets are relatively stable, so the types of these parameters are highly likely present in the model's training data. IDA may also expose these types in the pseudocode provided to the LLM since it auto-defines parameter types for many of these functions. The model could therefore determine field types from authoritative sources.
For example, the LLM observed that a pointer to the structure field at offset 0x30 is passed as the tenth parameter of CreateProcessW. Microsoft documents the type of this parameter as a pointer to a PROCESS_INFORMATION structure, and IDA's pseudocode shows the same type. The LLM used this information to correctly type the field as PROCESS_INFORMATION.
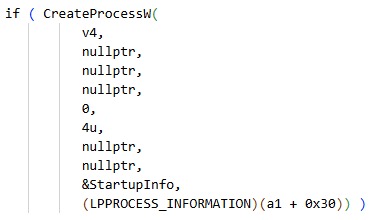
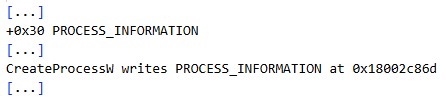
The LLM did not produce annotations that its analysis did not support. For example, it found no use of the field at offset 0x28 within the functions under analysis and did not label the field after an invented role. Instead, it flagged the finding and decided to explore ComRAT's code further to establish the field's role. It found no use of the field anywhere in ComRAT and labeled it unresolved_28. Our own analysis confirms that the field is indeed never used.

However, several structure field and function labels produced by the LLM are inaccurate, since they do not describe what they should: the role a field plays in the code or the primary operation a function performs. For example, the LLM labeled the field at offset 0x28 unresolved_28, naming its own analytical state rather than the role of the field, or the lack thereof. The label is also ambiguous, because it does not distinguish a field that has not been examined from one that has been examined and found to be unused. In the case of this field, a name such as unused would be more appropriate.
The LLM also named the function sub_18002C770 PrepareSuspendedSurrogateProcess, although the function’s primary operation is the creation of a browser process in a suspended state. The LLM’s label does not indicate process creation at all, and Prepare suggests work that precedes a later step rather than the function’s primary operation. The LLM’s free-text description of the function (“Create the configured surrogate process before proxy injection”) shows that the model had identified the primary operation. The description leads with it and treats the injection that follows as context, whereas the label PrepareSuspendedSurrogateProcess keeps only the context and leaves out the process creation. A human reverse engineer would be more likely to apply a label such as CreateSuspendedBrowserProcess, which is more descriptive and more accurate in the context of the task.
Beyond inaccurate labels, the LLM did not record all of its findings in the IDA database, as the annotation of the structure field at offset 0x0 demonstrates. This field is a pointer to a structure, which holds data associated with a log writing mechanism, and the LLM logs show that the model identified the field as such.
However, in the IDA database, the LLM typed this field as a generic void pointer and labeled it owner_context rather than something closer to its role, such as LogWriter. The LLM had established the type and role of the field but did not translate these findings into IDA database annotations.
#2 | Analyzing a Function’s Behavior
A ComRAT function, with the IDA default name sub_180077C10, retrieves by name the address of a function exported by a dynamic link library (DLL) loaded in a remote process. If the export is forwarded to another DLL, the function resolves the address of the forwarded export recursively.
The LLM labeled this function ResolveRemoteExportAddress, correctly expressing its primary operation. As in Case Study #1, the strongest evidence the LLM relied on was the Windows API calls the function invokes. ResolveRemoteExportAddress also compares values against publicly documented constants, which provided the LLM with further authoritative evidence of the function’s operation.
For example, from the ReadProcessMemory calls, the LLM established that the function reads memory in the address space of a remote process. From the comparisons against the MZ (0x5A4D) and PE (0x4550) signature constants, the model determined that the function looks for Windows PE (Portable Executable) headers. Because the PE format is publicly documented and highly likely present in the model’s training data, the offsets into these headers visible in the pseudocode enabled the model to identify which of the DLL’s PE structures the function reads, such as its export directory and the array of names of its exported functions.
The LLM's free-text description, “Resolve an exported function address in a remote module from its PE export directory”, is accurate but incomplete, since it does not account for the resolution of forwarded exports.
If an export is forwarded to another DLL, sub_180077C10 (ResolveRemoteExportAddress) calls sub_180081450, which resolves the address of the forwarded export. Treating its understanding of sub_180077C10 as complete, the LLM labeled and described the function without exploring all of its callees, including sub_180081450. The capability implemented by sub_180081450 therefore remained unidentified.